

Som en erfaren fagperson som arbeider med API-er, mikrotjenester og en rekke fullstackteknologier, er jeg klar over hvor viktig effektiv ytelsesovervåking er. Gjennom årene har jeg erfart fordelene ved å bruke omfattende AIOps-plattformer, som disse alternativene til Dynatrace, som tilbyr rask feilsøking og funksjoner for analyse av rotårsaker.
Disse alternativene til Dynatrace er ikke bare brukervennlige, men imponerer også med robuste overvåkingsfunksjoner. Den sømløse integrasjonen med populære plattformer som Slack bidrar til bedre teamkommunikasjon i kritiske situasjoner. Med omfattende profilering og modulære løsninger tilgjengelig er du utstyrt med en kraftig overvåkingsplattform som kan løfte teknologistakken og den samlede produktiviteten.
Hva er Dynatrace?
Dynatrace er en plattform for overvåking av applikasjonsytelse (APM) som hjelper deg med å spore, analysere og optimalisere hvordan appene og infrastrukturen din kjører. Den brukes av DevOps-team, SRE-er og IT-ledere som trenger å oppdage problemer tidlig og forbedre brukeropplevelsen. Sanntidsovervåking, AI-drevne varsler og sporing fra ende til ende hjelper med å finne ytelsesproblemer, identifisere rotårsaker og holde systemene i stabil drift. Alt i alt hjelper Dynatrace teamet ditt med å ligge i forkant av ytelsesproblemer før de påvirker brukerne.
Hvorfor du kan stole på våre programvareanbefalinger
6,700+
Reviews
20
Industry experts
16+
Evaluation factors
14
Years
Teamet vårt har testet og anmeldt programvare siden 2012. Vi er selv teknologiledere, så vi vet hvor vanskelig og hvor viktig det er å velge riktig programvare.
I denne guiden har vi vurdert verktøyene gjennom praktisk testing og uavhengig research og gitt dem poeng ut fra våre utvelgelseskriterier.
Anmeldelsene våre bygger på vår egen redaksjonelle vurdering. De er ikke et salgsargument.
Ekspertanmeldere:
- Paulo Gardini MiguelTech Director
 Tim FisherVP of AI
 Gabriel RosasTech Lead & Software Architect
 Christhian GruhnTech Lead & Platform Architect

Sammenligningstabell for alternativer til Dynatrace
Denne sammenligningstabellen oppsummerer prisdetaljene for mine beste alternativer til Dynatrace:
Score legend (out of 5)
- Excellent4.5–5
- Good4–4.4
- Average3–3.9
- Below average2–2.9
- Poor1–1.9
Sorted by: Default
| Tool | Starting Price | Website | |||||||
|---|---|---|---|---|---|---|---|---|---|
Best for real-time error resolution | 3.3 out of 5 | 4 | 4 | 1 | 3 | 4 | 4 | $26/month Free plan + 14-day trial + free demo available | Website |
Best for extensive technology support | 3.3 out of 5 | 3 | 3 | 4 | 3 | 3 | 4 | $395/year Free plan + 30-day trial available | Website |
Best for diverse application environments | 3.2 out of 5 | 3 | 3 | 3 | 4 | 2 | 4 | $10/month Free plan + 30-day trial + demo available | Website |
Best for enterprise-level open-source monitoring | 3.3 out of 5 | 2 | 4 | 5 | 4 | 3 | 2 | $325/month Free plan + 5-day free trial + free demo available | Website |
Best for comprehensive IT infrastructure monitoring | Not rated | Not rated | 4 | 4 | 2 | 1 | 2 | $2,595 one-time 30-day free trial | Website |
Best for unified cloud service tracking | 4.2 out of 5 | 5 | 4 | 3 | 4 | 4 | 5 | $18/host/month Free plan + free trial available | Website |
Best for real-time business performance visibility | 3.2 out of 5 | 2 | 3 | 4 | 4 | 2 | 4 | $6/month 30-day free trial + free demo available | Website |
Best for querying telemetry in a unified data store | 4.0 out of 5 | 4 | 4 | 4 | 3 | 4 | 5 | $10/user/month Free plan + free demo available | Website |
Best for log management and security analytics | 3.5 out of 5 | 3 | 4 | 4 | 3 | 4 | 3 | Pricing upon request 14-day free trial | Website |
Best for large-scale data analysis and insights | 3.7 out of 5 | 4 | 3 | 4 | 4 | 3 | 4 | $15/host/month Free plan available | Website |


Anmeldelser av de beste alternativene til Dynatrace
Nedenfor finner du mine detaljerte sammendrag av de beste alternativene til Dynatrace som kom med på kortlisten. Anmeldelsene mine gir en detaljert gjennomgang av de viktigste funksjonene, fordelene og ulempene, integrasjonene og de ideelle bruksområdene for hvert verktøy, slik at du kan finne det som passer best for deg.
 Best for real-time error resolution
- Free plan + 14-day trial + free demo available
- From $26/month (billed annually)
Visit WebsiteCustomer Rating:4.5/5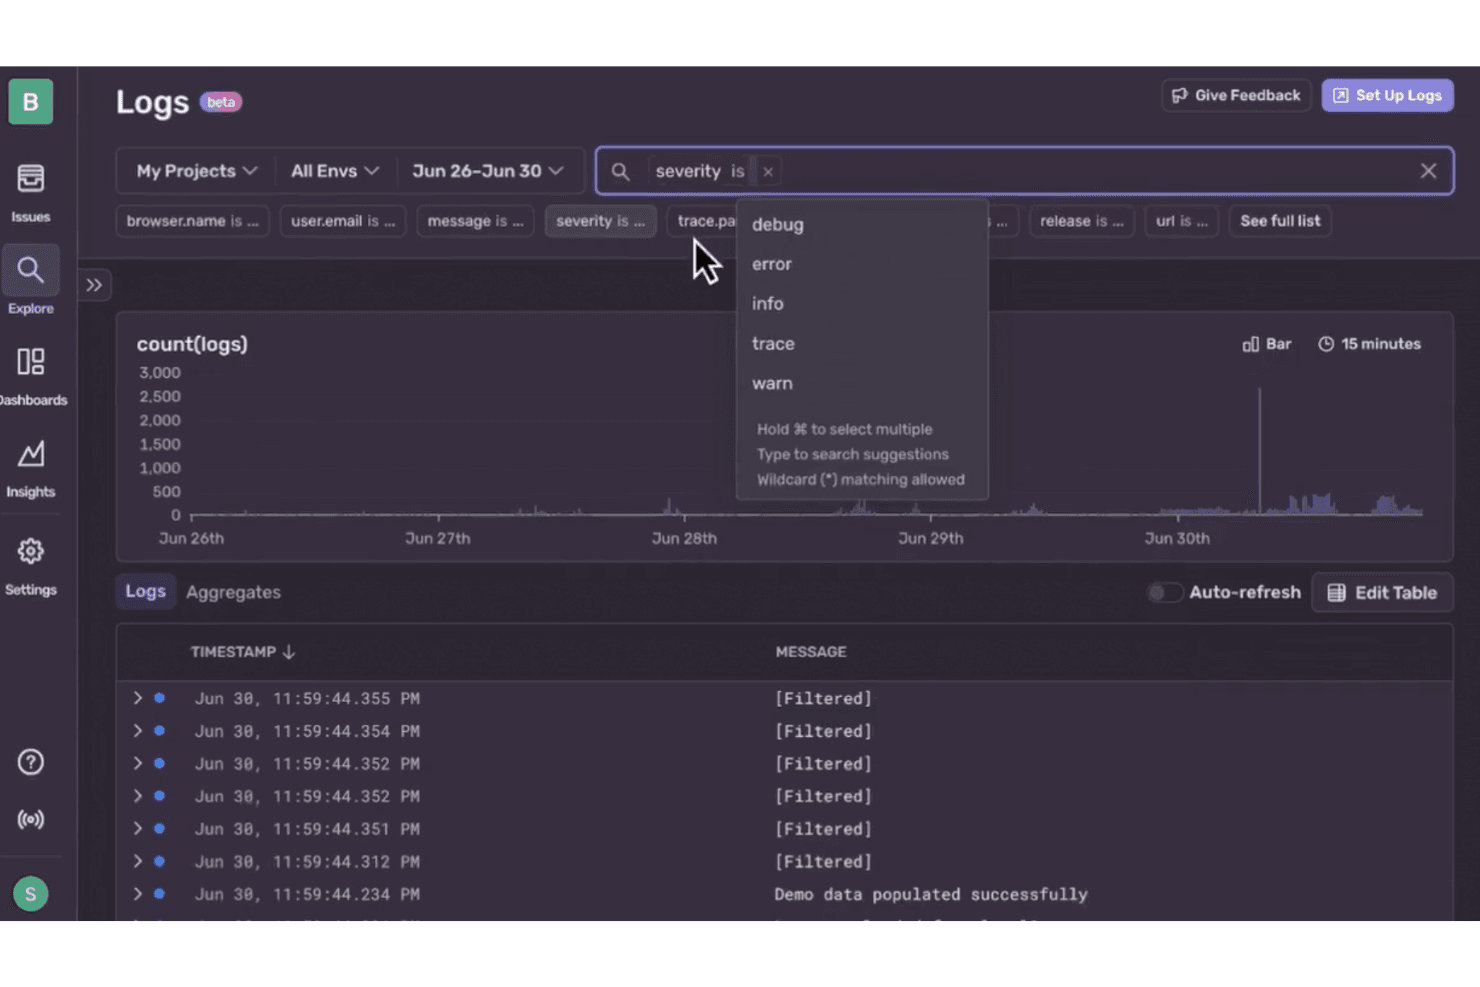
Sentry lets users filter logs by severity levels like debug, error, or warn. Sentry pairs application performance monitoring with error tracking, giving software teams a developer-focused alternative to Dynatrace for diagnosing issues across applications and services.
Who Is Sentry Best For?
Sentry is a good fit for software engineering and DevOps teams that need to identify and resolve production errors in real time.
Why I Picked Sentry
I picked Sentry as my choice for “Best for real-time error resolution” because it links production errors to stack traces and trace data, helping developers pinpoint failing code paths. Release health and regression tracking can also reveal when a deployment introduces new issues, so teams can prioritize fixes while monitoring application performance.
Sentry Key Features
- Continuous profiling: View function-level CPU profiles for supported applications.
- Web Vitals: Track browser metrics such as page load and interaction responsiveness.
- Database query monitoring: Inspect query duration and identify slow database operations.
- Custom instrumentation: Add measurements to monitor application-specific operations.
Sentry Integrations
Sentry offers integrations with GitHub, GitLab, Jira, Slack, Microsoft Teams, PagerDuty, Azure DevOps, Bitbucket, Vercel, and Opsgenie. Its integration platform and REST API support custom integrations.
Pros and Cons
Pros:
- Release tracking flags deployment regressions
- Correlates errors with traces and profiles
- Stack traces speed production debugging
Cons:
- Issue grouping and alerts can create noise
- No host or infrastructure monitoring
Learn more about Sentry: Best for extensive technology support
- Free plan + 30-day trial available
- From $395/year (billed annually)
Visit WebsiteCustomer Rating:4.3/5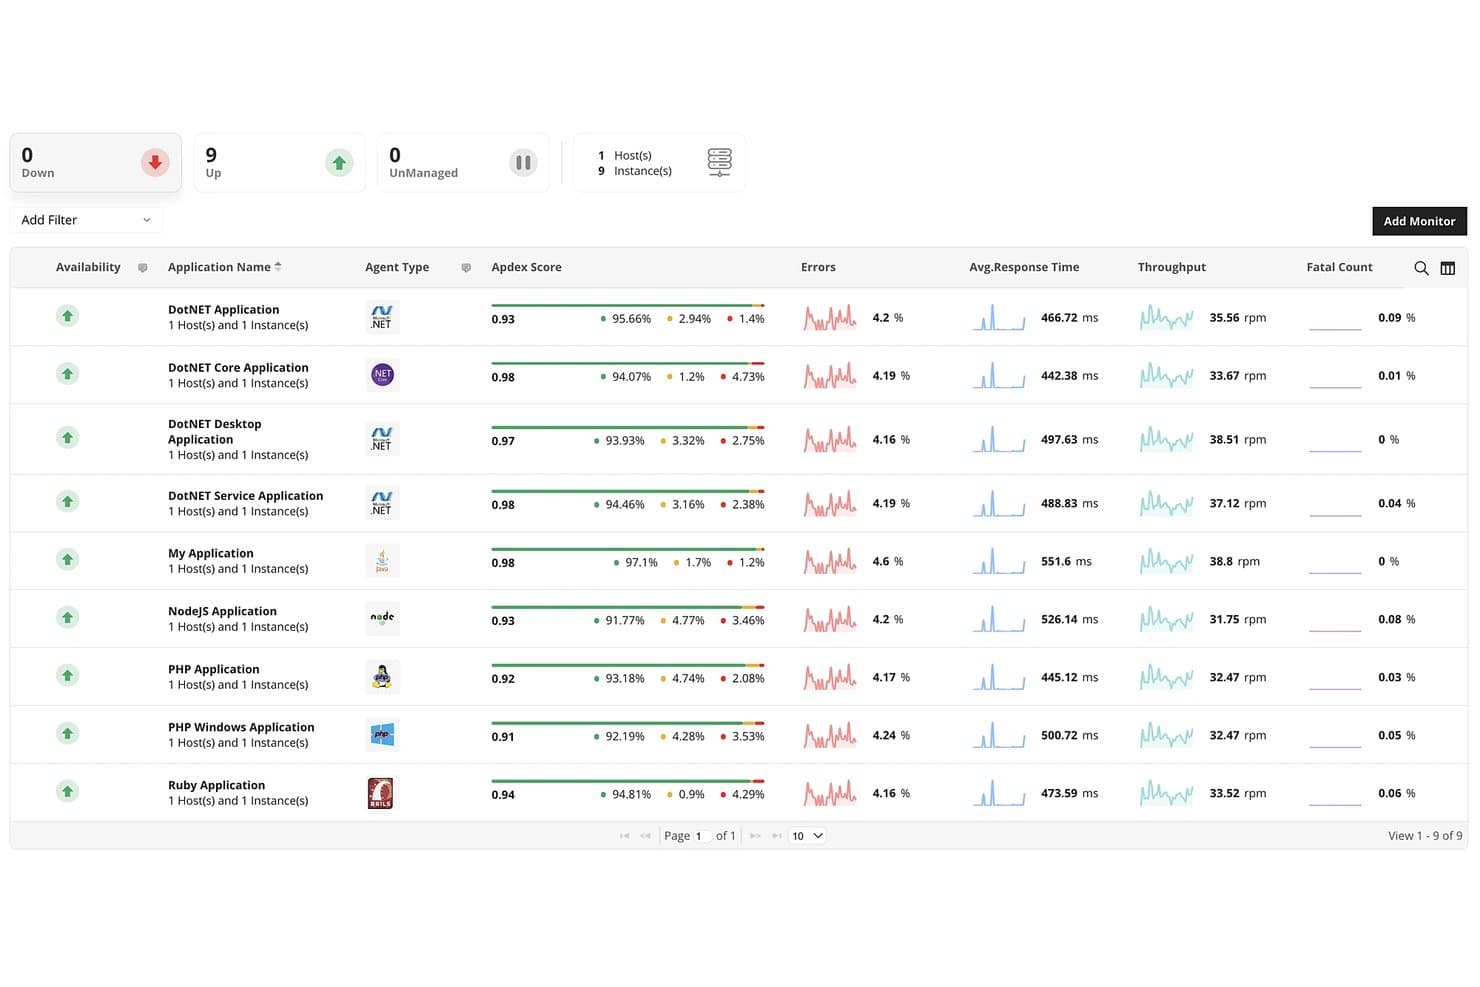
ManageEngine Applications Manager tracks app performance metrics across multiple instances. ManageEngine Applications Manager is an application performance monitoring platform for IT teams that need to trace slowdowns and outages across applications, servers, databases, and cloud services.
Who Is ManageEngine Applications Manager Best For?
IT operations teams overseeing diverse application and infrastructure environments across on-premises and cloud systems.
Why I Picked ManageEngine Applications Manager
I picked ManageEngine Applications Manager, “Best for extensive technology support,” because it monitors applications alongside servers, databases, and cloud services. I like that breadth for tracing a slow request across application and infrastructure tiers, then using transaction diagnostics to locate where latency builds.
ManageEngine Applications Manager Key Features
- Anomaly detection: Compare performance metrics with historical baselines or custom rules.
- Log management: Search, filter, and parse application and server logs in real time.
- Real user monitoring: Track page views, clicks, session duration, and Apdex scores from actual traffic.
- Capacity forecasting: Review trend reports and machine learning-powered forecasts to plan resource needs.
ManageEngine Applications Manager Integrations
ManageEngine Applications Manager documents integrations with ManageEngine ServiceDesk Plus, ManageEngine OpManager, Slack, and ServiceNow, plus Syslog-compatible SIEM platforms such as Splunk, Microsoft Sentinel, and ManageEngine Log360. It also provides REST APIs for connecting internal portals and third-party systems.
Pros and Cons
Pros:
- Broad legacy and hybrid-environment coverage
- Real-time alerts support proactive troubleshooting
- Monitors applications, databases, servers, and cloud
Cons:
- Less depth for cloud-native tracing
- Advanced threshold tuning takes setup time
Learn more about ManageEngine Applications Manager: Best for diverse application environments
- Free plan + 30-day trial + demo available
- From $10/month
Visit WebsiteCustomer Rating:4.7/5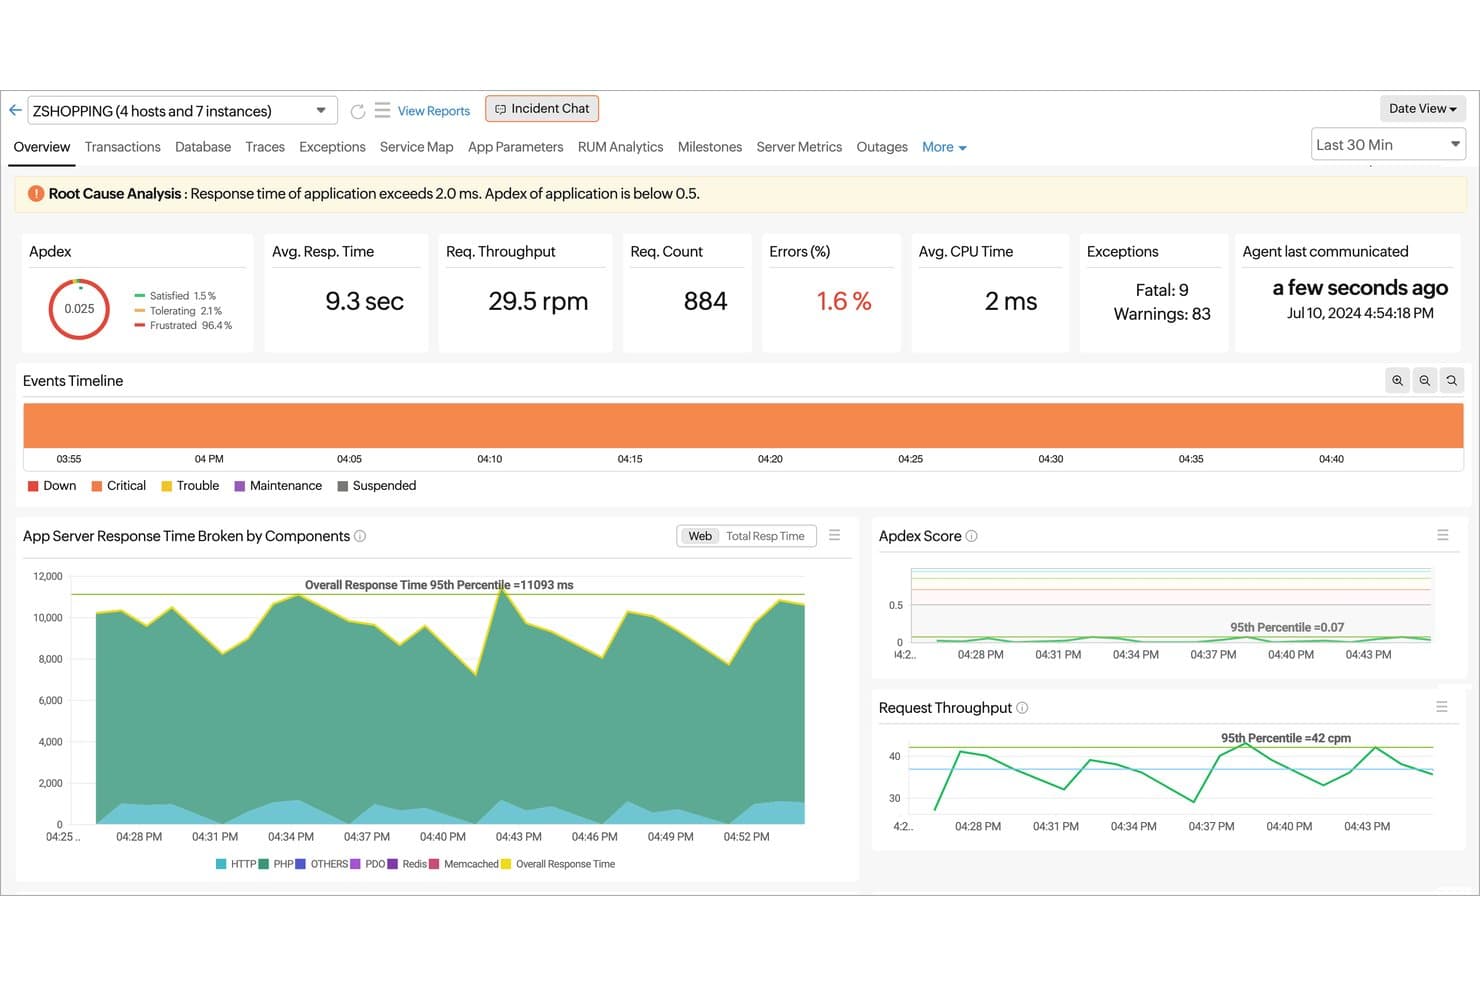
Site24x7 surfaces root cause analysis and APM metrics in one view. Site24x7 is an IT observability and monitoring platform for teams evaluating Dynatrace alternatives, helping IT specialists track application and infrastructure performance, diagnose service issues, and monitor hybrid environments.
Who Is Site24x7 Best For?
Site24x7 suits IT teams monitoring applications and infrastructure across diverse, hybrid environments.
Why I Picked Site24x7
I picked Site24x7 for the “Best for diverse application environments” use case because its APM supports Java, .NET, PHP, Ruby, Node.js, and Python. I like how distributed tracing and code-level diagnostics help me follow slow transactions across services, while OpenTelemetry support fits instrumented environments.
Site24x7 Key Features
- Server monitoring: Tracks CPU, memory, disk, and network metrics across physical, virtual, and cloud servers.
- Network monitoring: Measures device health, bandwidth, latency, and traffic across routers, switches, and firewalls.
- Log management: Collects and searches logs from applications, systems, and cloud sources.
- Website monitoring: Checks website availability from more than 130 global locations.
Site24x7 Integrations
Site24x7 supports integrations with ServiceNow, PagerDuty, Jira, Slack, Microsoft Teams, Opsgenie, Amazon EventBridge, and Zapier. It also provides REST APIs for custom integrations.
Pros and Cons
Pros:
- Checks website availability from 130+ locations
- Traces transactions across supported application languages
- Monitors applications across diverse hybrid environments
Cons:
- Dashboards feel cluttered with limited customization
- Alert tuning can produce false positives
Learn more about Site24x7: Best for enterprise-level open-source monitoring
- Free plan + 5-day free trial + free demo available
- From $325/month (billed annually)
Visit WebsiteCustomer Rating:4.5/5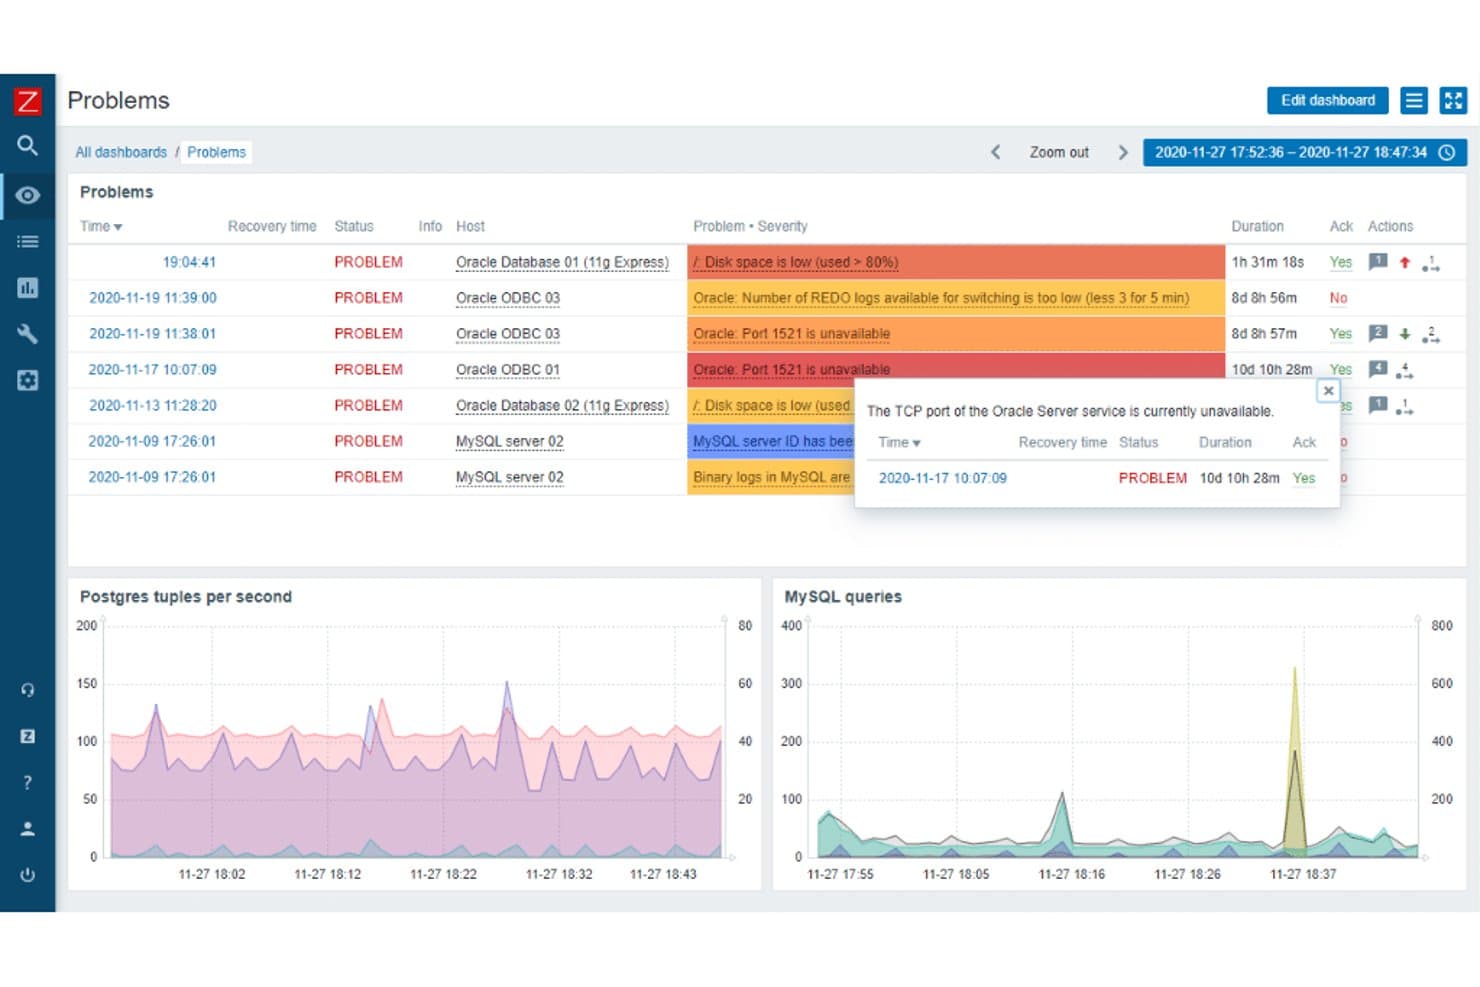
Zabbix surfaces active database and server problems with severity details. Zabbix is an infrastructure monitoring platform for IT teams that need to track servers, networks, and applications, spot service issues, and manage visibility across complex environments.
Who Is Zabbix Best For?
Zabbix suits enterprise IT operations teams that need customizable, open-source monitoring across large, distributed environments.
Why I Picked Zabbix
I picked Zabbix for this Guide to the Top Dynatrace Alternatives because it’s Best for enterprise-level open-source monitoring. I like how distributed proxies collect data from remote sites, while reusable templates apply checks and triggers across servers and network devices. That gives operations teams a way to monitor a large, mixed environment without relying on a proprietary platform.
Zabbix Key Features
- Event correlation: Define rules to group related problems and suppress symptom events.
- Web monitoring: Track multi-step web scenarios and response times.
- Network maps: Build maps that display monitored hosts, links, and current problems.
- Low-level discovery: Automatically detect entities such as network interfaces and create items to monitor them.
Zabbix Integrations
Zabbix’s official integrations catalog lists 1,986 solutions across 559 brands, including AWS, Azure, Kubernetes, ServiceNow, Slack, Jira, and PagerDuty. It also provides an HTTP-based JSON-RPC API and customizable JavaScript webhooks for custom integrations.
Pros and Cons
Pros:
- Correlates related alerts to reduce noise
- Reusable templates standardize checks across fleets
- Scales across distributed sites with proxies
Cons:
- Large deployments need database and proxy tuning
- Initial setup demands substantial manual configuration
 Best for comprehensive IT infrastructure monitoring
- 30-day free trial
- From $2,595 one-time
Visit WebsiteCustomer Rating:4.6/5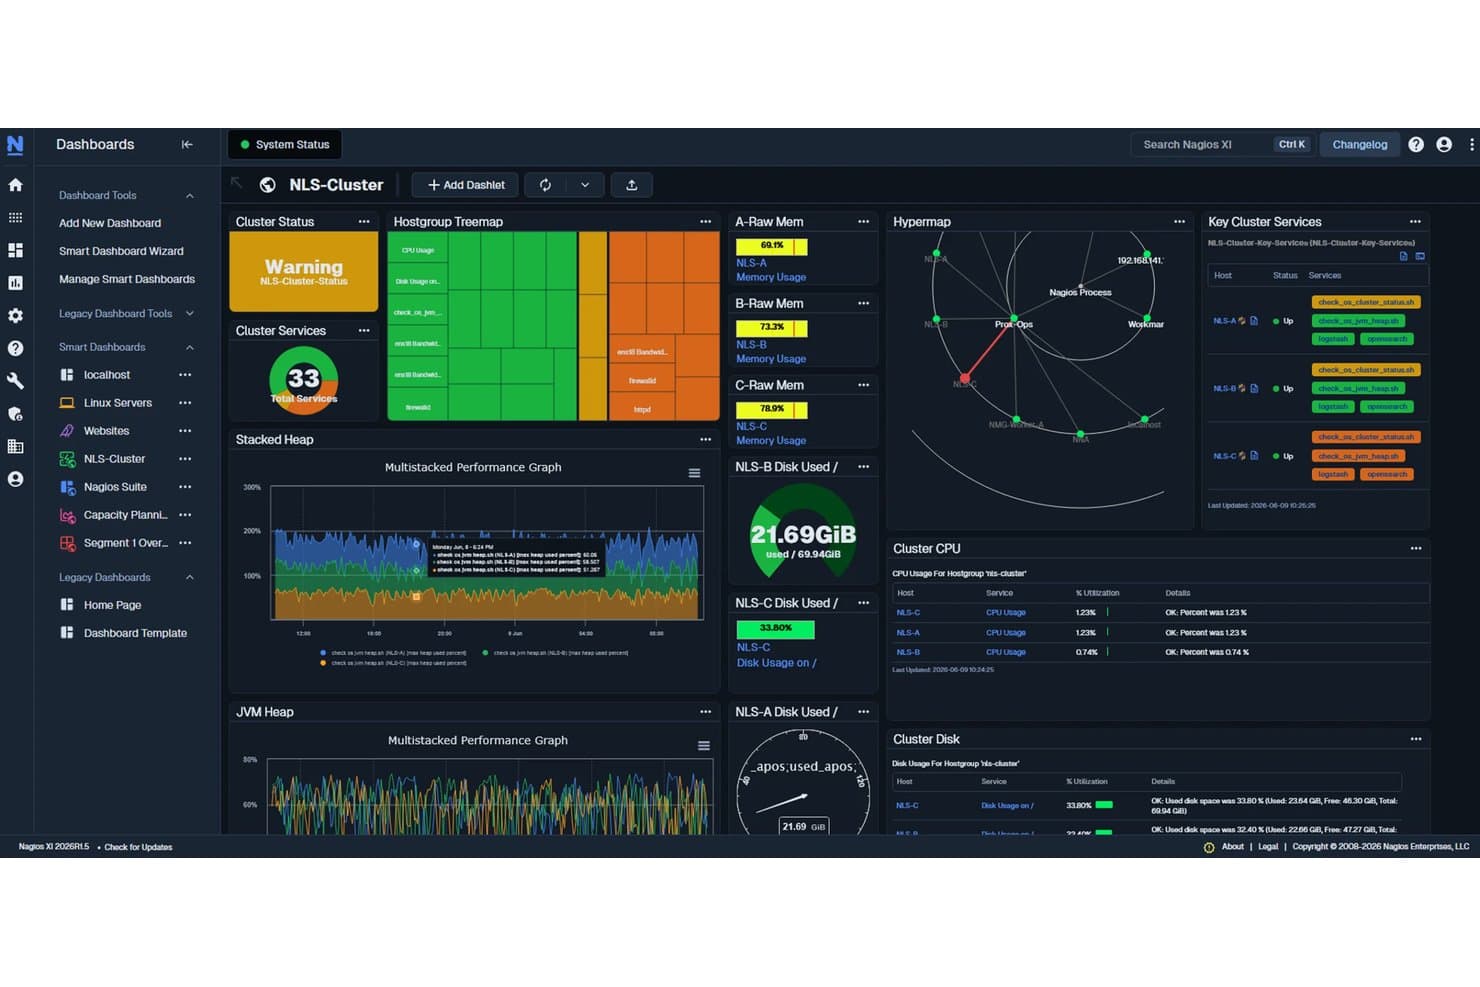
Nagios XI centralizes cluster health, CPU, disk, and service monitoring in one dashboard. Nagios gives IT teams configurable host and service monitoring to detect outages across servers, network devices, and applications in varied infrastructure environments.
Who Is Nagios Best For?
Nagios suits infrastructure and operations teams that need configurable monitoring across mixed environments, including established systems and network equipment.
Why I Picked Nagios
I picked Nagios for a Dynatrace alternatives guide because it fits “Best for comprehensive IT infrastructure monitoring” with plugin-based host and service checks. I use SNMP checks to monitor switches and routers alongside server health, then configure alerts when checks fail. That lets me track mixed infrastructure in one monitoring system.
Nagios Key Features
- Auto-discovery: Detects devices and services on your network.
- Configuration wizards: Guide setup for common devices and applications.
- Dashboards: Display status summaries, maps, and graphs in customizable views.
- Performance graphs: Chart monitoring data over time.
Nagios Integrations
Nagios XI has documented integrations with Slack and PagerDuty for alert notifications and incident handling, configured through scripts and notification settings. Its REST API supports custom connections with tools such as CMDB and ticketing systems.
Pros and Cons
Pros:
- Dashboards show status and historical trends
- Reliable alerts with configurable thresholds
- Monitors mixed hosts through custom checks
Cons:
- External plugins can be stale or undocumented
- Initial setup demands Linux monitoring expertise
Learn more about Nagios: Best for unified cloud service tracking
- Free plan + free trial available
- From $18/host/month
Visit WebsiteCustomer Rating:4.5/5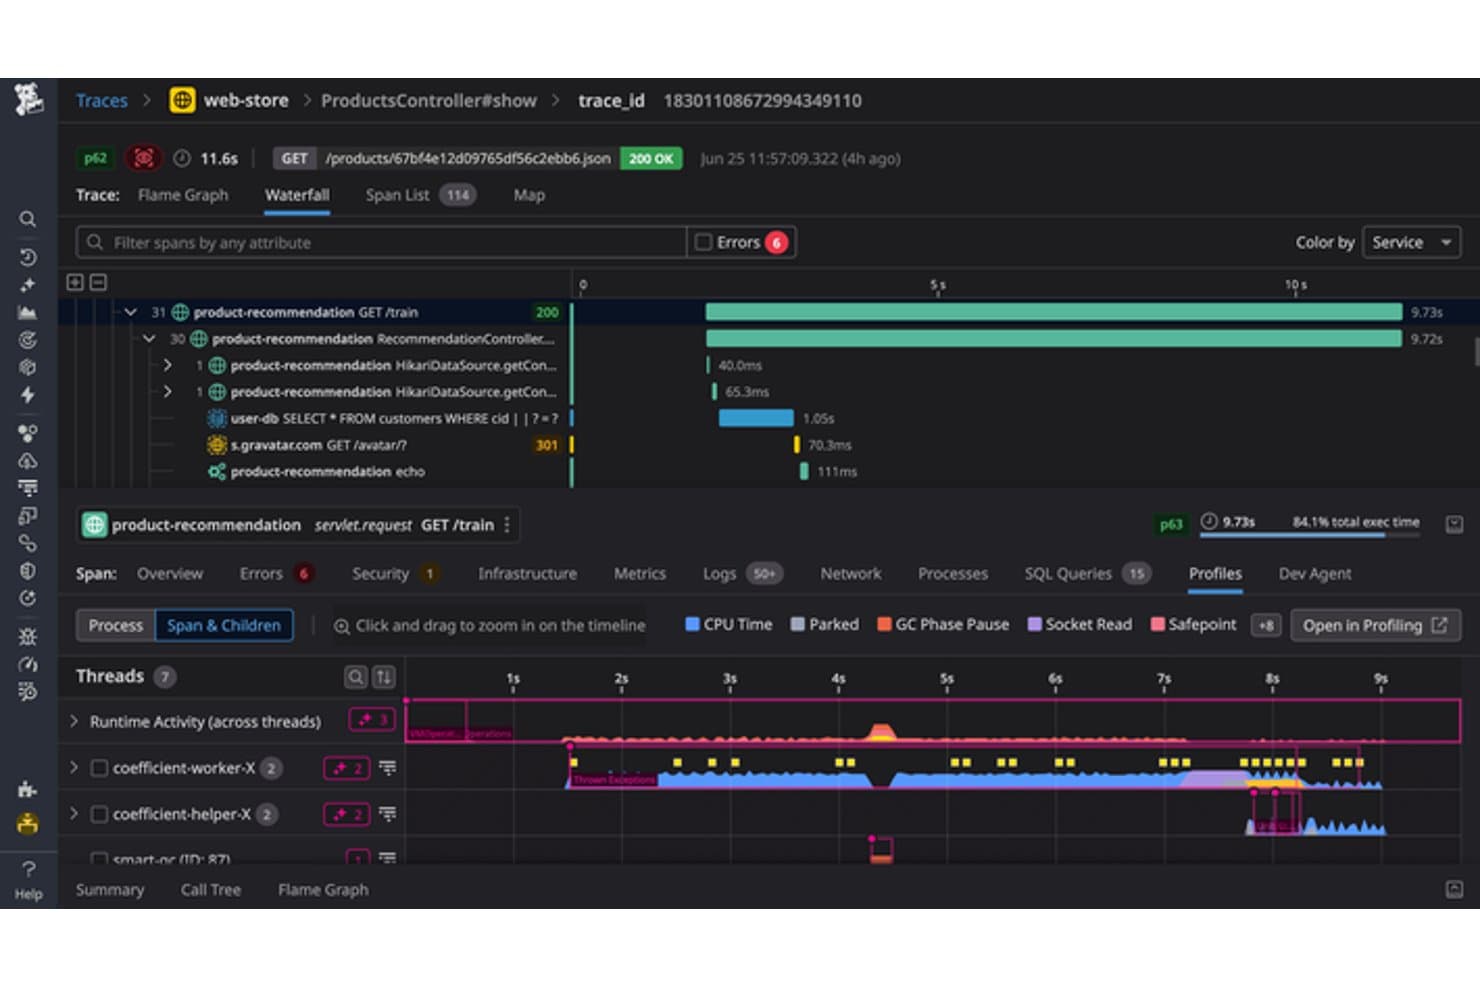
Datadog's APM traces CPU, threads, and span timelines in detail. Datadog is an observability platform for IT and DevOps teams that brings application, infrastructure, log, and security data together to help diagnose performance issues across cloud-native environments.
Who Is Datadog Best For?
Cloud operations and SRE teams can use Datadog to track service health across distributed infrastructure and pinpoint issues affecting production workloads.
Why I Picked Datadog
I picked Datadog for a Guide to the Top Dynatrace Alternatives because it earns “Best for unified cloud service tracking.” I like how its infrastructure metrics, distributed traces, and logs let me follow a slow request from a cloud host through dependent services and inspect related errors. Its service map helps me locate an upstream dependency affecting production health.
Datadog Key Features
- Real user monitoring: Captures browser sessions, frontend errors, and page performance.
- Synthetic monitoring: Runs scheduled browser and API tests against applications.
- Database monitoring: Shows query-level metrics and execution plans for supported databases.
- Monitors and alerts: Evaluates telemetry against thresholds and sends notifications when conditions trigger.
Datadog Integrations
Datadog offers more than 1,000 built-in integrations, including AWS, Azure, Google Cloud, Kubernetes, Docker, PostgreSQL, GitHub, Jira, Slack, and PagerDuty. It also supports custom integrations through its API.
Pros and Cons
Pros:
- Unifies infrastructure and application health views
- Maps dependencies to pinpoint upstream service failures
- Correlates metrics, logs, and traces during incidents
Cons:
- Advanced dashboards and queries require configuration time
- Telemetry growth makes bills hard to forecast
 Best for real-time business performance visibility
- 30-day free trial + free demo available
- From $6/month (billed annually)
Visit WebsiteCustomer Rating:4.3/5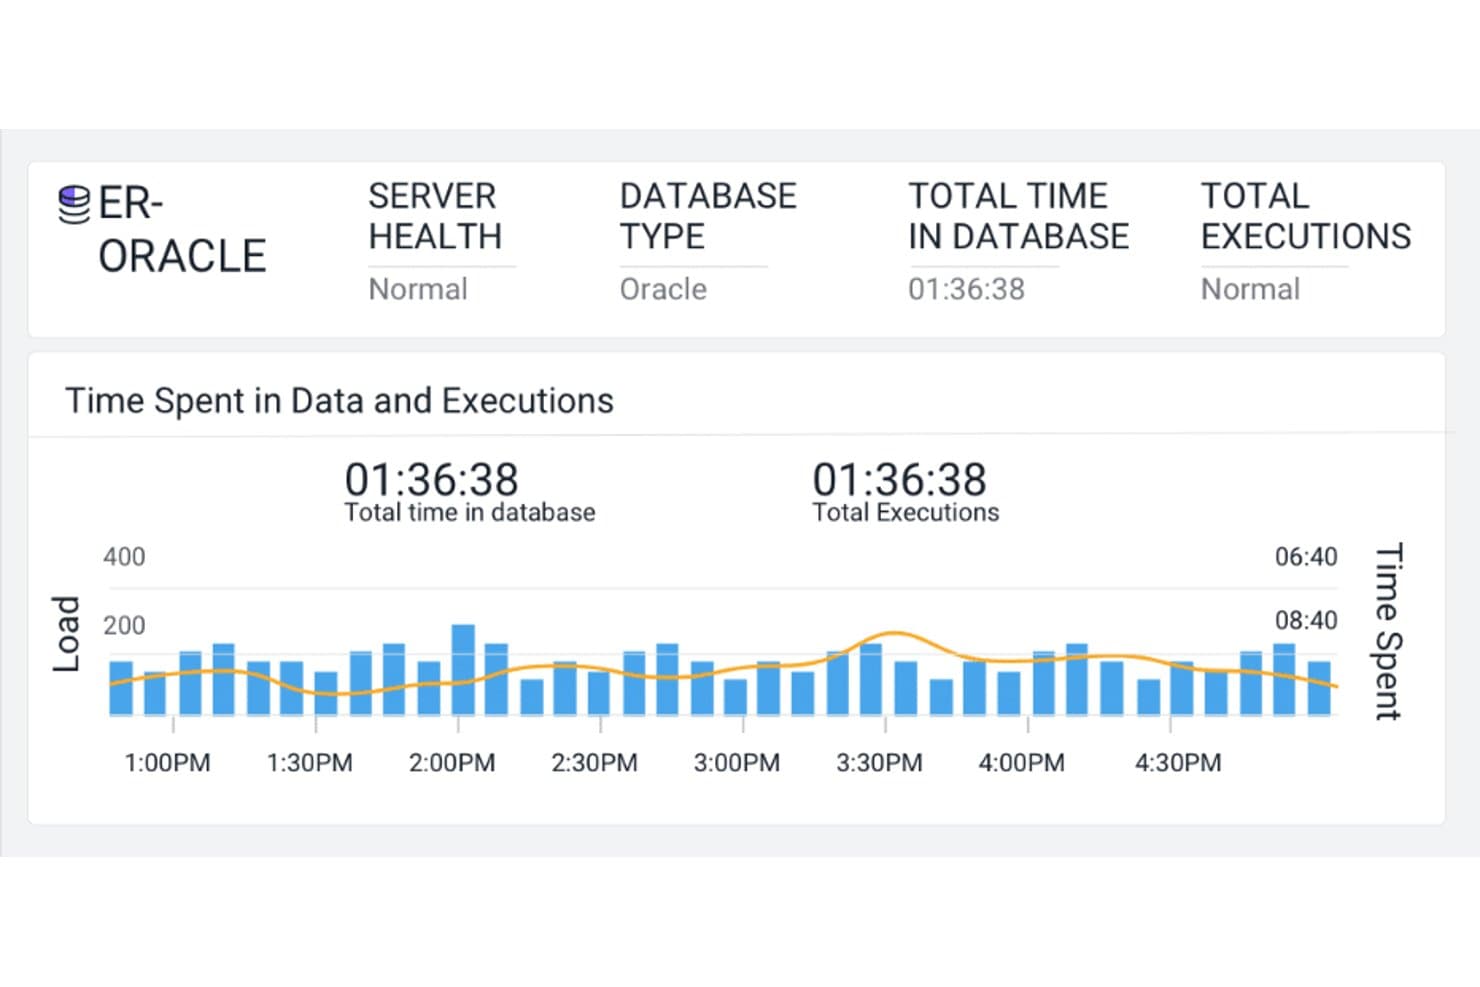
AppDynamics monitors Oracle database load and execution times visually. For IT and engineering teams comparing Dynatrace alternatives, AppDynamics combines application performance monitoring with transaction tracing to help locate slowdowns and errors across complex, distributed services.
Who Is AppDynamics Best For?
AppDynamics suits IT operations and application teams that need to connect live application health with the business transactions customers rely on.
Why I Picked AppDynamics
I picked AppDynamics because its focus, “Best for real-time business performance visibility,” connects live application health with the transactions customers depend on. I like how transaction tracing helps locate slowdowns across distributed services, so I can see where a request stalls and relate that issue to business activity.
AppDynamics Key Features
- Runtime application security: Detect application vulnerabilities and block attacks.
- Real-user monitoring: Capture web and mobile performance across devices and browsers.
- Synthetic monitoring: Monitor web, mobile, and API performance with simulated activity.
- Anomaly detection: Set performance baselines and flag deviations with AI and machine learning.
AppDynamics Integrations
AppDynamics has a built-in, two-way Jira integration for creating and updating incident tickets, plus an early-preview integration with Splunk Observability Cloud. It also offers prebuilt extensions and REST APIs for integrations and automation.
Pros and Cons
Pros:
- Baseline alerts flag deviations from normal
- Call graphs support code-level root cause analysis
- Business transaction maps connect telemetry to impact
Cons:
- Interface feels dated beside newer observability tools
- Instrumentation and agent setup take hands-on work
Learn more about AppDynamics: Best for querying telemetry in a unified data store
- Free plan + free demo available
- From $10/user/month
Visit WebsiteCustomer Rating:4.3/5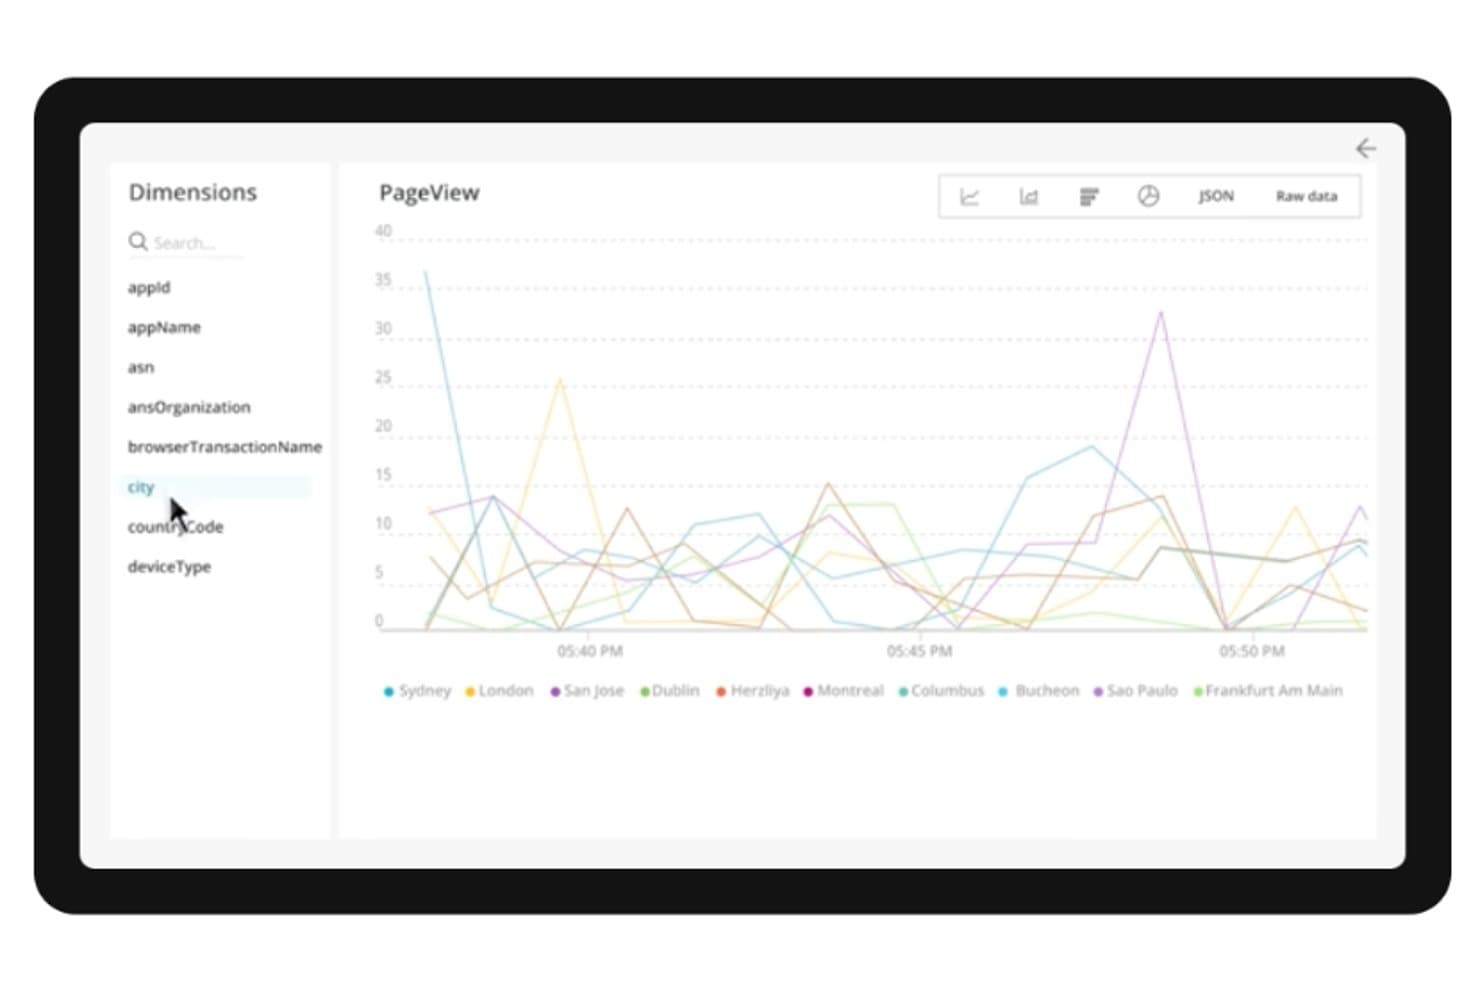
New Relic breaks down PageView data by city across a time series. For IT and engineering teams evaluating Dynatrace alternatives, New Relic is an APM platform that helps trace application issues, monitor service health, and investigate slowdowns across distributed systems.
Who Is New Relic Best For?
New Relic suits DevOps and site reliability teams that need to connect application traces, infrastructure metrics, and logs while diagnosing production issues.
Why I Picked New Relic
I picked New Relic for its “Best for comprehensive application performance monitoring” focus: it connects distributed traces with service health and logs, helping me follow slowdowns across services. When an API slows after a release, I can trace its request path and check related service signals to locate the affected dependency.
New Relic Key Features
- Database monitoring: Inspect slow database queries and their execution details.
- Code-level diagnostics: Profile application code to identify methods that consume CPU time.
- Deployment tracking: Mark releases to compare application performance before and after changes.
- Alert conditions: Set thresholds for application metrics and receive notifications when they’re breached.
New Relic Integrations
New Relic supports alert notification integrations with Atlassian Jira, AWS EventBridge, Microsoft Teams, PagerDuty, ServiceNow, and Slack, plus more than 400 on-host integrations. It also provides APIs and the Flex integration tool for sending custom data to New Relic.
Pros and Cons
Pros:
- Connects application performance with browser experience
- Tracks release regressions across distributed transactions
- Correlates traces, logs, and infrastructure signals
Cons:
- Ingestion growth can make costs unpredictable
- Dense navigation can slow incident investigation
Learn more about New Relic: Best for log management and security analytics
- 14-day free trial
- Pricing upon request
Visit WebsiteCustomer Rating:4.3/5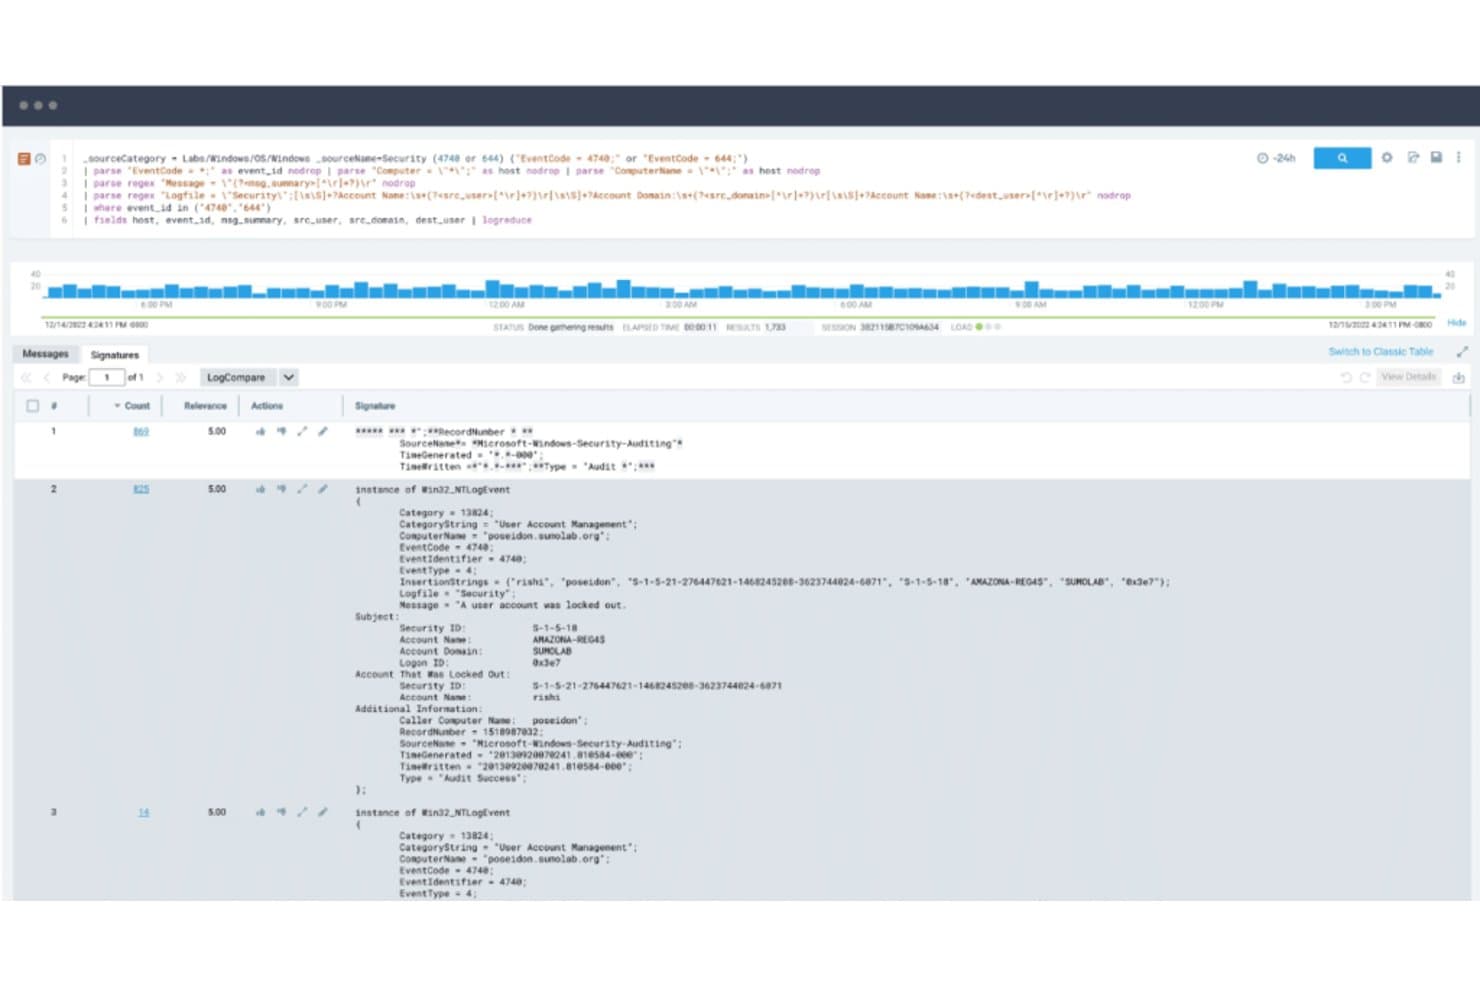
Sumo Logic detects account lockout events using security log analysis. Sumo Logic is a cloud-based observability platform that helps infrastructure and security teams investigate service disruptions and understand activity across distributed applications, making it an option for teams evaluating Dynatrace alternatives.
Who Is Sumo Logic Best For?
Security analysts and IT operations teams that need centralized log data for troubleshooting, threat detection, and investigation are a good fit for Sumo Logic.
Why I Picked Sumo Logic
I picked Sumo Logic for this Dynatrace-alternatives guide because it matches “Best for log management and security analytics.” Its log search helps me trace errors across distributed services, while Cloud SIEM correlates security signals to support investigation of suspicious activity.
Sumo Logic Key Features
- Metrics analytics: Query time-series metrics with Sumo Logic’s metrics query language.
- Distributed tracing: Inspect trace spans to follow requests across instrumented services.
- Dashboards: Create visualizations from telemetry data and arrange them in custom layouts.
- Monitors and alerts: Define conditions on metrics or queries to trigger notifications.
Sumo Logic Integrations
Sumo Logic’s App Catalog covers hundreds of vendors and products, including AWS, Azure, Datadog, Dynatrace, GitHub, and Jira, with offerings such as data-collection sources, prebuilt apps, and automation integrations. It provides native webhook integrations for ServiceNow and Slack, plus REST APIs for custom integrations.
Pros and Cons
Pros:
- Cloud SIEM correlates threats for investigation
- Centralized logs power real-time alerting
- Fast log searches support incident investigations
Cons:
- Log collection and parsing need refinement
- Query language takes time to master
 10Best for large-scale data analysis and insights
Splunk
- Free plan available
- From $15/host/month (billed annually)
Visit WebsiteCustomer Rating:4.3/5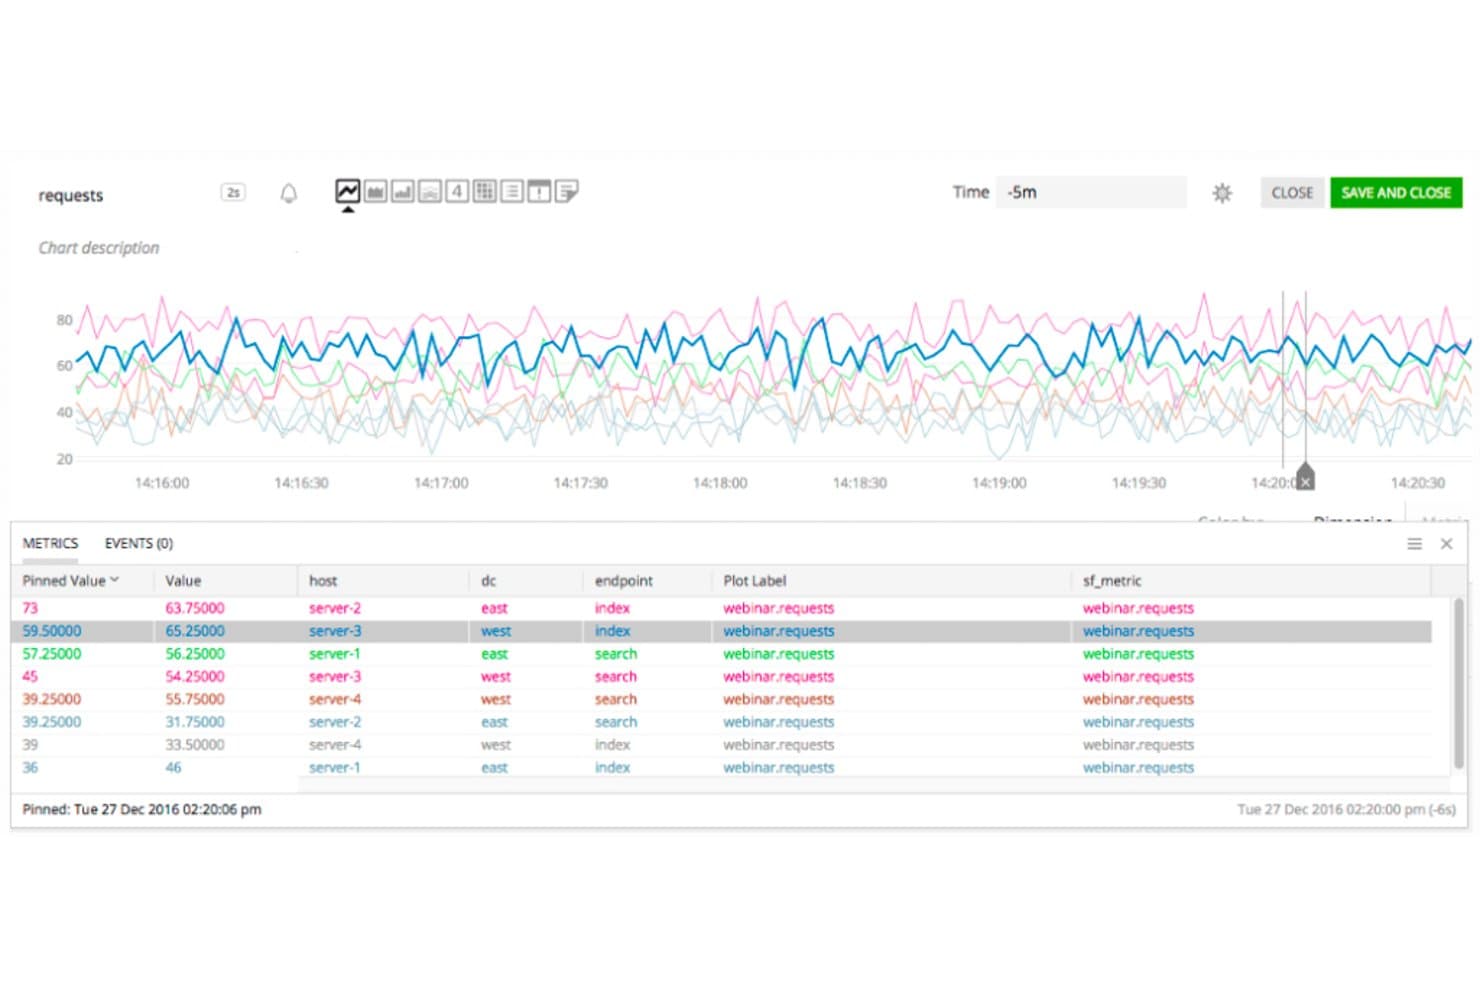
Splunk lets users monitor real-time request metrics across servers and endpoints. Splunk combines infrastructure monitoring with log, metric, and trace analysis, helping IT and operations teams investigate incidents across complex, distributed environments.
Who Is Splunk Best For?
Splunk suits large IT and security teams that need to analyze high volumes of machine data and uncover patterns across complex environments.
Why I Picked Splunk
I picked Splunk as a Dynatrace alternative for its “Best for large-scale data analysis and insights” focus. It combines infrastructure monitoring with log, metric, and trace analysis, so I can investigate a service slowdown across distributed systems and connect signals to related events. That helps me query high volumes of machine data during incident investigations.
Splunk Key Features
- Custom dashboards: Build visual panels with charts, tables, and service data.
- Alert detectors: Set conditions that trigger alerts when monitored signals cross thresholds.
- Kubernetes monitoring: Explore cluster, node, and workload health in the Kubernetes Navigator.
- Synthetic monitoring: Run scripted tests to check application availability and response times.
Splunk Integrations
Splunk Observability Cloud supports integrations with AWS CloudWatch, Google Cloud Platform, Microsoft Azure, Jira, Microsoft Teams, PagerDuty, ServiceNow, and Slack. Its integrations API configures supported connections, while Splunkbase provides apps, add-ons, and connectors.
Pros and Cons
Pros:
- Custom dashboards and alerts support focused triage
- Correlates logs, metrics, and traces for investigations
- Searches high-volume machine data for incident clues
Cons:
- Heavy queries can slow dashboards at scale
- Costs can rise as telemetry ingestion grows
Learn more about Splunk:
Andre alternativer til Dynatrace
Her er noen flere alternativer til Dynatrace som ikke kom med på kortlisten min, men som likevel er verdt å undersøke:
- 11PrometheusBest for robust monitoring in Kubernetes environments
- 12Grafana CloudBest for open-source visualization and analytics
- 13ElasticBest for real-time search and data analytics
- 14SolarWinds Observability SaaSBest for AI-driven alert prioritization
- 15SysdigBest for container and Kubernetes security
- 16Dotcom MonitorBest for real-browser simulations
- 17AuvikGood for comprehensive network infrastructure management
- 18PingdomGood for uptime, performance, and user experience monitoring
- 19LogicMonitorGood for SaaS-based, agentless monitoring
- 20IcingaGood for comprehensive monitoring with strong community support
- 21HoneycombGood for observability and debugging in production systems
- 22SensuGood for robust event filtering in monitoring workflows
- 23Stackify RetraceGood for deep code-level insights for developers
- 24InstanaGood for real-time performance monitoring with automatic APM
- 25ThousandEyesGood for network intelligence and visualizing network paths
- 26Scout APMGood for developers wanting detailed performance insights
- 27OpsviewGood for businesses seeking customizable dashboards and reporting
- 28RiverbedGood for network performance monitoring with digital experience focus
- 29Wavefront by VMwareGood for scalable, high-granularity observability and analytics
Andre programvareanmeldelser
- Verktøy for kodegjennomgang for utviklere
- Verktøy for webutvikling
- Verktøy for infrastrukturautomatisering
How I Evaluate Dynatrace Alternatives
I evaluate every tool on two levels: the must-haves like full-stack APM and distributed tracing, then the differentiators that separate platforms for different teams and stacks.
Core Functionality (Table Stakes For This List)
When I'm selecting tools for my list, I rank each one on a scale from 0 (does not offer the functionality) to 5 (excels in this area) for each core functionality listed below. Then, I calculate the tool's total score into a percentage. Each tool needs to achieve a minimum total score of 75% to be considered for inclusion.
- Full-Stack APM: I check whether the tool provides code-level transaction tracing across major languages and frameworks, like catching a slow database call buried in a Java microservice.
- Infrastructure Monitoring: Each tool should cover servers, containers, Kubernetes clusters, and cloud services with auto-discovery rather than requiring manual host-by-host setup.
- Distributed Tracing: I evaluate how traces flow across service boundaries and whether the platform supports OpenTelemetry ingestion, which matters when teams run polyglot stacks.
- Log Management & Analytics: Logs need to be correlated with traces and metrics in a single view, so an SRE can pivot from a spike in error rates to the exact log lines behind it.
- AI-Driven Anomaly Detection: I look for machine learning that baselines normal behavior and surfaces root cause suggestions, not just static threshold alerts that flood on-call channels.
- Real User & Synthetic Monitoring: The platform should offer both RUM for live traffic analysis and synthetic checks that catch broken checkout flows or API failures before real users do.
Once I have a list of tools that meet this criteria, I consider what sets each platform apart.
Differentiating Factors (What Sets Vendors Apart)
Here's how I compare and contrast different vendors:
Standout Features
Pricing transparency matters when you're switching from Dynatrace, so I evaluate whether a platform offers predictable, usage-based pricing with clear cost controls. OpenTelemetry native support is another key differentiator—teams already instrumented with OTel collectors shouldn't need to rip everything out for proprietary agents. I also look for automated remediation workflows that trigger runbooks or escalate through tools like PagerDuty when an anomaly fires, turning alerts into action without manual intervention.
Beyond Features
Deployment flexibility is a big one—I check whether a platform supports SaaS, self-hosted, and hybrid models, since teams in regulated industries often need on-prem or specific data residency options. The integration ecosystem also shapes how well a tool fits your existing stack. Native connectors to CI/CD pipelines, ITSM platforms like ServiceNow, and incident tools like Opsgenie make a real difference during adoption. I also evaluate compliance certifications like SOC 2 Type II and ISO 27001, along with SSO and role-based access controls.
Hvorfor se etter et alternativ til Dynatrace?
Selv om Dynatrace er et godt valg som plattform for overvåking av applikasjonsytelse (APM), finnes det flere grunner til at noen brukere ser etter alternative løsninger. Det kan hende du ser etter et alternativ til Dynatrace fordi …
- Prisen kan bli for høy for mindre team
- Læringskurven føles for bratt for nye brukere
- Du ønsker enklere oversikter og rapportering
- Du trenger mer fleksible alternativer for varsler og meldinger
- Du bruker et hybridoppsett og trenger bredere integrasjoner
- Du foretrekker verktøy med mer oversiktlig fakturering
Hvis noe av dette høres kjent ut, har du kommet til rett sted. Listen min inneholder flere alternativer til plattformer for overvåking av applikasjonsytelse (APM) som passer bedre for team som møter disse utfordringene med Dynatrace og ser etter alternative løsninger.
Viktige funksjoner i Dynatrace
Her er noen av de viktigste funksjonene i Dynatrace, som kan hjelpe deg med å sammenligne hva alternative løsninger tilbyr:
- Overvåking av hele teknologistakken: Lar deg følge med på applikasjonsytelse, infrastruktur og brukeropplevelse på ett og samme sted.
- Davis AI-motor: Oppdager problemer automatisk og forklarer den grunnleggende årsaken, slik at teamet ditt sparer tid.
- Overvåking av reelle brukere: Viser hvordan faktiske brukere samhandler med applikasjonen din, slik at du kan løse problemer som betyr noe.
- Applikasjonssikkerhet: Varsler om sårbarheter i sanntid mens koden kjører i produksjon.
- Støtte for skybaserte miljøer: Fungerer godt med Kubernetes, AWS, Azure og andre skymiljøer.
- Smarte varsler: Sender bare varsler når det er nødvendig, slik at teamet ditt unngår varselstretthet.
- Tilpassede dashbord: Lar deg bygge visninger som er tilpasset teamets behov og måleverdier.
- Innsikt på kodenivå: Hjelper deg med å undersøke ytelsen ned til individuelle kodelinjer.
- Loggadministrasjon: Lar deg søke i, filtrere og analysere logger for raskere feilsøking.
- Syntetisk overvåking: Simulerer brukerhandlinger, slik at du kan teste applikasjonsytelsen fra ulike steder.
Sammendrag
I denne kjøpsveiledningen gikk vi i dybden på alternativer til Dynatrace og utforsket ulike alternativer tilpasset bestemte bruksområder. Enten du ser etter et verktøy for overvåking av åpen kildekode på virksomhetsnivå, loggadministrasjon og sikkerhetsanalyse eller sikkerhet for containere og Kubernetes, har du mange solide alternativer å vurdere.
Her er tre viktige lærdommer fra denne veiledningen:
- Vurder behovene dine: Ulike verktøy er utviklet med tanke på forskjellige bruksområder. Noen egner seg godt for omfattende loggadministrasjon, andre for miljøer med åpen kildekode, og andre igjen for sikkerhet for containere og Kubernetes. Når du forstår organisasjonens unike behov, blir det enklere å finne det riktige verktøyet.
- Se på funksjonene: Verktøy kan ha lignende kjernefunksjoner, men det er detaljene som avgjør. De unike funksjonene i hvert verktøy, brukervennligheten og integrasjonene med andre verktøy du bruker, kan utgjøre hele forskjellen for overvåkingsopplevelsen.
- Vurder prisene: Selv om kostnaden ofte er en viktig faktor, er det viktig å vurdere hva du får for pengene. Et dyrere verktøy kan tilby den solide funksjonaliteten eller støtten du trenger, og i noen tilfeller kan et billigere eller til og med kostnadsfritt verktøy dekke behovene dine.
Husk at det «beste» verktøyet avhenger helt av organisasjonens spesifikke krav og omstendigheter. Med informasjonen i denne veiledningen er du godt på vei mot å ta en informert beslutning.