

Monitoring your network with an all-in-one monitoring platform can be challenging, especially when your current tools don't quite meet your needs. You may be using PRTG and finding that it doesn't align with your team's specific requirements or lacks certain features.
In my experience, finding the right network monitoring solution can significantly ease your workload, reduce downtime, and improve overall performance. That's why I've researched and tested various PRTG alternatives to help you discover the best fit for your business.
In this article, you'll find unbiased reviews of top alternatives, focusing on their unique features and benefits. Whether you're looking for better scalability, specific industry compliance, or enhanced user experience, I'll guide you through the options. Let's find the network monitoring software that best supports your team.
What Is PRTG?
Paessler Router Traffic Grapher (PRTG), often referred to as PRTG Network Monitor, is a monitoring tool designed to help you track your network's health and performance. IT monitoring professionals and network administrators generally use PRTG for its ability to provide detailed insights into network traffic and system uptime. Features such as real-time monitoring, customizable alerts, and detailed reporting support your need for efficient network management. PRTG can provide valuable insights that will help your systems run smoothly, but there are alternatives.
Why Trust Our Software Recommendations
6,700+
Reviews
20
Industry experts
16+
Evaluation factors
14
Years
Our team has been testing and reviewing software since 2012. As tech leaders ourselves, we know how difficult—and important—it is to choose the right software.
For this guide, we evaluated tools using hands-on testing and independent research, scoring tools using our selection criteria.
Our reviews reflect our human editorial judgment, not a sales pitch.
Expert reviewers:
- Paulo Gardini MiguelTech Director
 Tim FisherVP of AI
 Gabriel RosasTech Lead & Software Architect
 Christhian GruhnTech Lead & Platform Architect

PRTG Alternatives Comparison Table
This comparison table summarizes pricing details for my top PRTG alternative selections:
Score legend (out of 5)
- Excellent4.5–5
- Good4–4.4
- Average3–3.9
- Below average2–2.9
- Poor1–1.9
Sorted by: Default
| Tool | Starting Price | Website | |||||||
|---|---|---|---|---|---|---|---|---|---|
Best for detailed SLA reporting | 4.0 out of 5 | 4 | 4 | 4 | 4 | 4 | 4 | $1,400/year Free plan + 60-day free trial available | Website |
Best for remote IT management | 2.7 out of 5 | 3 | 4 | 2 | 2 | 2 | 3 | Pricing upon request Free demo available | Website |
Best for open-source scalability | 4.2 out of 5 | 4 | 5 | 4 | 4 | 4 | 4 | $325/month Free plan + 5-day free trial + free demo available | Website |
Best for cloud-based observability | 3.5 out of 5 | 4 | 4 | 3 | 3 | 3 | 4 | $18/host/month Free plan + free trial available | Website |
Best for customizable dashboards | 3.8 out of 5 | 4 | 4 | 3 | 4 | 4 | 4 | $2,595 one-time Free plan + 30-day trial + demo available | Website |
Best for Internet Path Visibility | 3.2 out of 5 | 4 | 3 | 2 | 3 | 3 | 4 | Pricing upon request 15-day free trial + demo available | Website |
Best for unified endpoint management | 3.3 out of 5 | 4 | 4 | 4 | 3 | 2 | 3 | $3.75/month 14-day free trial + free demo available | Website |
Best for automatic network discovery | 3.3 out of 5 | 4 | 4 | 4 | 3 | 3 | 2 | Pricing upon request Free plan + free demo available | Website |
Best for synthetic network monitoring | 3.8 out of 5 | 4 | 4 | 3 | 4 | 4 | 4 | $249/month Free plan + 14-day trial + free demo available | Website |
Best for automated network mapping | 3.8 out of 5 | 4 | 4 | 5 | 4 | 4 | 2 | Pricing upon request 14-day free trial + demo available | Website |


Best PRTG Alternatives Reviews
Below are my detailed summaries of the best PRTG alternatives that made it onto my shortlist. My reviews offer a detailed look at the key features, pros and cons, integrations, and ideal use cases of each tool to help you find the best one for you.
 Best for detailed SLA reporting
- Free plan + 60-day free trial available
- From $1,400/year (billed annually)
Visit WebsiteCustomer Rating:4.7/5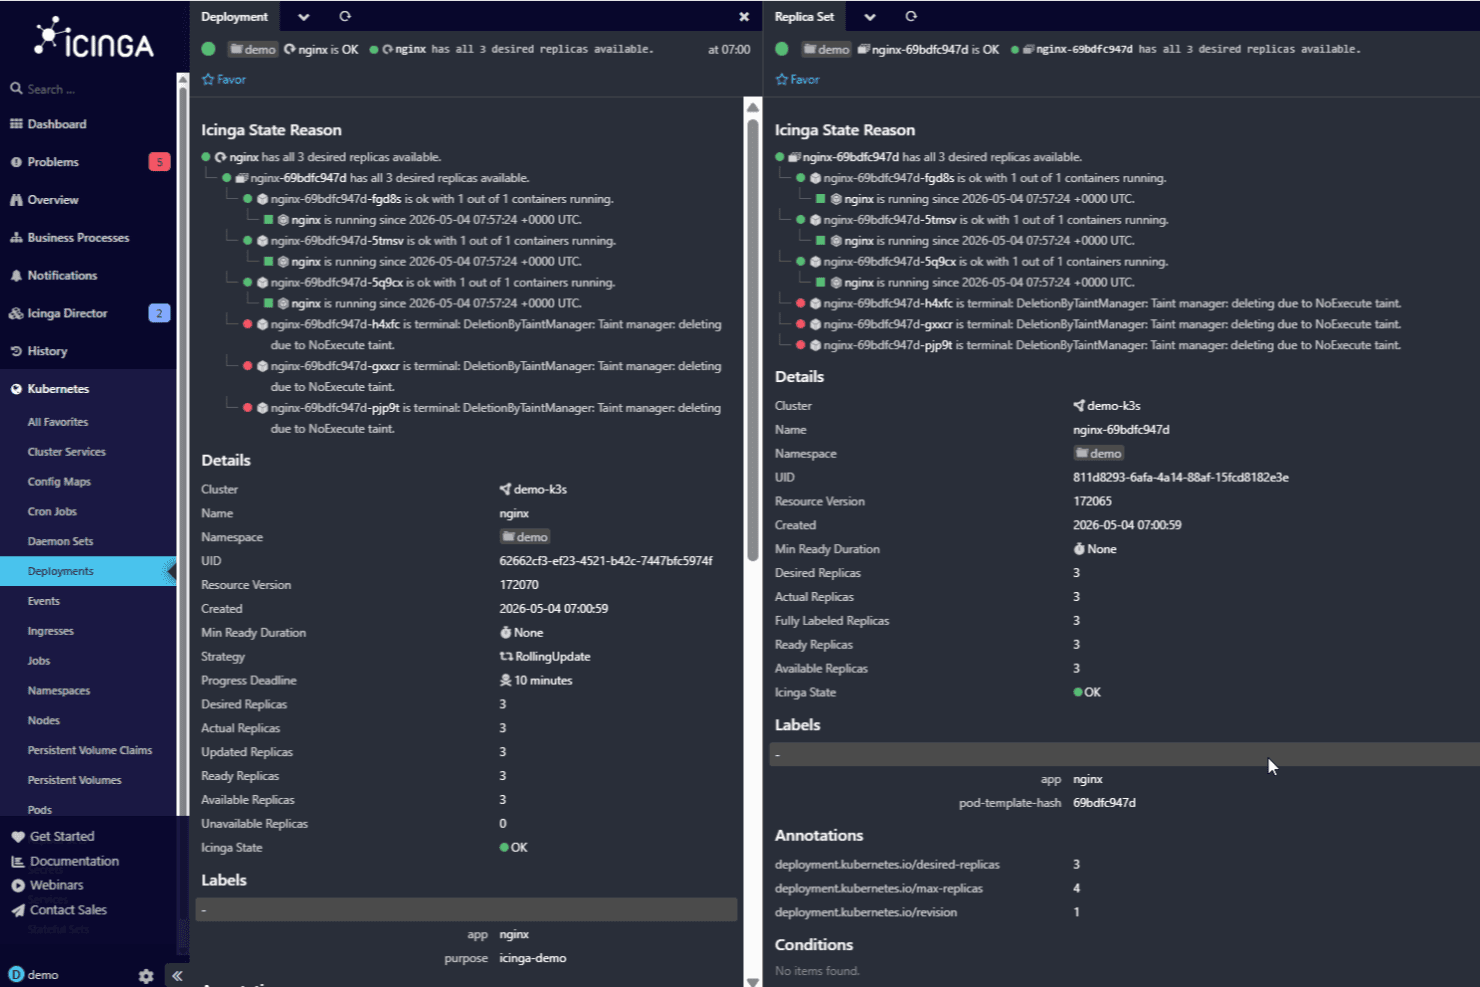
Icinga tracks all deployments on one dashboard with labels, details, and annotations. Icinga is an open-source infrastructure monitoring platform that appeals to systems engineers, network administrators, and MSPs who need unlimited host monitoring, flexible check methods, and detailed SLA reporting without per-sensor licensing constraints.
Who Is Icinga Best For?
Icinga is a strong fit for systems engineers and MSP technicians who need to monitor large, distributed infrastructure without per-host licensing costs holding them back.
Why I Picked Icinga
I picked Icinga as one of the best because its SLA reporting goes deeper than most monitoring tools I've worked with. Icinga DB maintains separate SLA history tables that retain exactly the data needed for availability calculations, and history isn't deleted by default. You can generate host and service availability reports, preview them in Icinga Web, export them as PDFs, and schedule them to send automatically at regular intervals.
Icinga Key Features
- Distributed master/satellite/agent architecture: Deploys monitoring across multiple sites using parent and child nodes that continue checking and collecting data during network outages.
- Forever Free Edition with unlimited hosts: Monitors unlimited hosts and services at no cost, with no per-sensor or per-device licensing restrictions.
- API-driven configuration management: Uses a REST API to dynamically create, modify, and delete hosts, services, and configuration objects, with support for versioned configs and rollback.
- Multi-protocol check support: Monitors devices and services via SNMP, SSH, ICMP, agent-based checks, NSClient++, and passive results submitted through the REST API.
Icinga Integrations
Icinga has documented integrations with Grafana, Elasticsearch, NetBox, Graphite, InfluxDB, Prometheus, Ansible, Puppet, and Terraform. Its REST API supports custom integrations, configuration automation, event streams, and connections to ticketing workflows.
Pros and Cons
Pros:
- Custom checks cover mixed infrastructure
- Distributed checks continue during outages
- Detailed SLA availability reports
Cons:
- Long-term trend analysis needs separate tooling
- Setup requires substantial manual configuration
Learn more about Icinga: Best for remote IT management
- Free demo available
- Pricing upon request
Visit WebsiteCustomer Rating:4.7/5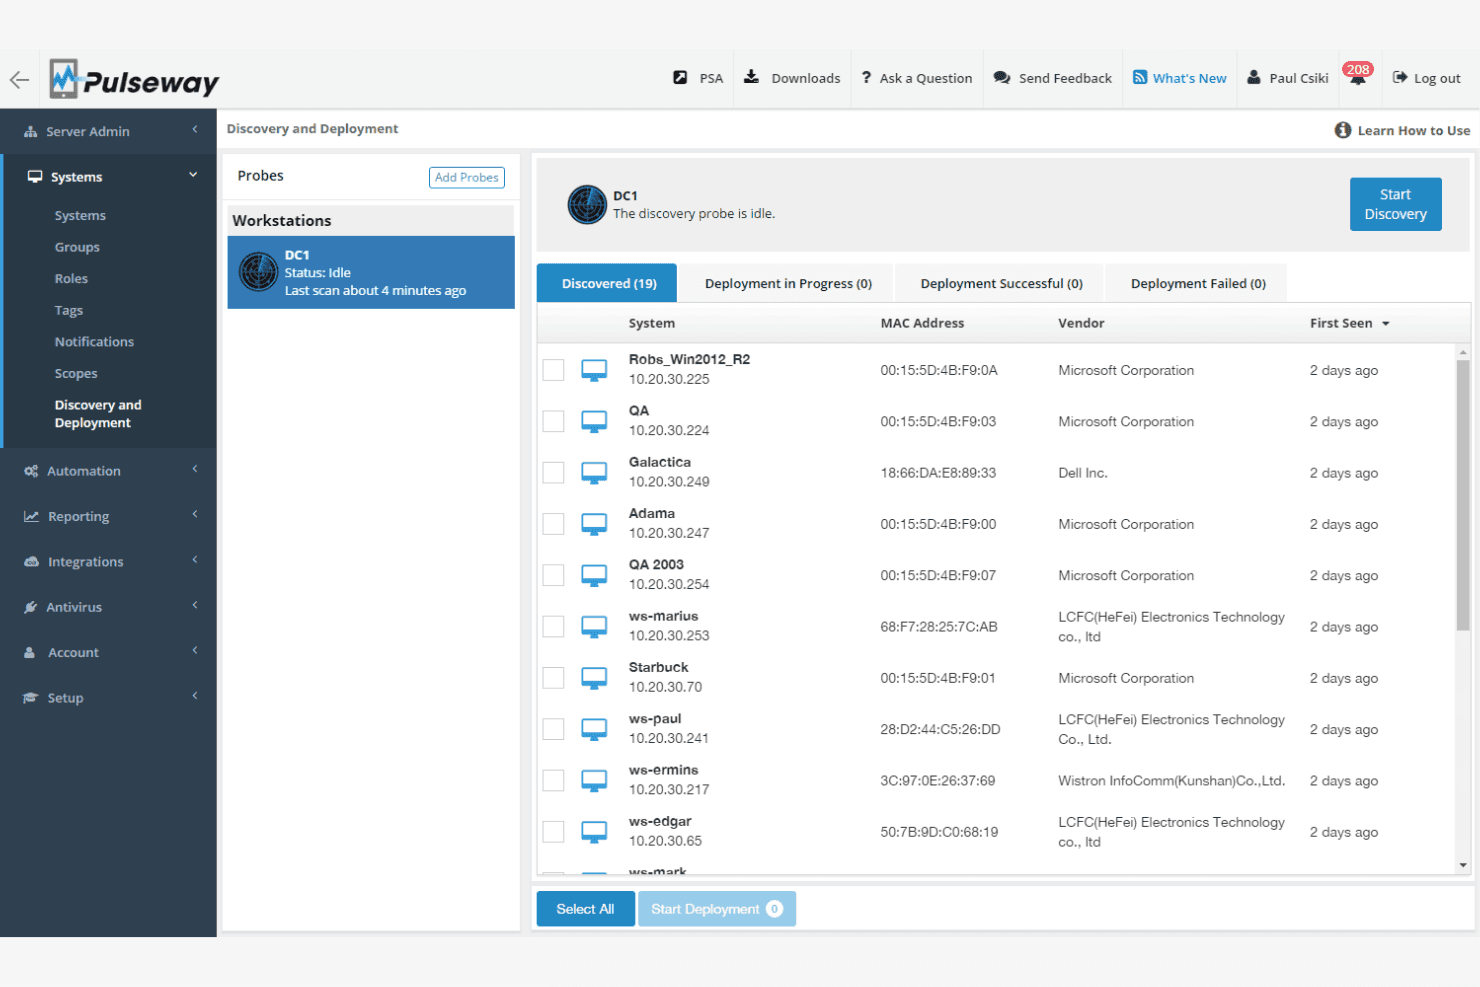
Pulseway's Discovery and Deployment screen finds devices on the network and tracks their deployment status. Pulseway is an RMM platform built for MSPs and IT teams that need to monitor, manage, and troubleshoot endpoints, servers, and network devices—with a strong focus on mobile-first remote access and alert response.
Who Is Pulseway Best For?
Pulseway is a strong fit for MSP technicians who need to monitor and manage client endpoints remotely, especially from a mobile device.
Why I Picked Pulseway
I picked Pulseway as one of the best because its mobile-first remote management sets it apart from tools like PRTG, which anchors you to a desktop console. I can respond to a critical server alert, run a remediation script, and restart a service directly from my phone before anyone notices an outage. Its SNMP-based conditional alerts integrate with automation workflows, so the response isn't just a notification—it's a fix already in motion.
Pulseway Key Features
- Network topology maps: Auto-generates customizable topology maps with editable device types, logical groupings, and network relationships.
- Patch management: Automates OS and third-party application patching across Windows, Mac, and Linux with configurable policies and schedules.
- Remote control session recording: Manually or automatically records remote-control sessions for Windows agents, covering both shared and private sessions.
- Alert-triggered automation workflows: Runs scripts and workflows in response to alerts to automatically resolve IT issues without manual intervention.
Pulseway Integrations
Pulseway offers native integrations with PagerDuty, Slack, ConnectWise Manage, Autotask, Zendesk, and IT Glue. It also provides REST, Client, and Cloud APIs plus plugins for custom connectivity.
Pros and Cons
Pros:
- Topology maps clarify discovered device relationships
- Alert-triggered scripts reduce repetitive troubleshooting
- Mobile alerts support fast remote response
Cons:
- Reporting offers limited customization and depth
- SNMP setup can be difficult
Learn more about Pulseway: Best for open-source scalability
- Free plan + 5-day free trial + free demo available
- From $325/month (billed annually)
Visit WebsiteCustomer Rating:4.5/5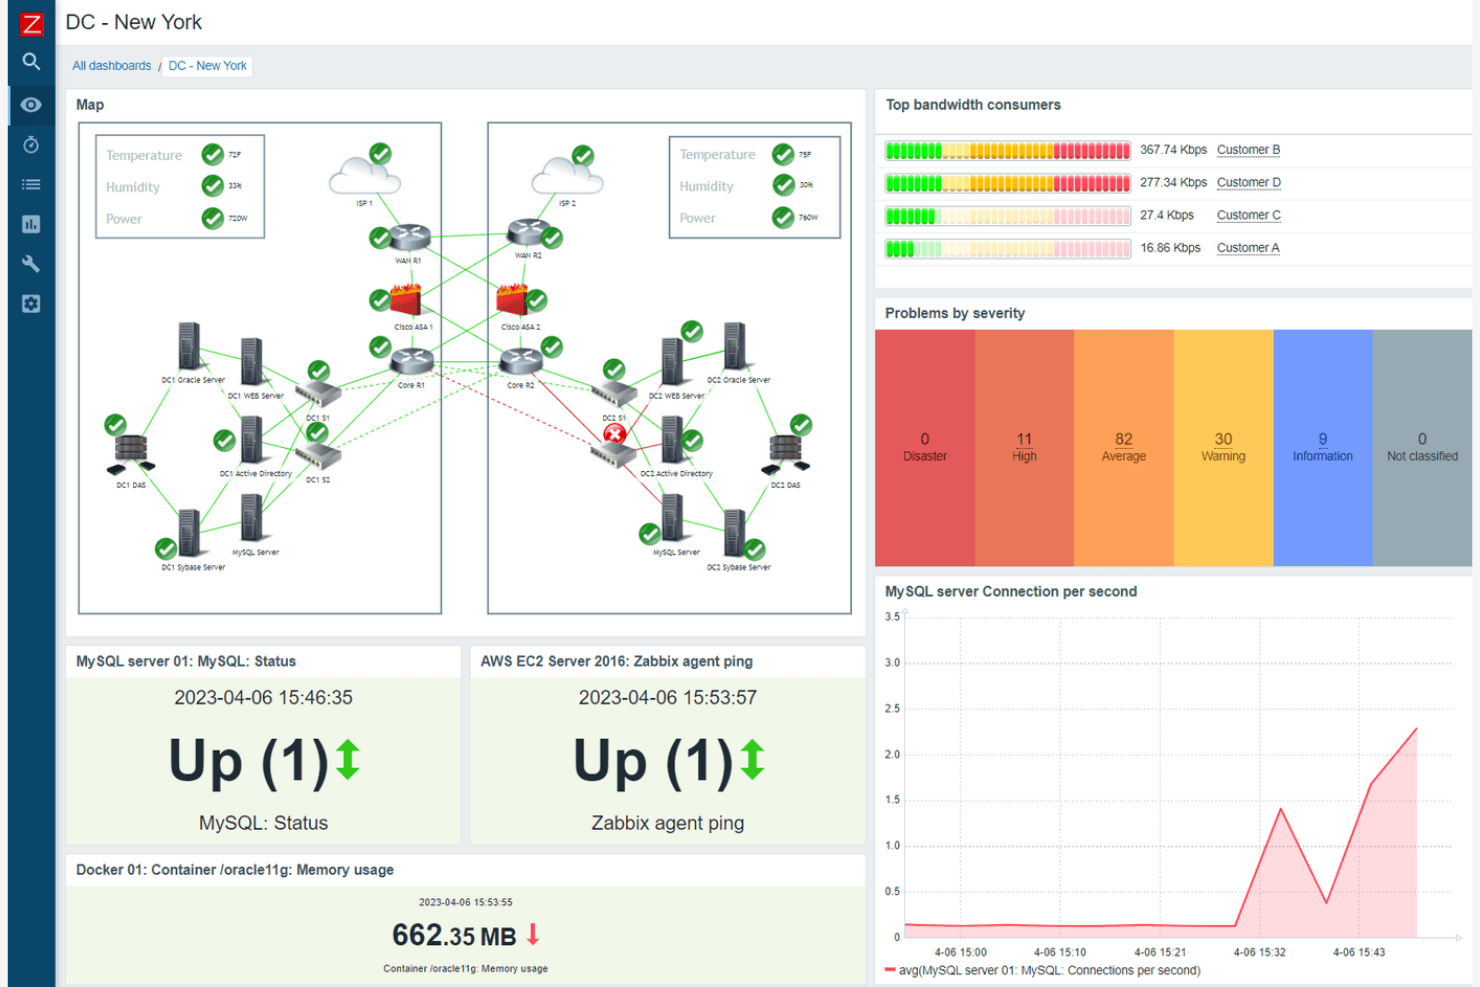
Zabbix dashboard displaying a data center network map, bandwidth usage, and problems by severity. Zabbix is an open-source monitoring platform that lets infrastructure and operations teams track servers, network devices, cloud resources, and applications without paying per sensor or per device.
Who Is Zabbix Best For?
Zabbix is a strong fit for infrastructure and operations teams that need to monitor large, complex environments without the cost of per-device or per-sensor licensing.
Why I Picked Zabbix
Zabbix earns its spot on my shortlist because it's one of the few monitoring platforms that genuinely scales to millions of metrics without charging per device or per sensor. I appreciate how its proxy-based architecture lets me distribute collection across remote sites, DMZs, and firewalls, so a single Zabbix server can realistically cover a sprawling multi-site infrastructure. The open-source license means there's no PRTG-style sensor cap quietly waiting to catch you as your environment grows.
Zabbix Key Features
- Multi-protocol agentless monitoring: Monitor network devices, servers, and services using SNMP, IPMI, SSH/Telnet, ICMP/TCP, Prometheus, Modbus, and MQTT without deploying an agent.
- Escalation workflows: Configure multi-step alert escalations with delays, repeat notifications, user group routing, and automated remote command execution.
- Business service trees: Define service hierarchies, calculate service status using configurable algorithms, and measure availability against SLA targets.
- JSON-RPC API: Access over 200 API methods to automate configuration, retrieve historical data, and integrate third-party tools with Zabbix.
Zabbix Integrations
Zabbix offers native integrations with ServiceNow, Jira ServiceDesk, Slack, Microsoft Teams, PagerDuty, AWS, Microsoft Azure, Google Cloud, Kubernetes, and VMware. Its JSON-RPC API provides more than 200 methods for custom integrations, with streaming to Kafka, RabbitMQ, Amazon SQS, and Amazon Kinesis.
Pros and Cons
Pros:
- No sensor-based license ceiling
- Agentless and agent-based monitoring covers varied systems
- Proxy-based polling buffers remote-site data
Cons:
- Alert thresholds need tuning to reduce noise
- Initial host and trigger setup takes effort
 Best for cloud-based observability
- Free plan + free trial available
- From $18/host/month
Visit WebsiteCustomer Rating:4.5/5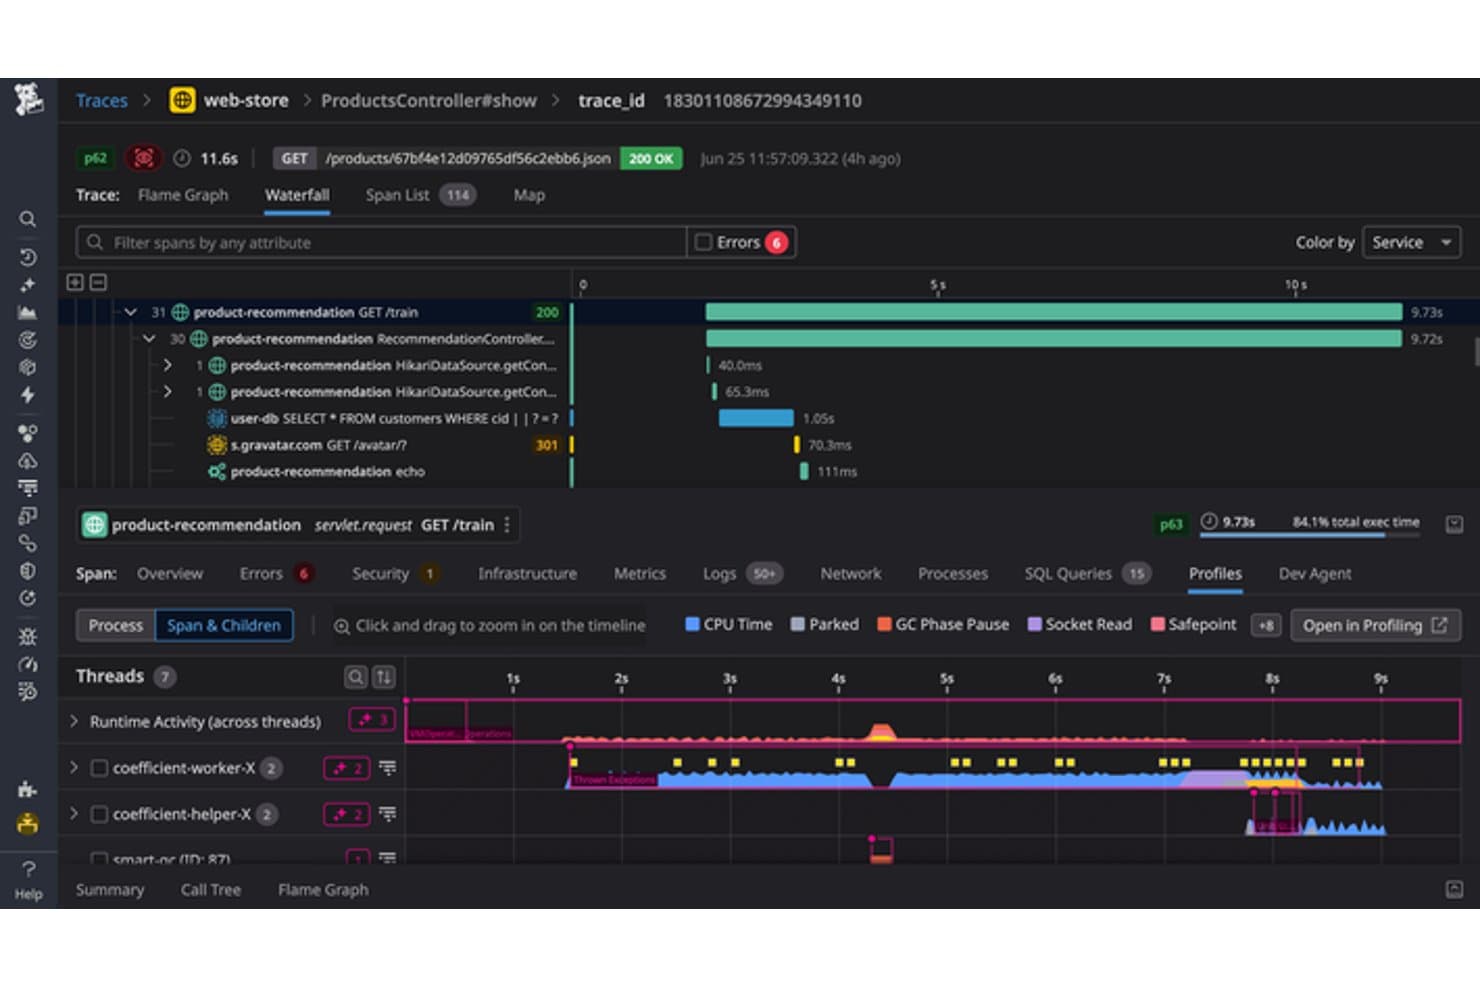
Datadog APM trace waterfall with profiling view for a product-recommendation service request. Datadog is a cloud-native monitoring platform that unifies network, infrastructure, and application visibility across multi-cloud and hybrid environments—making it a strong fit for IT operations teams that need correlated, cross-layer insights without managing multiple tools.
Who Is Datadog Best For?
Datadog suits IT operations teams managing multi-cloud and hybrid environments who need network, infrastructure, and application data in one place.
Why I Picked Datadog
I picked Datadog as one of the best PRTG alternatives because it brings cloud-native observability to network monitoring in a way traditional NMS tools simply don't. I love how Cloud Network Monitoring correlates traffic between microservices, cloud endpoints, and on-premises infrastructure in a single view, so my team can pivot from a network anomaly to the application or host behind it without switching tools. Network Path adds hop-by-hop latency and packet-loss visibility across VPCs, WANs, and SaaS providers, which makes tracing degraded paths across hybrid environments genuinely practical.
Datadog Key Features
- Network Device Monitoring: Discovers physical and virtual devices via SNMP (v1–v3), traps, NetFlow, and syslog, with auto-generated device and interface dashboards.
- Device topology map: Automatically visualizes physical network connections and upstream/downstream dependencies across your device inventory.
- NetFlow Monitoring: Collects NetFlow v5/v9, IPFIX, sFlow, and jFlow data to identify top talkers, protocols, and bandwidth usage trends.
- Multi-organization account management: Separates client data into isolated child organizations, with parent-level usage visibility and programmatic setup via API or Terraform.
Datadog Integrations
Datadog lists 1,000+ built-in integrations platform-wide, including Arista, Aruba, Cisco, Cisco Meraki, F5, and Juniper. It also offers a PRTG Marketplace integration, ServiceNow CMDB enrichment, and an HTTP REST API for custom integrations.
Pros and Cons
Pros:
- Dashboards help teams spot system health issues
- Maps hop-by-hop latency and packet loss
- Correlates network, infrastructure, and application issues
Cons:
- Network data retention trails dedicated NMS tools
- SNMP setup can be labor-intensive
 Best for customizable dashboards
- Free plan + 30-day trial + demo available
- From $2,595 one-time
Visit WebsiteCustomer Rating:4.6/5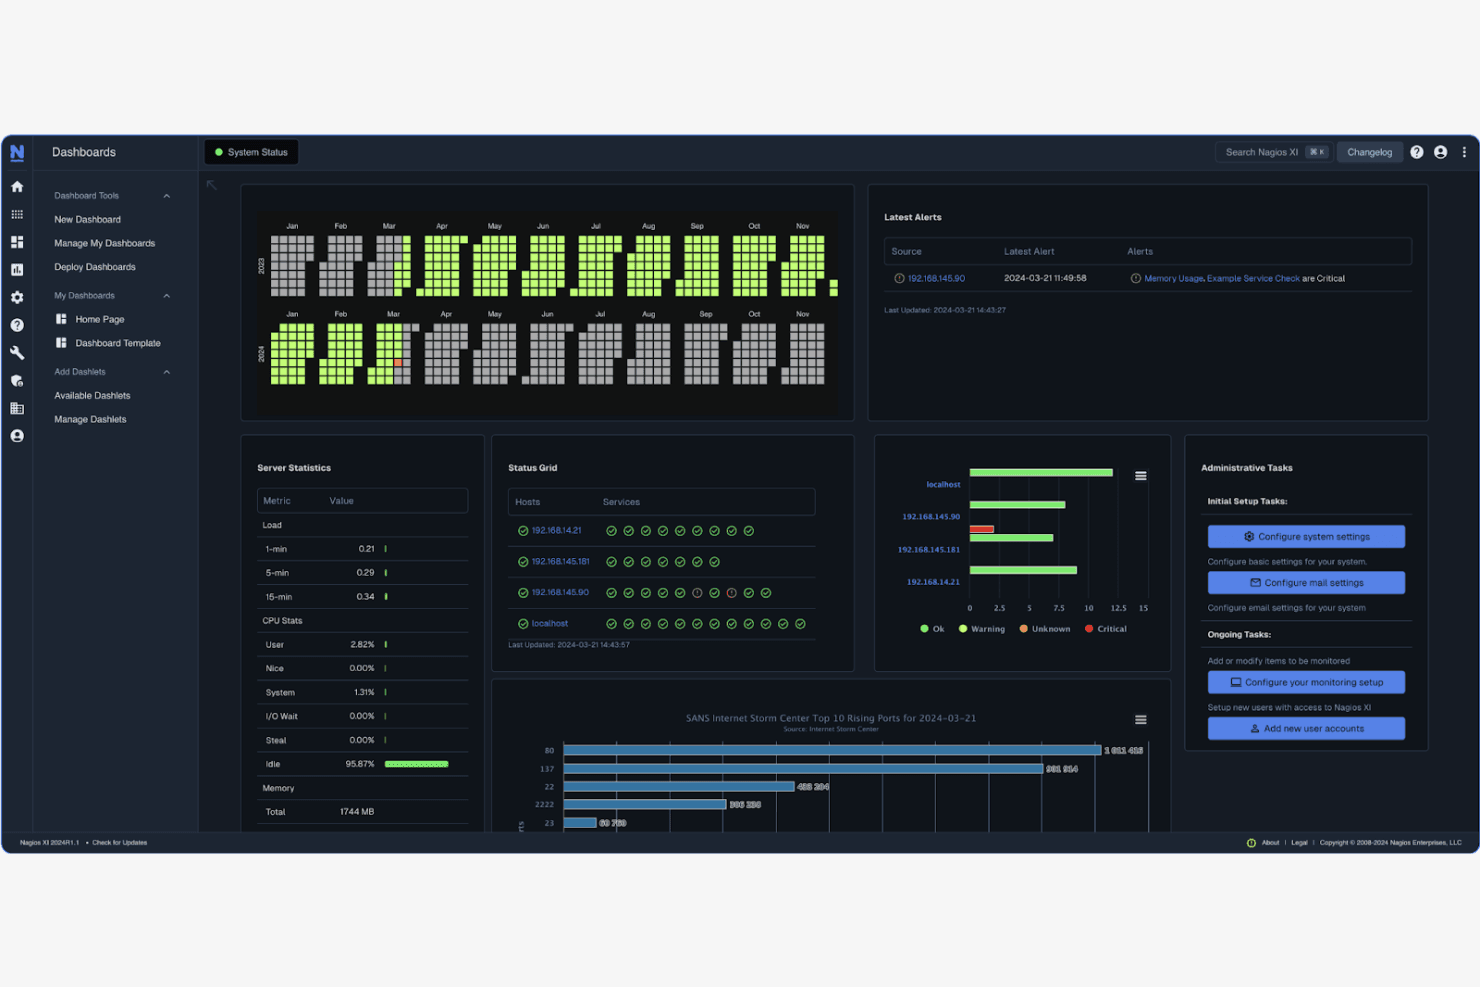
The Nagios XI dashboard summarizing alerts, host and service status, server statistics and administrative tasks. Nagios XI is a self-hosted infrastructure monitoring platform built for network administrators and IT operations teams who need granular control over how they monitor servers, network devices, and applications—without the per-sensor pricing constraints that come with PRTG.
Who Is Nagios XI Best For?
Nagios XI is a strong fit for network administrators and systems engineers who need deep control over a self-hosted monitoring environment without sensor-based licensing constraints.
Why I Picked Nagios XI
I picked Nagios XI as one of the best because its dashboard customization goes deeper than most self-hosted alternatives. Each user builds their own tactical display from dashlets covering graphs, status summaries, network maps, and gauges, and Enterprise Edition lets admins push those dashboards out to other users or sync them to a master Admin view. I also appreciate that you can schedule dashboards as PDF email attachments on a recurring cadence, which makes it easy to keep stakeholders in the loop without manual reporting work.
Nagios XI Key Features
- Per-node licensing: XI licenses by monitored node rather than by sensor or check, with no stated cap on the number of checks you run per device.
- Notification escalation policies: You can configure escalations so that after a set number of notifications, alerts automatically route to a different contact group.
- Configuration rollback: Administrators can revert configuration errors to a known-good snapshot, reducing the risk of a misconfiguration taking down monitoring.
- Capacity planning: Enterprise Edition visualizes projected future performance and can alert you when thresholds are on track to be exceeded.
Nagios XI Integrations
Nagios XI offers documented integrations with Microsoft Azure AD for SSO and Slack for notifications. It also provides a REST API for custom integrations and supports SNMP trap connectivity.
Pros and Cons
Pros:
- Distributed workers expand remote check coverage
- Dashlets tailor operator-specific infrastructure views
- Per-device licensing avoids sensor-count ceilings
Cons:
- Report templates offer limited flexibility
- Initial device integration can take substantial effort
Learn more about Nagios XI: Best for Internet Path Visibility
- 15-day free trial + demo available
- Pricing upon request
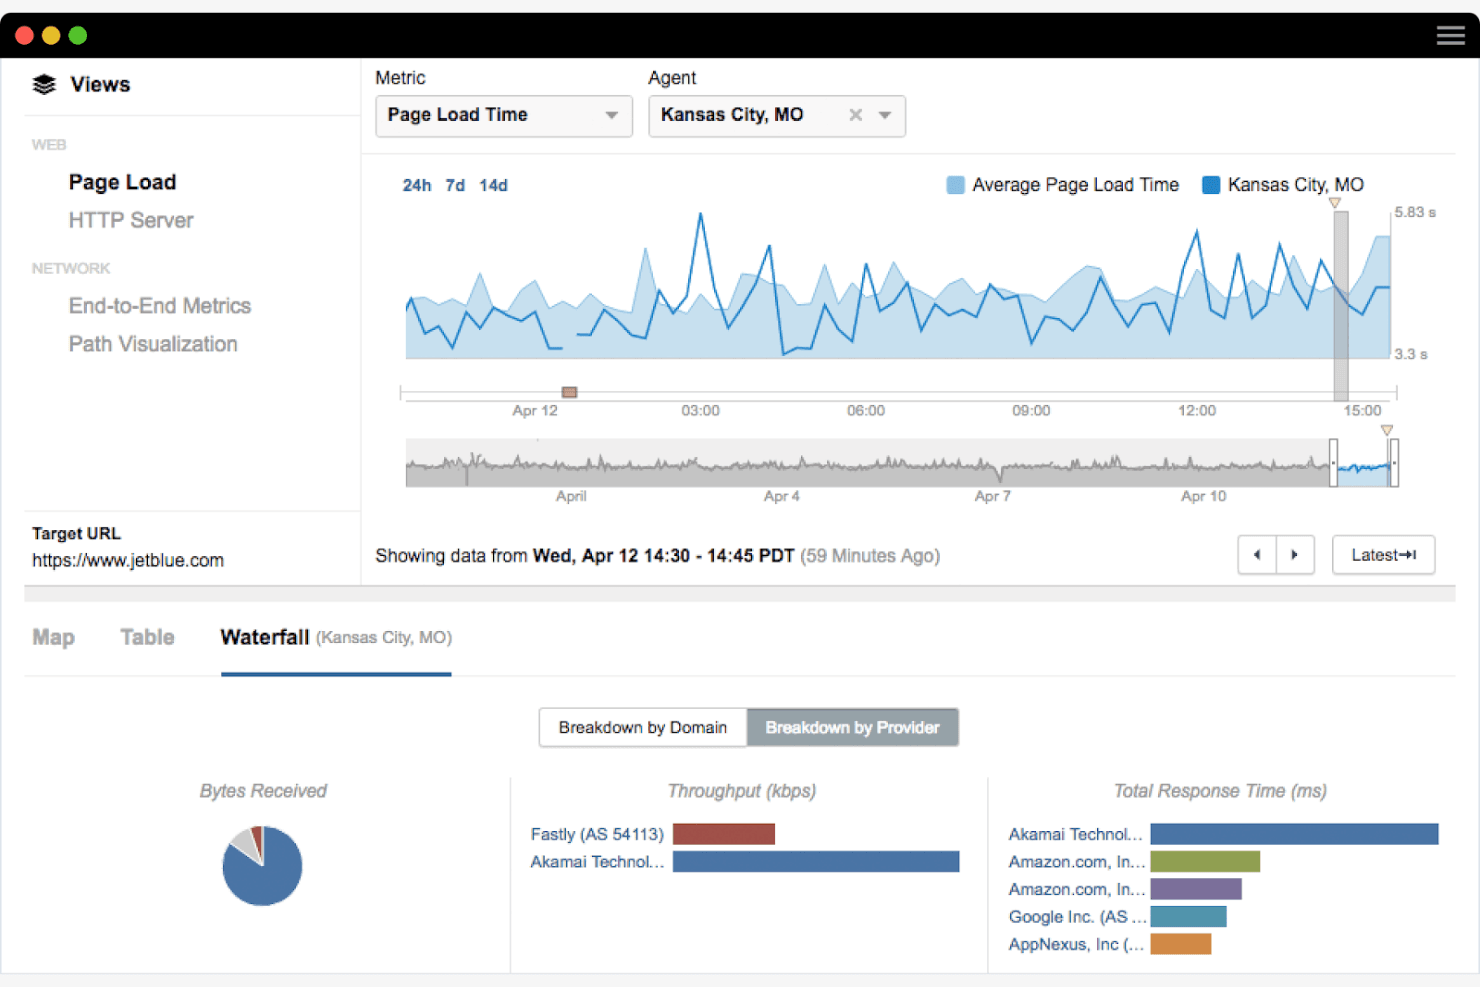
ThousandEyes Page Load view tracking page load times from a Kansas City agent, with provider-level breakdowns. ThousandEyes is a Cisco-backed network monitoring platform that gives IT teams end-to-end visibility into how traffic moves across the Internet, cloud services, and SaaS applications—making it especially useful when you need to pinpoint whether a performance issue lives inside your network or somewhere beyond it.
Who Is ThousandEyes Best For?
ThousandEyes is a strong fit for IT and network operations teams at mid-to-large enterprises that rely heavily on cloud services, SaaS applications, or distributed branch environments where Internet path visibility is the priority.
Why I Picked ThousandEyes
I picked ThousandEyes as one of the best because it does something traditional PRTG setups simply can't: it shows you exactly where in the Internet path a problem lives. When a SaaS app like Salesforce starts misbehaving, ThousandEyes' network path visualization traces every hop between your users and that service, so I can tell immediately whether the fault is inside my network, with an ISP, or in the cloud provider's infrastructure. Its Cloud Agents span 276 cities across 71 countries, giving me outside-in visibility that no on-premises sensor can replicate.
ThousandEyes Key Features
- Synthetic test types: Runs HTTP, FTP, browser, DNS, BGP route, VoIP, and UCaaS monitoring tests from Cloud and Enterprise Agents.
- SNMP device layer monitoring: Polls network devices using SNMPv2c or SNMPv3 through deployed Enterprise Agents, with manual or scheduled discovery scans.
- Multi-step API testing: Emulates backend interactions with API endpoints, validates response content, and supports assertions for data integrity and edge-case testing.
- Alert rule configuration: Supports both manual and adaptive alert rules with notification routing to PagerDuty, Slack, ServiceNow, or custom webhooks.
ThousandEyes Integrations
ThousandEyes offers documented integrations with PagerDuty, Slack, ServiceNow, Splunk Observability Cloud, AppDynamics, OpenTelemetry, and CyberArk Secrets Manager. It also provides a REST API and custom webhooks for additional integrations.
Pros and Cons
Pros:
- Compares performance from global network vantage points
- Exposes latency, packet loss, and SaaS connectivity issues
- Pinpoints faults across external network paths
Cons:
- Device polling covers fewer protocols than PRTG
- Limited local telemetry for switches and servers
Learn more about ThousandEyes: Best for unified endpoint management
- 14-day free trial + free demo available
- From $3.75/month
Visit WebsiteCustomer Rating:5/5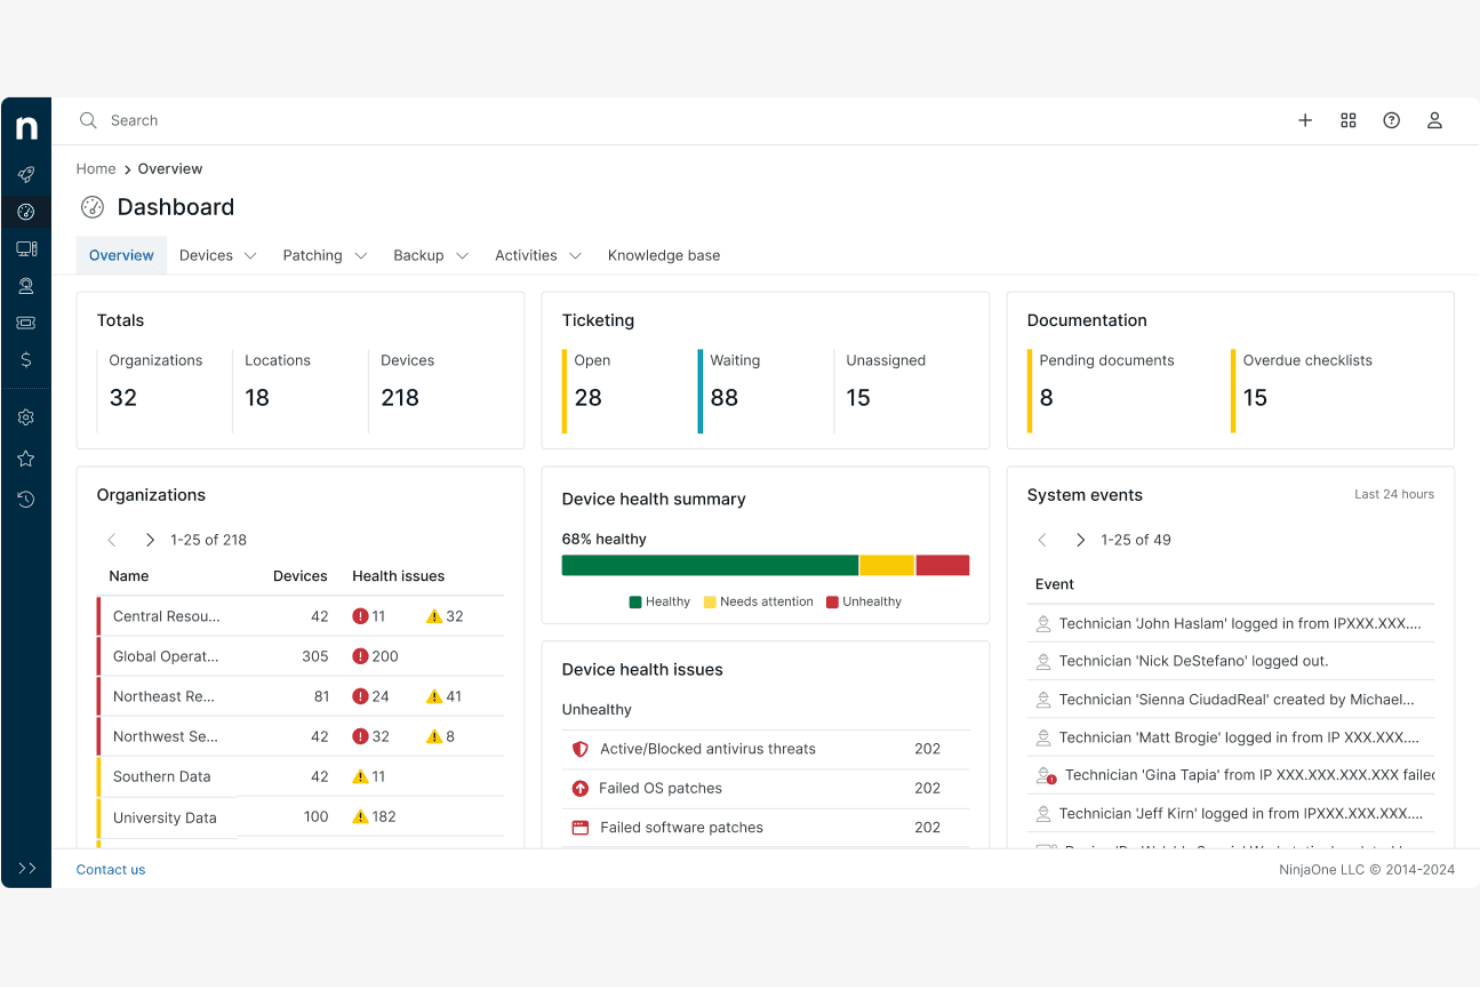
NinjaOne's dashboard overview, summarizing devices, organizations, tickets, device health and system events in one view. NinjaOne RMM is an endpoint and network monitoring platform built for MSPs and IT teams that need centralized visibility across endpoints, network devices, and cloud infrastructure—with built-in patching, alerting, and remote management tools to reduce manual work.
Who Is NinjaOne Best For?
NinjaOne is a strong fit for MSP technicians and IT operations teams managing endpoints across multiple client environments from a single console.
Why I Picked NinjaOne
I picked NinjaOne as one of the best PRTG alternatives because it brings endpoint monitoring, network device visibility, and automated remediation into a single console, which is exactly what MSP technicians managing multiple client environments need. I like that NMS is built directly into the RMM, so my team can monitor routers, switches, and firewalls alongside Windows, macOS, and Linux endpoints without switching tools. Policy-based conditions let me set thresholds for CPU, memory, adapter traffic, and ping latency, then trigger automatic remediations when those thresholds are crossed.
NinjaOne Key Features
- Multi-channel alerting: Configure notification channels including email, SMS, Slack, PagerDuty, Microsoft Teams, and webhooks to deliver threshold-based alerts to your team.
- Condition-based auto-remediation: Define script workflows that automatically detect and resolve endpoint issues like stopped services, open ports, or missed reboots without technician intervention.
- Flow monitoring support: Collect and analyze NetFlow, JFlow, sFlow, and IPFIX data from supported network devices to gain visibility into traffic patterns.
- Public API and webhooks: Access NinjaOne data and trigger actions programmatically using an OAuth 2.0 API with full POST, GET, PATCH, DELETE, and PUT method support.
NinjaOne Integrations
NinjaOne lists integrations with ServiceNow, Autotask, ConnectWise Manage, HaloPSA, Slack, PagerDuty, Microsoft Azure, and AWS. Its OAuth 2.0 Public API and webhooks support custom integrations and monitoring workflows.
Pros and Cons
Pros:
- Monitors flow data alongside device health metrics
- Policy automation helps reduce routine response work
- Centralizes endpoint and network visibility across clients
Cons:
- Limited documented retention for performance history
- Network monitoring can require manual OID mapping
Learn more about NinjaOne: Best for automatic network discovery
- Free plan + free demo available
- Pricing upon request
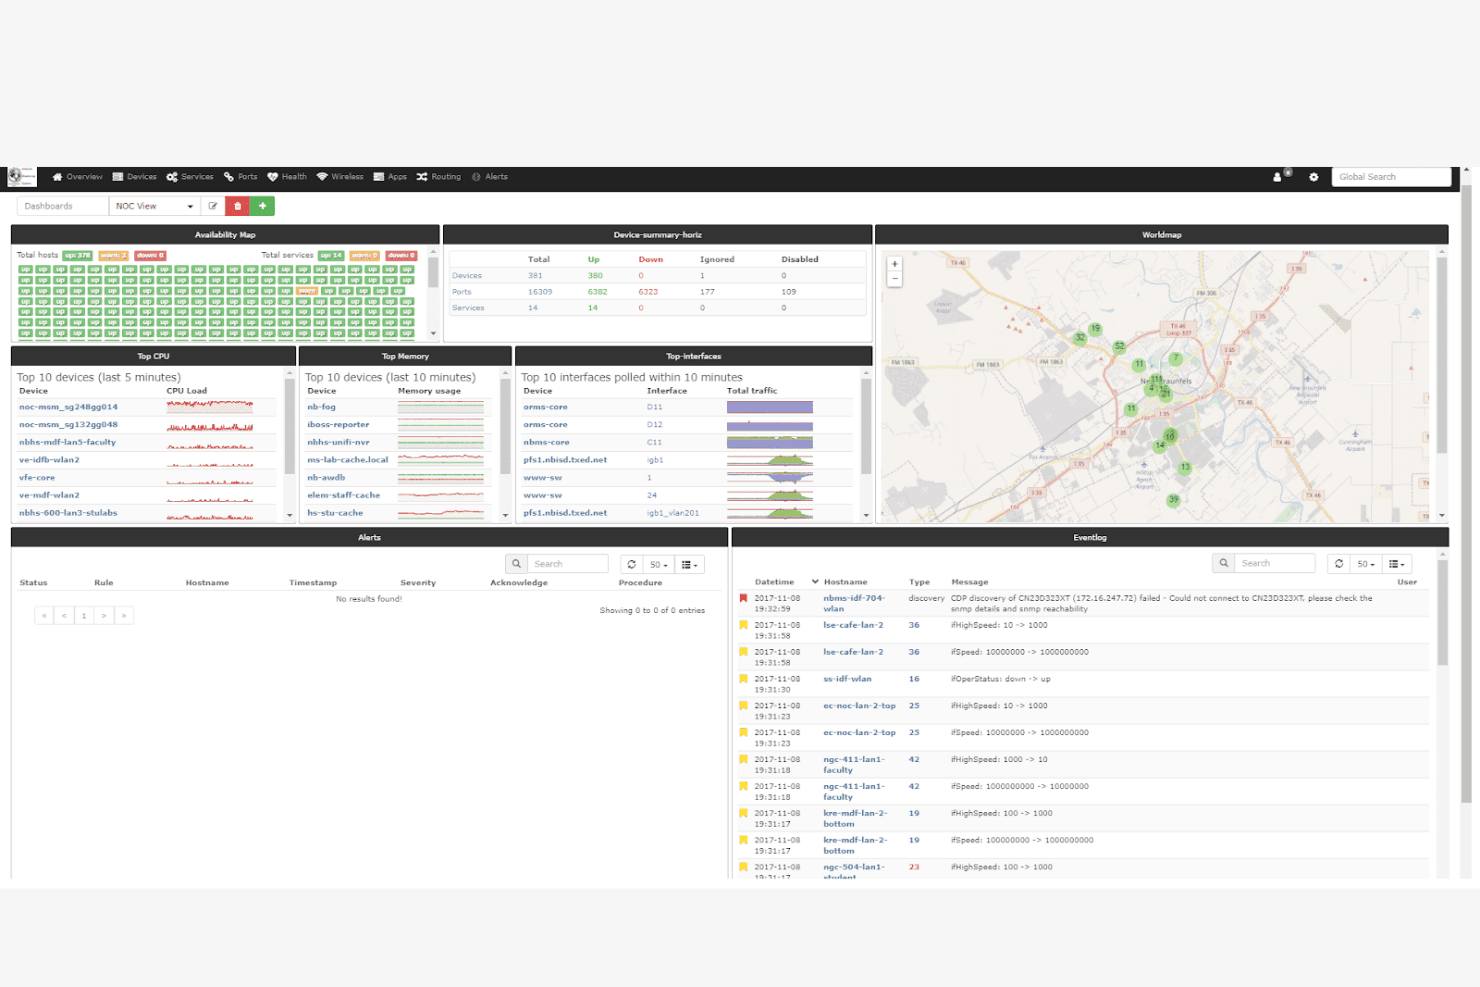
LibreNMS NOC dashboard showing device availability, top CPU and memory usage, interface traffic, and a live event log. LibreNMS is a free, open-source network monitoring system that appeals to systems engineers and network administrators who need broad device discovery and infrastructure visibility without the cost or licensing restrictions of commercial tools.
Who Is LibreNMS Best For?
LibreNMS is a strong fit for systems engineers and network administrators who want broad device discovery and infrastructure visibility without sensor-based licensing costs.
Why I Picked LibreNMS
I picked LibreNMS as one of the best because its automatic network discovery is genuinely impressive: it uses CDP, LLDP, OSPF, BGP, SNMP, and ARP to find devices on your network without manual input. I've seen it pull in routers, switches, and access points quickly after setup, which is exactly what you need when you're replacing a sensor-limited tool like PRTG. The built-in ICMP availability checks and application monitoring for services like NGINX, MySQL, and Docker round out the visibility you get from day one.
LibreNMS Key Features
- Customizable alert operations: Configure multi-step notification workflows with timed segments that escalate across transports like Slack, email, and Telegram until an alert is resolved or acknowledged.
- Bandwidth billing system: Generate bills for network ports based on actual usage or data transfer volume directly within the platform.
- Distributed polling: Spread polling and discovery tasks across multiple servers by assigning devices to poller groups as your network grows.
- Multi-protocol application monitoring: Collect application statistics from services like MySQL, NGINX, Docker, and PostgreSQL via direct connection, SNMP extend, or the Check_MK agent.
LibreNMS Integrations
Documented integrations include NfSen, collectd, SmokePing, RANCID, and Oxidized. LibreNMS also provides an HTTP API with JSON and PNG responses for custom integrations, device management, graph generation, and data retrieval.
Pros and Cons
Pros:
- Tracks uptime and network performance
- Escalating alerts across notification channels
- Broad automatic device discovery
Cons:
- Distributed polling isn’t built for remote sites
- Limited native reporting options
Learn more about LibreNMS: Best for synthetic network monitoring
- Free plan + 14-day trial + free demo available
- From $249/month
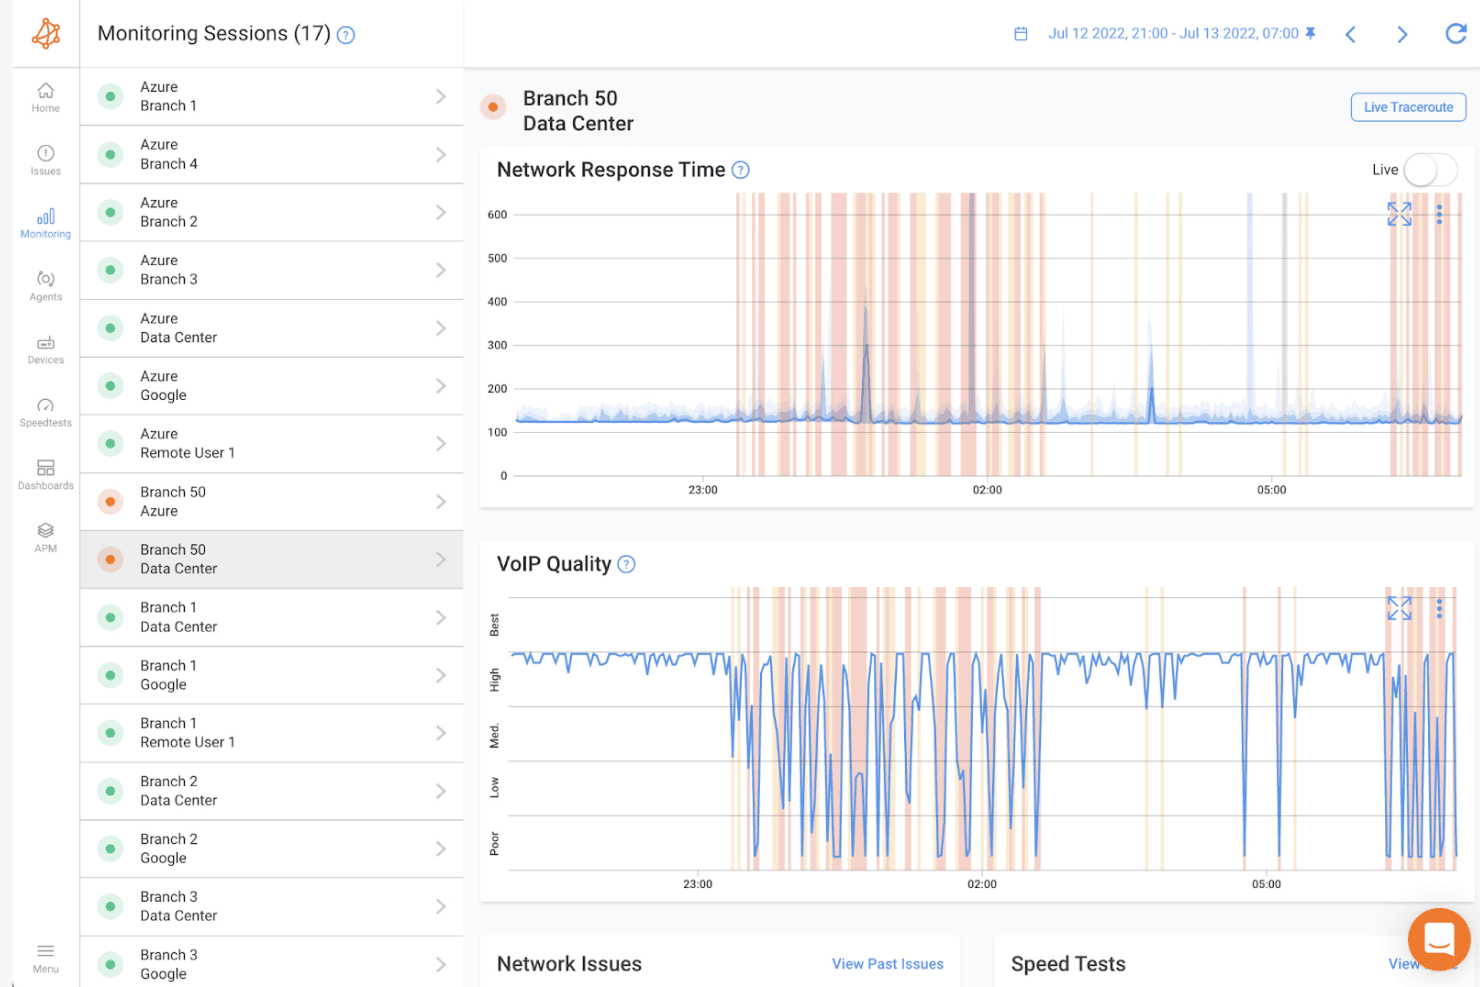
Obkio's monitoring dashboard tracking network response time and VoIP quality across branch and data center sessions. Obkio is a cloud-based network performance monitoring tool that uses synthetic traffic between distributed agents to help network administrators and MSPs detect, diagnose, and troubleshoot latency, packet loss, and connectivity issues across multi-site environments.
Who Is Obkio Best For?
Obkio is a strong fit for network administrators and MSP technicians who need to monitor performance across distributed, multi-site environments using synthetic traffic.
Why I Picked Obkio
Obkio earns its spot on my shortlist because of how it approaches network monitoring differently from PRTG: instead of polling devices from a single point, it deploys agents at every site and continuously exchanges synthetic UDP traffic between them every 500 milliseconds. I particularly like the Chord Diagram, which gives a live, bidirectional view of connection health across all locations. The Obkio Insights feature also automatically correlates performance data, SNMP metrics, and traceroute results to surface a probable root cause without manual digging.
Obkio Key Features
- SNMP device monitoring: Monitors routers, switches, firewalls, and Wi-Fi access points, automatically collecting CPU usage, bandwidth utilization, interface errors, and availability via SNMP v1, v2c, or v3.
- Visual traceroutes: Runs continuous, automatic traceroutes alongside monitoring sessions and displays per-hop latency, packet loss, and jitter in interactive, color-coded path maps.
- Multi-channel alerting: Sends threshold-based notifications through email, Slack, Microsoft Teams, PagerDuty, ServiceNow, or HTTP webhooks, with configurable severity levels and smart event grouping.
- Scheduled reporting: Automatically generates Excel, PDF, or JSON reports on a daily, weekly, or monthly schedule and emails them to recipients who don't need an Obkio account.
Obkio Integrations
Obkio offers four documented native integrations: Microsoft Teams, PagerDuty, ServiceNow, and Slack. It also supports HTTP webhooks for notifications and completed reports, but a general public API wasn't documented.
Pros and Cons
Pros:
- Reviewers praise clear network health visualizations
- Synthetic probes catch brief WAN degradations
- Bidirectional visibility across distributed sites
Cons:
- Reviewers want better historical report exports
- Device polling depends on local collector agents
Learn more about Obkio: 10Best for automated network mapping
Auvik
- 14-day free trial + demo available
- Pricing upon request
Visit WebsiteCustomer Rating:4.7/5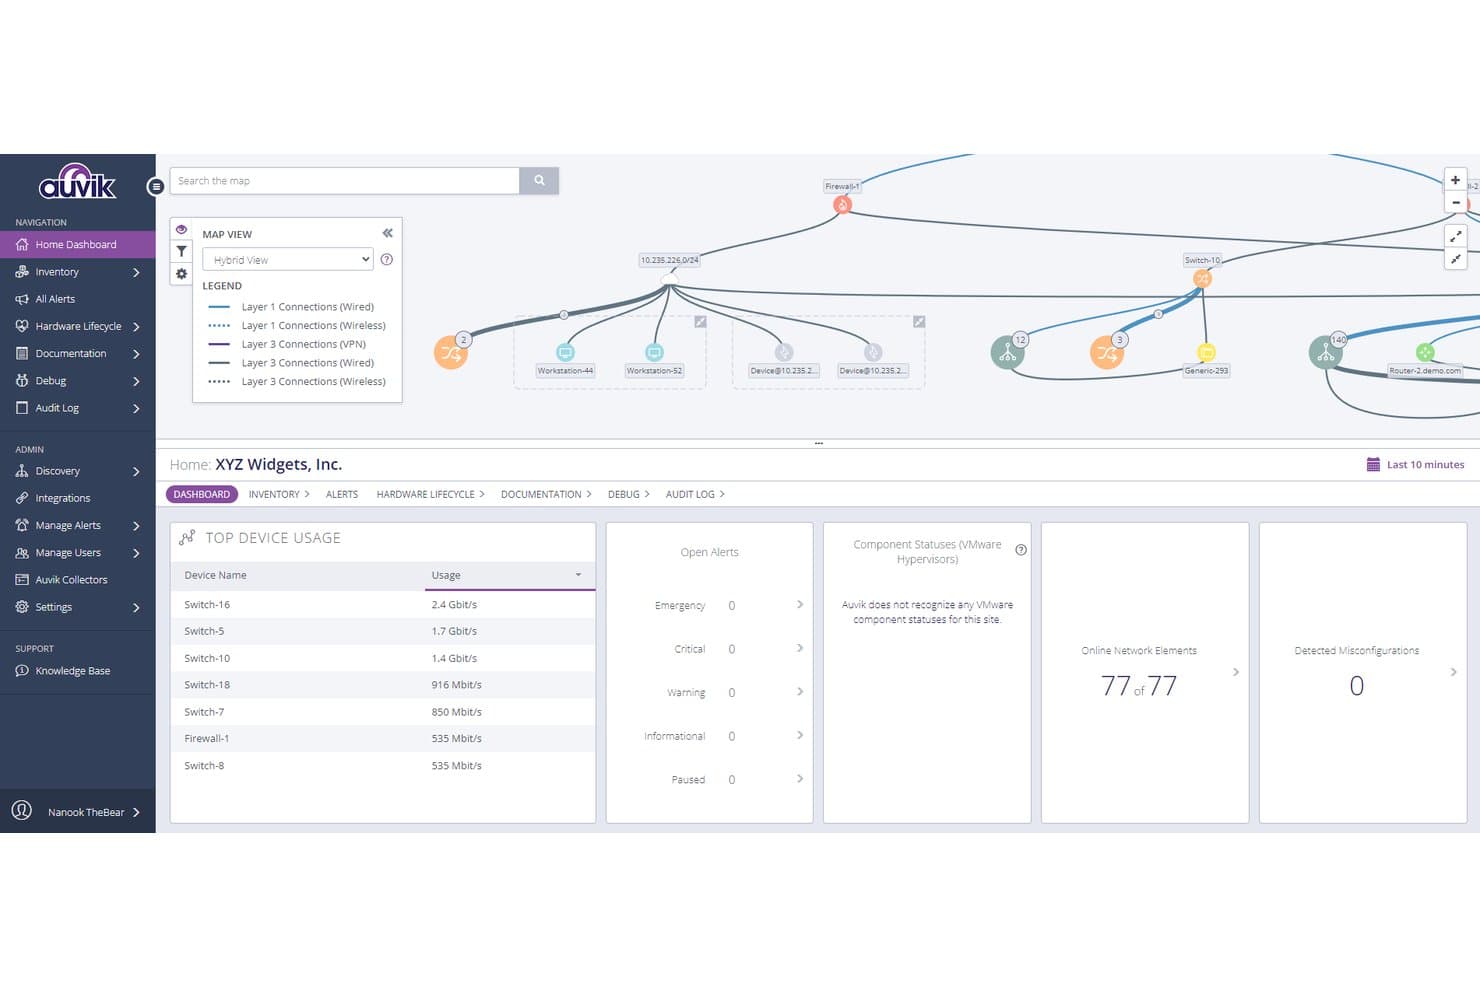
Auvik's home dashboard combines a live network map with device usage and alert summaries. Auvik is a cloud-based network management platform built for IT teams and MSPs that need automated device discovery, live topology mapping, and multi-site visibility without the manual overhead of documenting and maintaining network records.
Who Is Auvik Best For?
Auvik is a natural fit for MSP technicians and network administrators who need to monitor and document multi-site client environments without spending hours on manual discovery and mapping.
Why I Picked Auvik
I picked Auvik as one of the best because automated network mapping is where it genuinely outperforms what PRTG offers out of the box. The moment a collector is deployed, Auvik discovers every IP-connected device and renders a live topology map across Layers 1, 2, and 3, updating continuously as your network changes. I especially like that it retains historical topology snapshots, so I can see exactly what the network looked like before an incident occurred.
Auvik Key Features
- Multi-layer traffic analysis: Auvik ingests NetFlow v5/v9, J-Flow, IPFIX, and sFlow data to show top talkers, bandwidth-heavy applications, and protocol-level traffic breakdowns across your network.
- Automated configuration backups: Auvik continuously backs up device configurations, tracks version history, and lets you compare changes side by side for audit and troubleshooting purposes.
- Preconfigured alert library: Auvik ships with over 50 ready-to-use alerts covering device status, interface utilization, packet errors, latency, jitter, and syslog events, with customizable thresholds.
- MSP tool integrations: Auvik connects natively with ConnectWise Manage, Datto Autotask, and IT Glue to sync device inventory and bi-directionally manage tickets across client environments.
Auvik Integrations
Auvik has native integrations with ConnectWise Manage, Datto Autotask, ServiceNow, PagerDuty, Slack, Microsoft Teams, and Opsgenie. It also provides APIs and webhooks for custom integrations, including a generic incoming webhook.
Pros and Cons
Pros:
- Configuration history helps trace network changes
- Centralized views cover multiple client sites
- Automated topology maps speed troubleshooting
Cons:
- Default alerts can create noisy false positives
- Some maps need manual cleanup
Learn more about Auvik:
Other PRTG Alternatives
Here are some additional PRTG alternatives that didn’t make it onto my shortlist, but are still worth checking out:
Related Reviews
How I Evaluate PRTG Alternatives
I split my evaluation into two layers: the baseline capabilities—like SNMP device monitoring and threshold alerting—a tool must have to replace PRTG, and the differentiators that set options apart.
Core Functionality (Table Stakes For This List)
When I'm selecting tools for my list, I rank each one on a scale from 0 (does not offer the functionality) to 5 (excels in this area) for each core functionality listed below. Then, I calculate the tool's total score into a percentage. Each tool needs to achieve a minimum total score of 65% to be considered for inclusion.
- Network Device Monitoring: I check for multi-protocol support (SNMP, ICMP, NetFlow) and pre-built templates that cover routers, switches, firewalls, and wireless APs from major vendors.
- Server & Infrastructure Monitoring: Each tool should track OS-level metrics across Windows and Linux, plus support for VMware, Hyper-V, containers, and cloud providers like AWS and Azure.
- Alerting & Notification System: I look at threshold configuration depth and multi-channel delivery options, including whether alerts integrate with tools like PagerDuty, Slack, or Teams.
- Dashboards & Visualization: Real-time dashboards with topology maps and drill-down views matter here, especially for NOC teams who need at-a-glance status across hundreds of devices.
- Historical Reporting & Analytics: I evaluate data retention flexibility, SLA and uptime report generation, and whether capacity planning trends are easy to pull for stakeholder presentations.
- Auto-Discovery & Scalability: The tool should scan and map assets automatically, and I pay close attention to how licensing and architecture handle growth across distributed sites.
Once I have a list of tools that meet this criteria, I consider what sets each platform apart.
Differentiating Factors (What Sets Vendors Apart)
Here's how I compare and contrast different vendors:
Standout Features
AI-powered anomaly detection is a big differentiator. Tools that baseline normal traffic patterns and flag deviations catch issues that static thresholds miss entirely—like a slow memory leak on a production server. I also look for built-in log management, since correlating syslog data with performance metrics during an outage saves real time over switching between separate tools. For MSP teams, multi-tenant support with client isolation and white-labeled dashboards determines whether a platform can scale across customer environments.
Beyond Features
Licensing structure matters a lot when you're switching from PRTG. I evaluate whether pricing scales predictably as you add devices—per-sensor models can get expensive fast across a 1,000-node environment. Deployment flexibility is another factor I check, since some teams need on-prem installs for air-gapped networks while others prefer SaaS. I also consider the integration ecosystem, specifically native connections with ITSM tools like ServiceNow or Jira, because monitoring data is most useful when it feeds directly into your incident response workflows.
Why Look for a PRTG Alternative?
While PRTG is a good choice for monitoring tools, there are several reasons some users seek alternative solutions. You might be looking for a PRTG alternative because…
- You need better scalability for growing networks
- You're looking for more customization options
- Your team needs easier integration with cloud services
- You require more advanced analytics features
- You're seeking a more intuitive user interface
If any of these sound like you, you’ve come to the right place. My list contains several monitoring tools options that are better suited for teams facing these challenges with PRTG and looking for alternative, cost-effective solutions.
PRTG Key Features
Here are some of the key features of PRTG, to help you contrast and compare what alternative solutions offer:
- Network and server monitoring: Provides real-time monitoring for routers, switches, firewalls, and more, ensuring your network runs smoothly.
- Bandwidth monitoring: Tracks bandwidth usage to help you understand network traffic patterns and prevent bottlenecks.
- Customizable dashboards: Offers real-time maps and dashboards that you can tailor to display the most important metrics for your team.
- Alerts and notifications: Sends customizable alerts via email, SMS, or push notifications to keep you informed of any issues.
- Distributed monitoring: Allows centralized monitoring of multiple remote locations and data centers, providing a full view of your entire network.
- Custom reporting: Enables you to create tailored reports to communicate the status of your IT infrastructure effectively.
- SNMP monitoring: Supports SNMP for monitoring various network devices, ensuring compatibility with a wide range of hardware.
- Wi-Fi monitoring: Monitors Wi-Fi networks to ensure reliable connectivity and performance across your wireless infrastructure.