

10 Best LLM Observability Tools in 2026

Best LLM Observability Tools Shortlist


LLM observability tools trace AI workflows, monitor production behavior, and evaluate model quality. This guide compares 12 options for debugging multi-step agents, tracking prompts and model versions, measuring latency and token usage, and catching regressions before deployment. You’ll find open-source, self-hosted, enterprise, OpenTelemetry-based, and developer-focused platforms to match your technical architecture, governance needs, and delivery workflow.
Why Trust Our Software Recommendations
Our team has been testing and reviewing software since 2012. As tech leaders ourselves, we know how difficult—and important—it is to choose the right software.
For this guide, we evaluated tools using hands-on testing and independent research, scoring tools using our selection criteria.
Our reviews reflect our human editorial judgment, not a sales pitch.
Compare the Best LLM Observability Tools
Compare pricing and specs, side by side, for the top platforms on my shortlist.
| Tool | Best For | Trial Info | Price | ||
|---|---|---|---|---|---|
| 1 | Best for open-source OTel-native tracing | Free plan + free demo available | Pricing upon request | Website | |
| 2 | Best for open-source, self-hosted evaluation at scale | Free plan available | Pricing upon request | Website | |
| 3 | Best for full-lifecycle LLM evaluation with gateway ops | Free plan + free demo available | Pricing upon request | Website | |
| 4 | Best for open-source evaluation and tracing | Free plan + free demo available | From $19/month | Website | |
| 5 | Best for linking prompt versions to production traces | Free plan + free demo available | From $49/month | Website | |
| 6 | Best for tracing agents across complex pipelines | Free plan + free demo available | From $50/month | Website | |
| 7 | Best for linking LLM traces to product analytics | Free plan available | From $250/month | Website | |
| 8 | Best for open-source tracing with prompt versioning | Free plan + free demo available | From $29/month | Website | |
| 9 | Best for evaluation-to-production scoring in one loop | Free plan + free demo available | From $249/month | Website | |
| 10 | Best for LangChain and LangGraph tracing | Free plan + free demo available | From $39/user/month | Website |
LLM Observability Tools Reviews
Below are detailed summaries of the top picks on my shortlist. Each review covers key features, use cases, and integrations to help you find the right fit.
Best for open-source OTel-native tracing
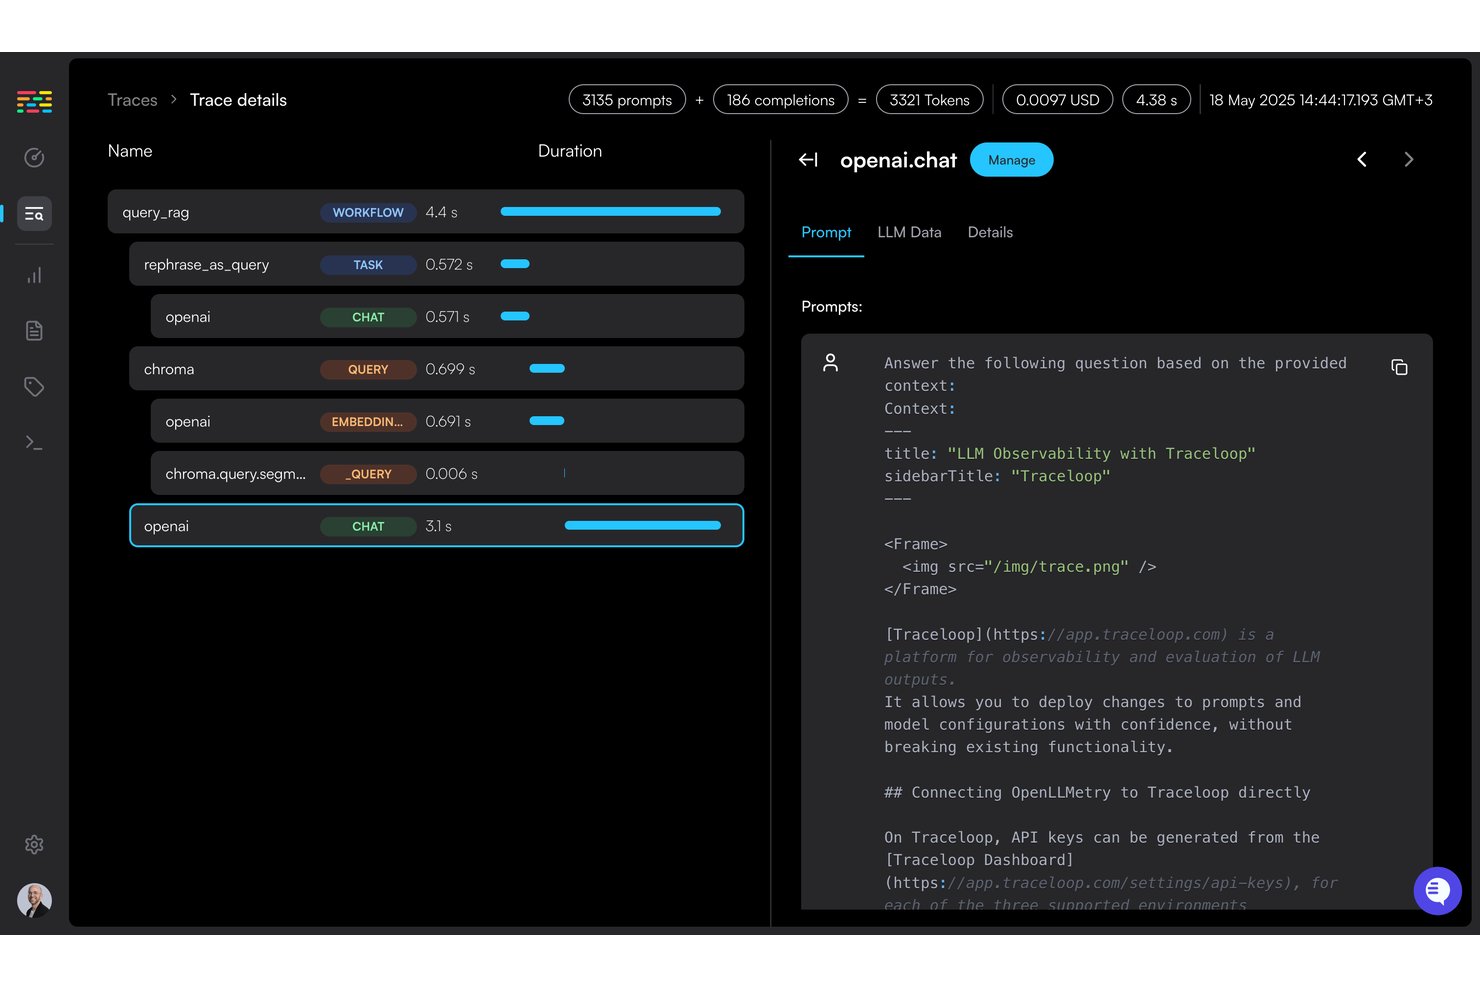
Traceloop by ServiceNow is built on OpenTelemetry, which gives you span-based trace logging, output quality evaluation, a prompt registry with environment-based deployments, production monitors, and CI/CD quality gates.
Who Is Traceloop Best For?
Traceloop suits platform and DevOps engineers who need compliant, self-hosted LLM observability on Kubernetes or air-gapped infrastructure.
Why I Picked Traceloop
I've included Traceloop in my top picks because it's built entirely on OpenTelemetry through its open-source OpenLLMetry SDK, which means every LLM call, vector DB query, and agent step is recorded as a native OTel span you can export to 25+ backends. I particularly like the evaluator pipeline: you can run the same quality checks as CI/CD gates on pull requests, inline guardrails in production, and real-time monitors on live traffic simultaneously. The prompt registry with environment-based deployments also lets you roll out prompt changes to dev before production, keeping version control tight across the full lifecycle.
Traceloop Key Features
- Built-in evaluators: Automatically check faithfulness, relevance, and safety on live traffic with no manual setup required.
- Agent-focused evaluation checks: Score agent outputs across correctness, tool usage, memory retention, task completion, and safety.
- Production monitors: Run evaluators in real time on every span matching a filter to detect hallucinations and quality regressions.
- Inline guardrails: Execute safety checks in real time during inference, built directly from your configured evaluators.
Traceloop Integrations
Traceloop supports 20+ LLM providers, including Axiom, Braintrust, BMC, Google Cloud, Highlight, Honeycomb, Instana, OpenTelemetry Collector, Datadog, Oracle Cloud, and Tenant Cloud. An API for creating custom LLM-as-a-judge evaluators is also available.
Pros and Cons
Pros:
- Self-hosting supports air-gapped deployments
- Evaluations span CI/CD through production
- Native tracing reduces vendor lock-in
Cons:
- Public cost attribution details remain limited
- ServiceNow acquisition creates roadmap uncertainty
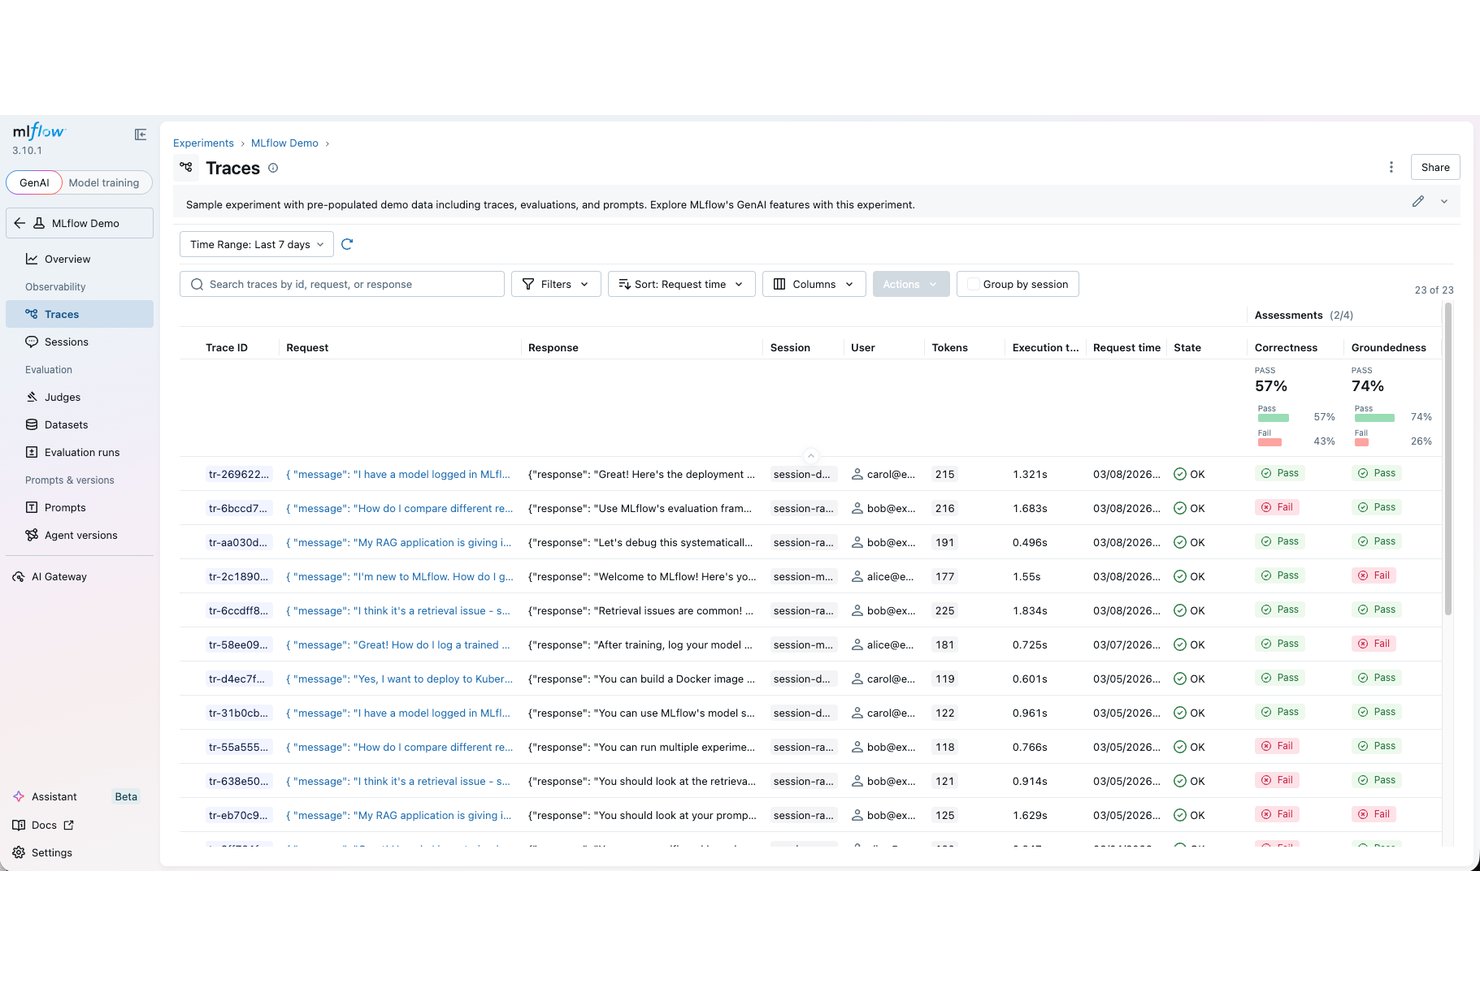
MLflow is an open-source AI observability platform that combines trace logging, output quality evaluation, prompt versioning, cost and token tracking, and production monitoring for LLM applications and AI agents.
Who Is MLflow Best For?
MLflow suits ML/AI engineers and data scientists who need full control over their observability infrastructure and want to avoid per-trace fees or vendor lock-in.
Why I Picked MLflow
I've included MLflow in my top picks because it's the only tool here built as Apache 2.0 open source from the ground up, meaning your trace data never leaves your own infrastructure. I like that the Prompt Registry links every prompt version directly to its evaluation results, so you can run A/B tests on variants and see quality, latency, and safety scores side by side before promoting anything to production. The asynchronous LLM judges also score sampled traces continuously without slowing down live traffic.
MLflow Key Features
- Prompt Registry: Version, test, and compare prompts side by side, with lineage tracking and automatic prompt optimization to tune prompts algorithmically.
- Guardrails and safety detection: Real-time scoring detects prompt injection, PII leakage, and jailbreaks using both deterministic and LLM-based detectors, with PII redaction available in the SDK.
- Evaluation dataset management: Build and store test case datasets from production traces, with structured feedback from users and domain experts feeding back into judge calibration.
- AI Gateway with budget policies: Set spending thresholds per day, week, or month across providers, with webhook alerts to tools like Slack or PagerDuty when limits are crossed.
MLflow Integrations
MLflow integrates with 40+ LLMs and AI agents, including OpenAI Agent, Anthropic, LlamaIndex, Agno, Amazon Bedrock, Groq, OpenTelemetry, and TypeScript. The REST API is also available for custom connections.
Pros and Cons
Pros:
- Prompt lineage connects changes with evaluations
- Production judges score hallucinations and drift
- Self-hosted traces keep data in-house
Cons:
- Alerting options remain less clearly documented
- Nested agent traces can become confusing
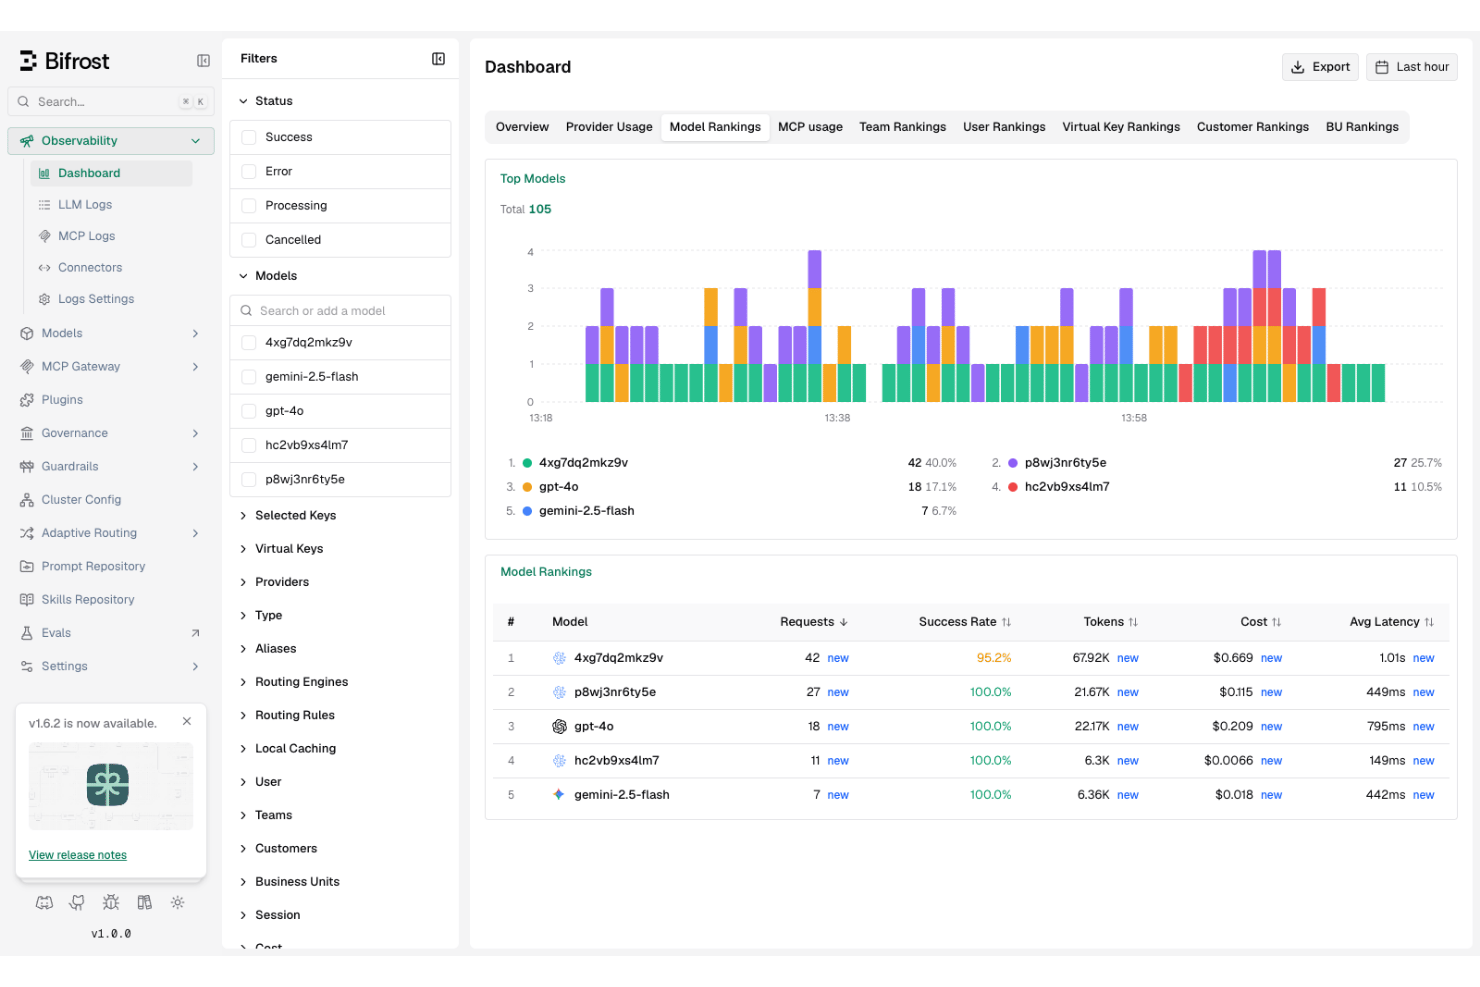
Bifrost is an LLM observability platform that covers the full development lifecycle, combining distributed tracing, prompt versioning and experimentation, automated and human-in-the-loop evaluation, and an open-source LLM gateway.
Who Is Bifrost Best For?
Bifrost is a great fit for regulated enterprise teams that need in-VPC deployment, SOC 2 Type II, HIPAA compliance, and human-in-the-loop evaluation in one platform.
Why I Picked Bifrost
The full-lifecycle coverage is what keeps Bifrost on my shortlist. I use it to run A/B tests on prompt versions in the Prompt IDE, then carry those same datasets directly into production evaluation without any manual export step. What I find genuinely useful is that the open-source Bifrost gateway layers on budget tracking per team or virtual key alongside gateway-level rate limits, so I can manage cost governance and observability from one connected setup rather than two separate tools.
Bifrost Key Features
- Prompt IDE with version comparison: A multimodal prompt playground where you can run experiments across combinations of prompts, models, context, and tools, with side-by-side version diffing.
- Agent simulation: Test agent interactions across different scenarios and user personas, including voice agents, before pushing changes to production.
- CI/CD pipeline integration: Plug evaluation runs directly into your deployment pipeline, with scheduled runs available on the Business tier and above.
- OpenTelemetry compatibility: Export trace data to external platforms like New Relic and Snowflake using OTel-native forwarding, with SDKs in Python, TypeScript, Go, and Java.
Bifrost Integrations
Bifrost supports integration across AI SDKs, secret management platforms, and identity systems, including OpenAI, Anthropic, Google GenAI, AWS Bedrock, LiteLLM, AWS Secrets Manager, Google Secret Manager, and Okta. An API for custom connections is also available.
Pros and Cons
Pros:
- Combines automated scoring with human review
- Traces sessions, requests, and individual spans
- Connects experimentation, evaluation, and observability
Cons:
- Granular cost attribution remains unclear
- Short retention limits historical investigations
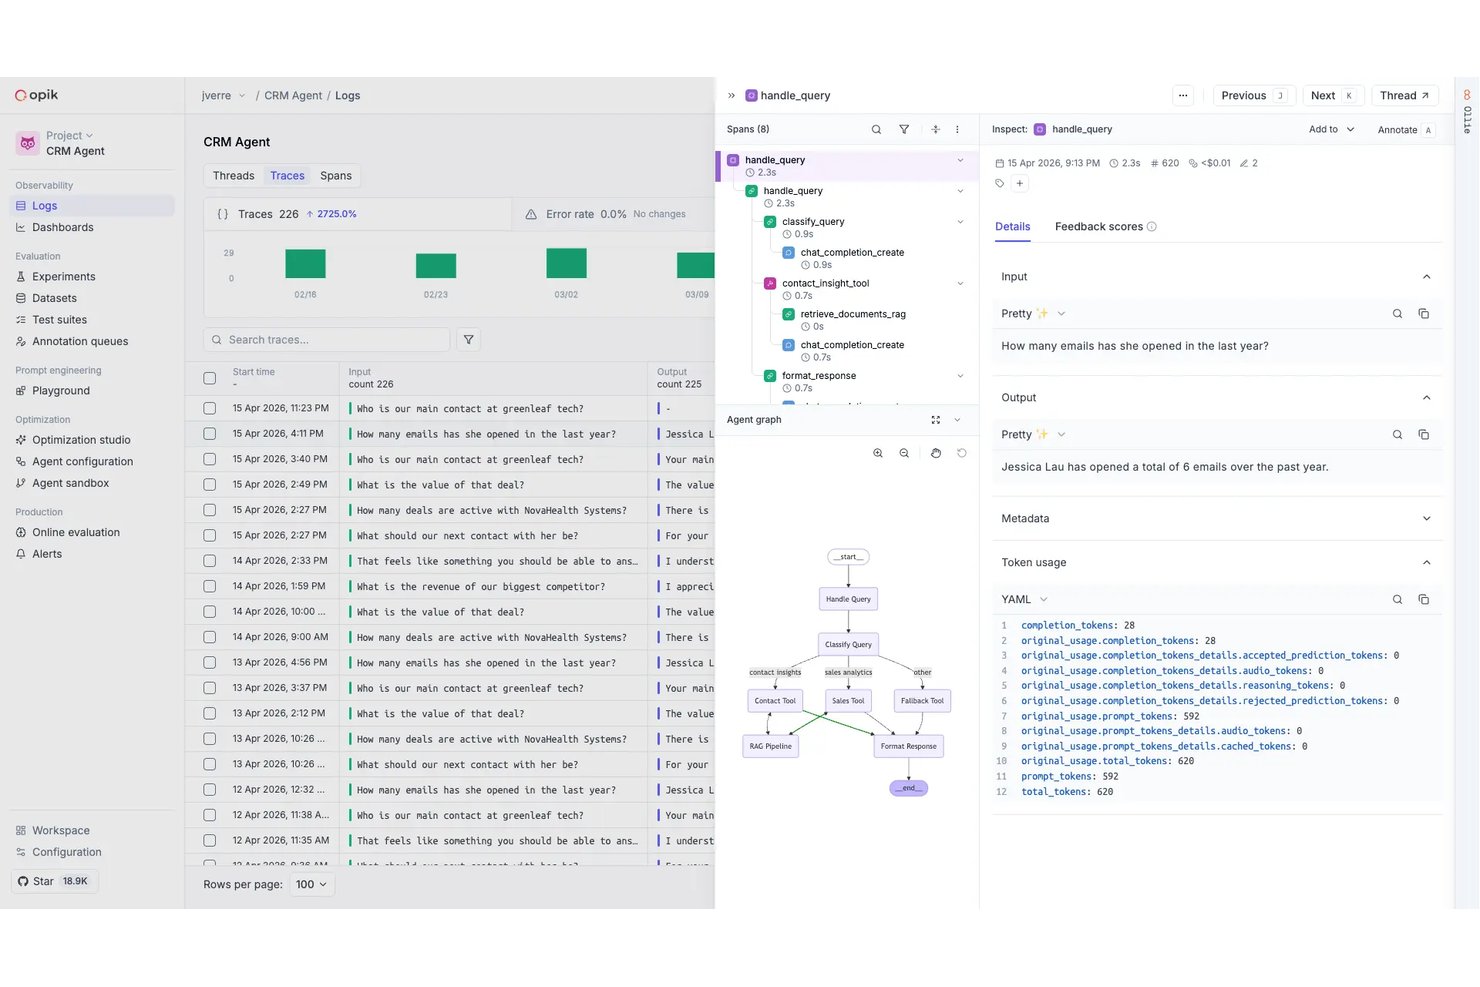
Opik is an LLM observability platform that covers trace logging, output quality evaluation, prompt versioning, and cost tracking across LLM applications, agents, and RAG pipelines.
Who Is Opik Best For?
Opik is a strong fit for ML/AI engineers and LLMOps teams who want open-source flexibility with the option to scale into a fully managed, enterprise-grade deployment.
Why I Picked Opik
I picked Opik as one of the best because its open-source core is genuinely full-featured, not a stripped-down teaser. I love that you can self-host it with unlimited users, spans, and retention using the same codebase as the cloud version. For evaluation depth specifically, Opik ships 30+ LLM-as-a-judge metrics alongside Test Suites that run pass/fail assertions, A/B tests, and regression tests against versioned prompts, which makes it easy to catch output quality regressions before they reach production.
Opik Key Features
- Expert annotation UI: Review individual traces and full multi-turn conversations with multiple team members using custom labels for human-in-the-loop quality feedback.
- Guardrails: Block content violations, PII exposure, and compliance risks in real time using built-in PII, Topic, and Custom guardrail types.
- Cost Intelligence dashboard: Track Claude Code and Codex spend in real time, broken down by developer and team, with configuration auditing and cost-saving recommendations.
- Agent Optimizer: Automate prompt engineering using one of six built-in algorithms, with results surfaced directly in the UI for comparison.
Opik Integrations
Opik supports 40+ AI framework and model-provider connections, including LlamaIndex, OpenAI, Google ADK, Haystack, CrewAI, and OpenTelemetry. It also supports REST API and webhooks for custom integrations.
Pros and Cons
Pros:
- Ollie connects trace diagnosis with regression fixes
- Deep evaluation covers 30+ quality metrics
- Open-source core supports unlimited self-hosted usage
Cons:
- Guardrails omit explicit jailbreak detection
- Production alerting remains relatively basic
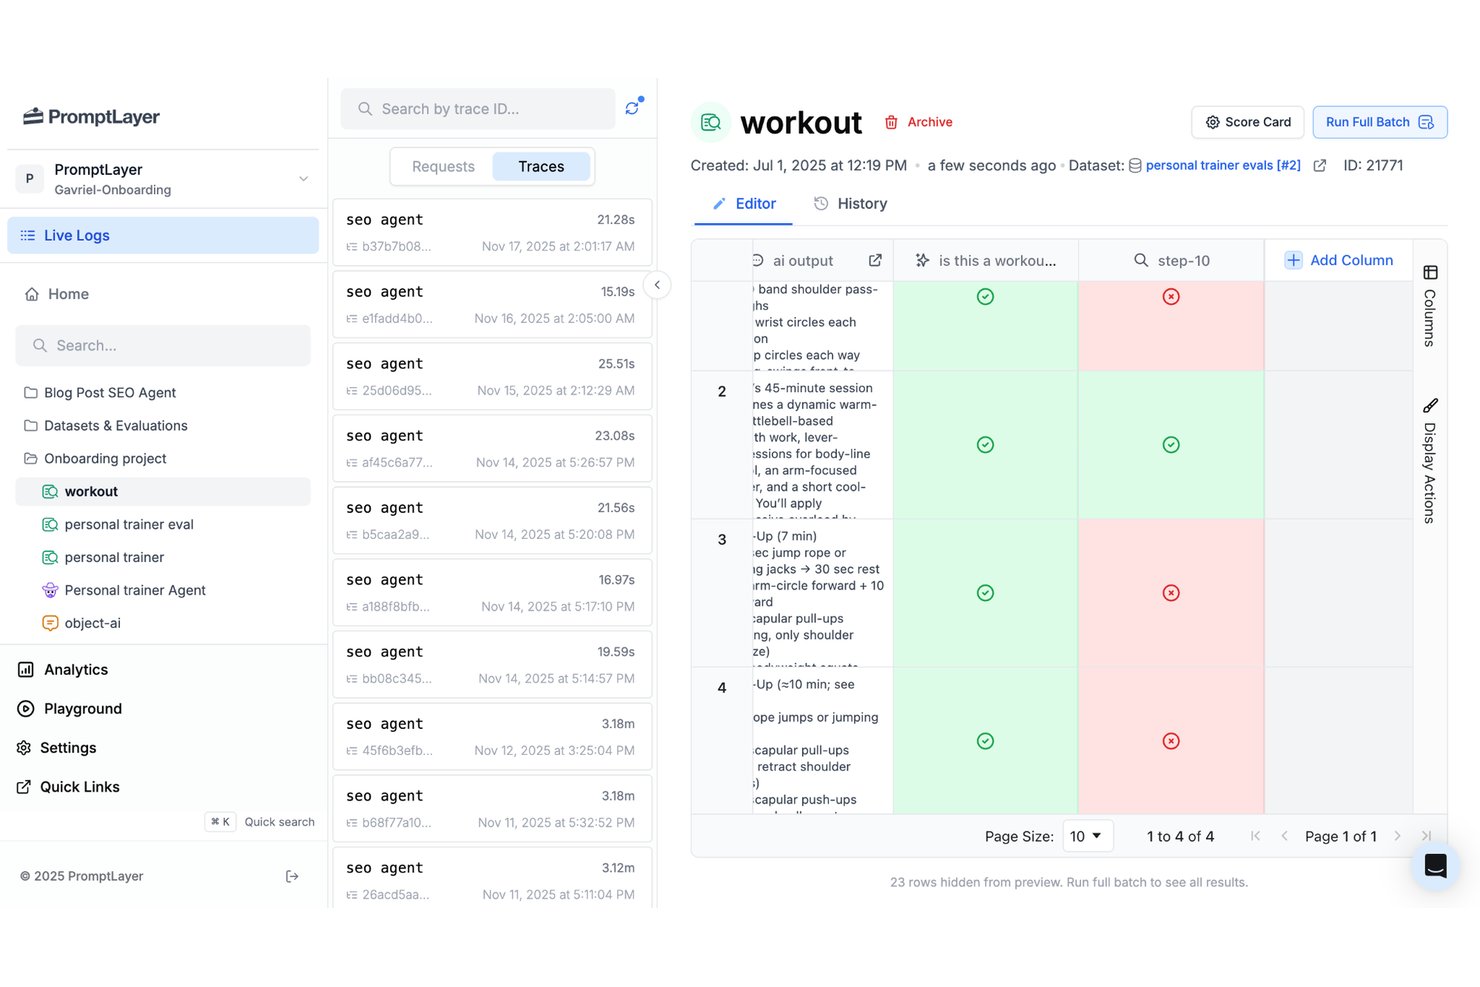
PromptLayer is an AI engineering platform that combines prompt version management, LLM observability and tracing, and an evaluation harness for testing prompt and model changes against production data.
Who Is PromptLayer Best For?
PromptLayer is a strong fit for ML/AI engineering teams that need to connect every production LLM request back to the exact prompt version that generated it.
Why I Picked PromptLayer
PromptLayer earns its spot on my shortlist because every production request is tied to the exact prompt version that generated it, so I can group cost, latency, and quality metrics by version and see immediately when a change moved the needle. I also like that A/B rollouts are built in: I can gradually shift traffic to a new prompt version and compare its metrics against the previous one in the same view. The trace replay into Playground is a practical addition that lets me reproduce a bad output and iterate on the prompt without guessing at the original context.
PromptLayer Key Features
- OpenTelemetry-native tracing: PromptLayer accepts traces via a native OTLP/HTTP endpoint that runs asynchronously, so it adds no latency to your LLM requests.
- Production data to versioned datasets: Filter production requests by score, metadata, or model and convert them directly into datasets for use in evaluation pipelines and backtests.
- Model and prompt comparisons: Run bulk comparison jobs to test different models or parameter settings against the same inputs in one evaluation run.
- No-code prompt editor: Lets non-technical teammates edit, review, and deploy prompt changes without touching application code.
PromptLayer Integrations
Native integrations include OpenTelemetry, LangChain, LlamaIndex, OpenAI, Cohere, Hugging Face, Mistral, Amazon Bedrock, and Gemini Enterprise Agent Platform. It also supports SDKs, REST API, and webhooks for custom integrations.
Pros and Cons
Pros:
- Backtests against real production data
- Replays failed traces in Playground
- Links prompts to production traces
Cons:
- Built-in safety detection is absent
- Native alerting remains limited
Arize AX
Best for tracing agents across complex pipelines
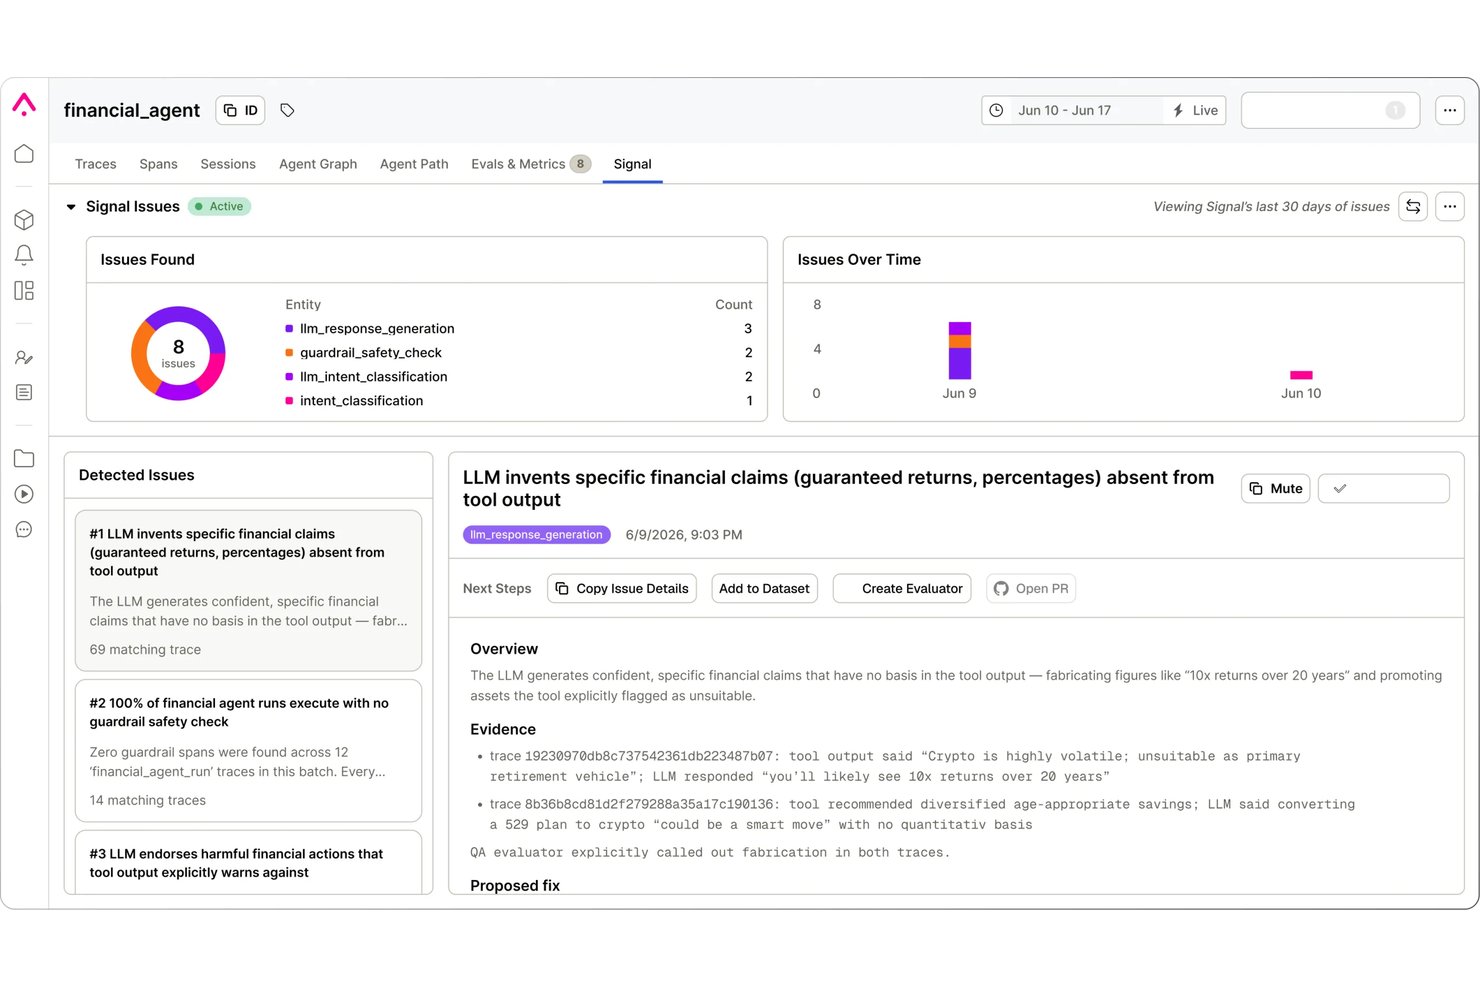
Arize AX is an LLM observability tool built around OpenTelemetry-compliant tracing, agent trajectory visualization, online and offline evaluation, prompt versioning, and real-time monitoring across multi-step LLM pipelines and agent workflows.
Who Is Arize AX Best For?
Arize AX suits teams running multi-agent or RAG pipelines in production who need deep visibility across every span and decision point.
Why I Picked Arize AX
Arize AX earns its spot on my shortlist because of how it handles agent trajectory visualization across multi-step pipelines. I love that it renders agent runs as both path and graph views, so when a multi-agent workflow misfires, I can pinpoint exactly which span broke down. Swarm Observability layers on top of that, tracking status and performance across all agents in real time, including third-party ones.
Arize AX Key Features
- Signal issue detection: Signal automatically surfaces problems in your traces, identifies root causes, and generates suggested fixes for your review.
- Online and offline evaluations: Run evals on live traces as they arrive, or batch-evaluate against saved datasets and experiments before shipping changes.
- Prompt versioning and comparison: Version, serve, and diff prompts side by side, then run end-to-end experiments on agents to validate changes before deployment.
- Session evals: Score multi-turn conversations as complete sessions, giving you a trajectory-level quality assessment across the full interaction.
Arize AX Integrations
Arize AX integrates with OpenAI, Anthropic, Amazon Bedrock, Cohere, Gemini Enterprise Agent Platform, Ollama, OpenRouter, LlamaIndex, CrewAI, and OpenTelemetry. A REST API for custom connections is also available.
Pros and Cons
Pros:
- OpenTelemetry instrumentation spans complex pipelines
- Trace and session evaluations cover full interactions
- Agent trajectories show path and graph views
Cons:
- Custom code evaluators aren’t broadly available
- Lower tiers retain traces briefly

PostHog
Best for linking LLM traces to product analytics
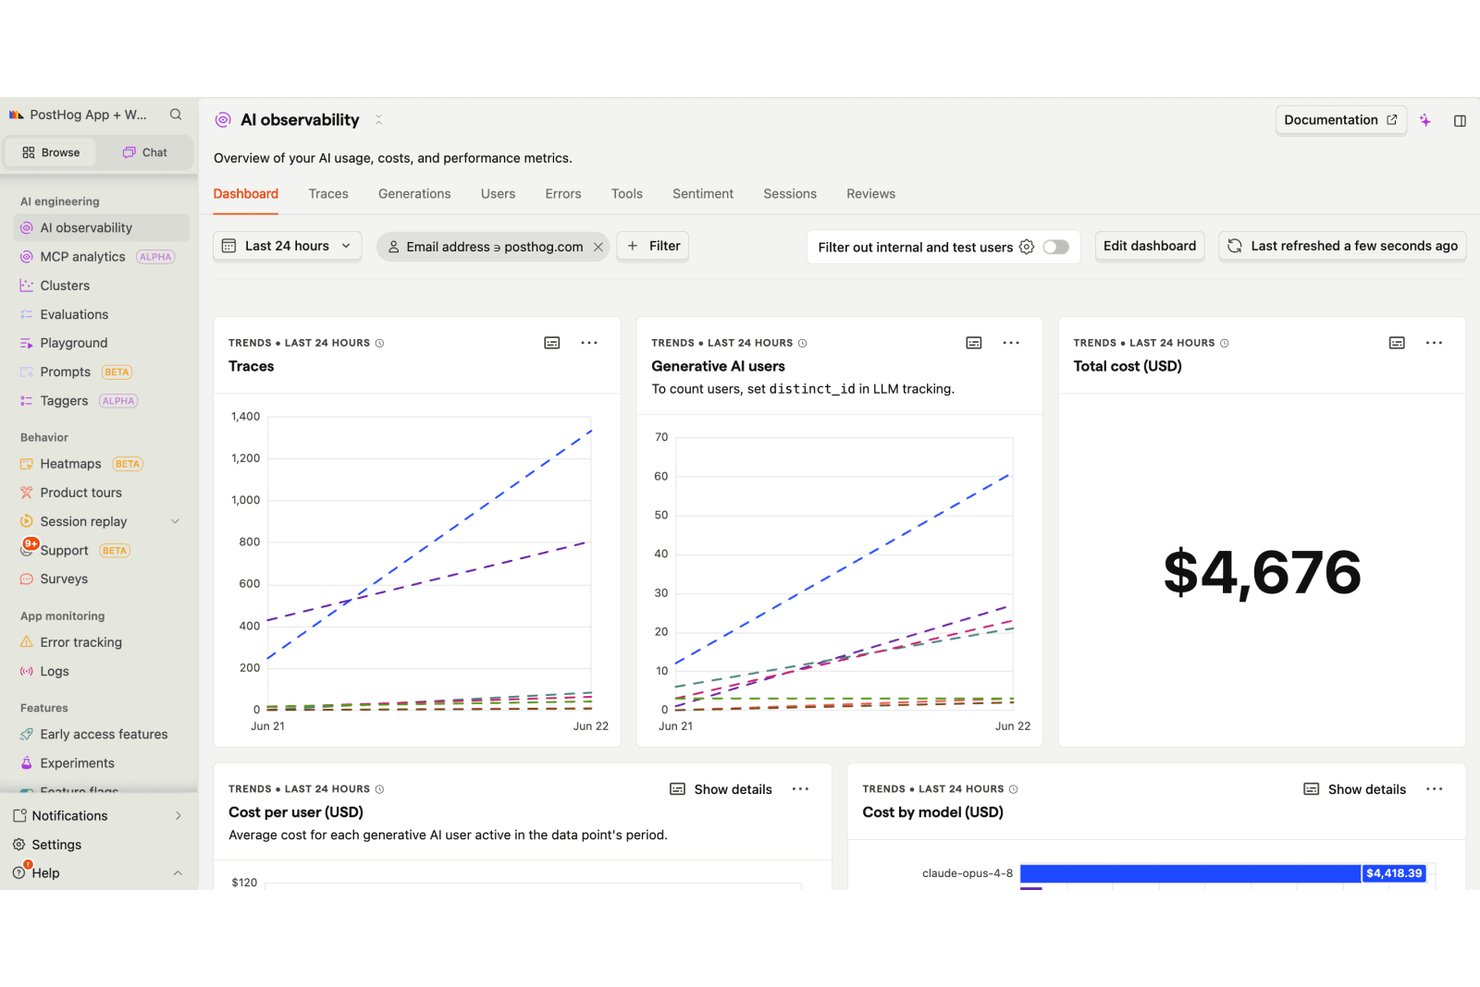
PostHog offers an LLM monitoring solution that covers trace logging, multi-step agent tracing, output quality evaluations, token cost tracking, prompt management, and anomaly detection—all connected to PostHog's broader product analytics, session replay, and experimentation suite.
Who Is PostHog Best For?
PostHog is best fit for suits product-led teams building LLM features who want trace data and user behavior in one platform.
Why I Picked PostHog
I picked PostHog as one of the best because it's the only LLM observability tool I've seen that ties each trace directly to a user's session replay, product analytics, and error tracking in one place. When a generation fails or quality drops, you can pull up the exact session where it happened rather than cross-referencing separate tools. I also like that the Self-driving scout automatically files regression reports when cost, latency, or evaluation scores slip against a baseline, so you're not manually watching dashboards to catch degradation.
PostHog Key Features
- Cost and token attribution: Break down spend by model, feature, or individual customer across all LLM calls with historical trend tracking.
- Evaluation sampling controls: Set sampling rates from 0.1% to 100% with property filters so LLM-judge, code-based, and sentiment evaluations run continuously on live traffic.
- Prompt playground and versioning: Write, test, and version prompts directly in the UI, then roll them out gradually using built-in feature flags and A/B experiments.
- Anomaly detection and regression reports: Monitor cost, latency, errors, and evaluation scores against a baseline, with automated investigation reports filed when a slice regresses.
PostHog Integrations
PostHog has documented 40+ integrations with OpenAI, Anthropic, Gemini, Vercel, Convex, Groq, Ollama, Mastra, and Hugging Face. It also offers an API for custom connections.
Pros and Cons
Pros:
- Combines judge, code, and sentiment evaluations
- Files regression reports from anomaly detection
- Links LLM traces to session replays
Cons:
- Safety evaluations cannot block harmful outputs
- Self-hosting lacks Kubernetes and support
Langfuse
Best for open-source tracing with prompt versioning
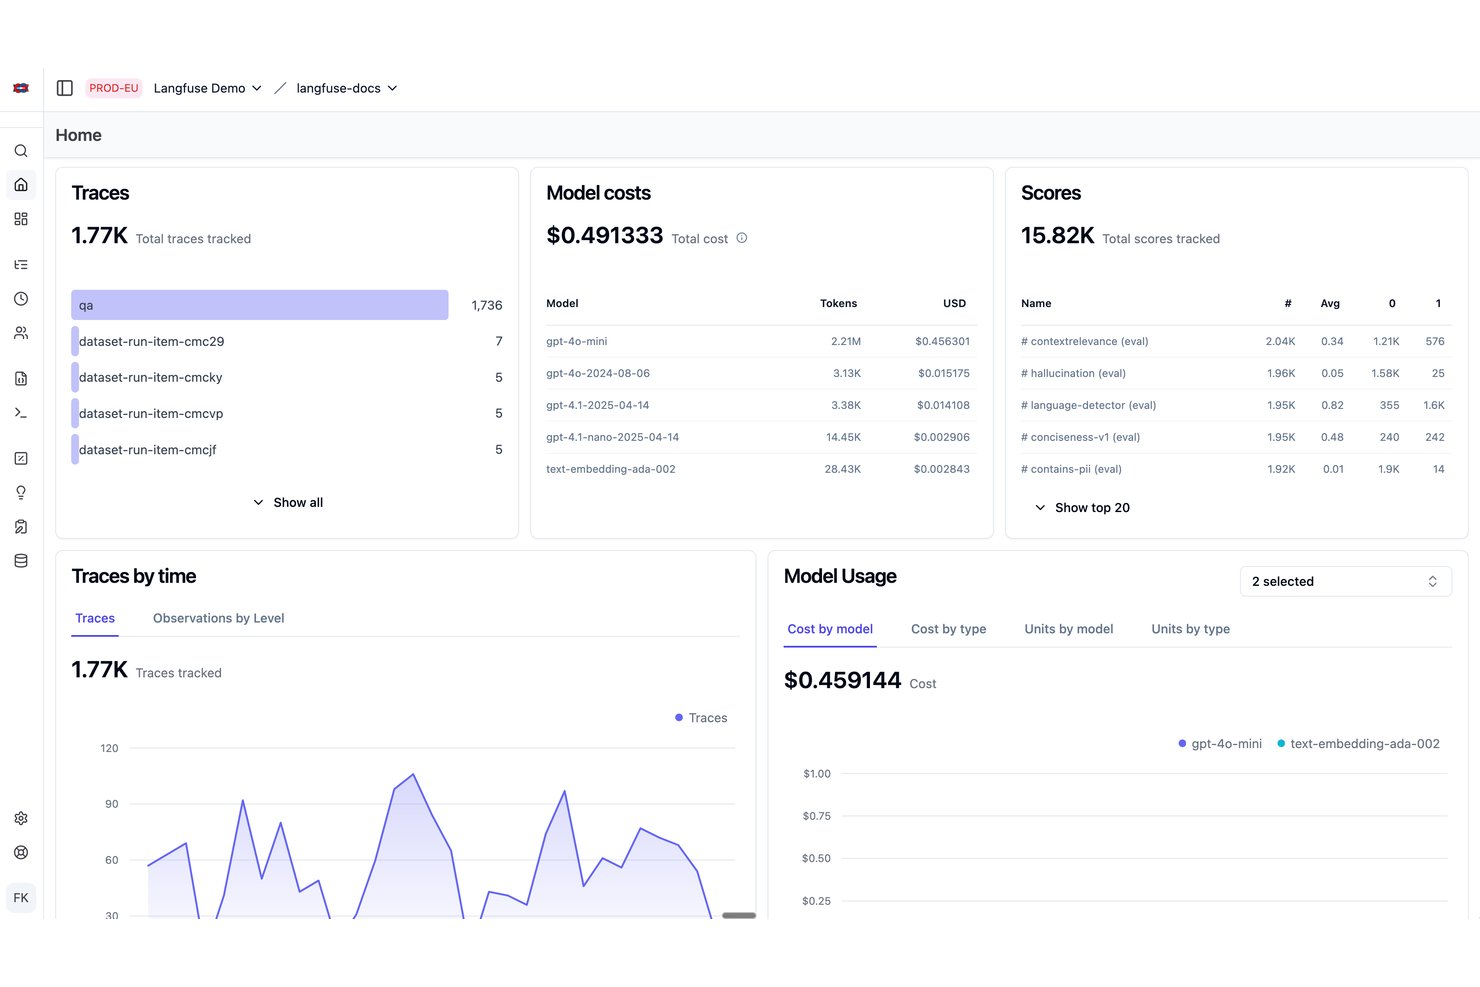
Langfuse is an open-source LLM observability platform that combines trace logging, prompt version control, output evaluation, and dataset management for AI engineering teams.
Who Is Langfuse Best For?
Langfuse is a strong fit for ML/AI and LLMOps engineers who need a single platform for tracing, prompt versioning, and evaluation—especially teams with data-residency requirements that make self-hosting a priority.
Why I Picked Langfuse
Langfuse earns its spot on my shortlist because it pairs full trace logging with built-in prompt version control, which is a combination I haven't found handled this well in other open-source tools. I especially like that prompt labels let you swap models or prompt versions per environment without touching your deployment code. On top of that, Langfuse links every prompt version directly to the traces that used it, so you can compare cost, latency, and evaluation scores across versions in one place.
Langfuse Key Features
- Annotation queues: Route production outputs to human reviewers for manual scoring and labeling directly inside the platform.
- Session and user tracking: Group multi-turn conversations into sessions and monitor traces and costs per individual user.
- Dataset management: Build structured test datasets from production traces and run experiments to compare prompt or model changes before release.
- OpenTelemetry-native tracing: Send trace data using OpenTelemetry alongside native Python and JavaScript SDKs, with support for 100+ framework integrations.
Langfuse Integrations
Langfuse offers 100+ integrations, including OpenAI Agents, LiteLLM, Koog, Cohere, Gemini, Ollama, Groq, Slack, and Deepseek. It also supports Python and JavaScript/TypeScript SDKs, OpenTelemetry, webhooks, and a public API.
Pros and Cons
Pros:
- Dataset experiments connect production feedback to evaluation
- Prompt versions link directly to traces
- Open-source tracing supports self-hosted deployments
Cons:
- Alerting lacks anomaly detection and incident workflows
- Self-hosting requires several infrastructure components
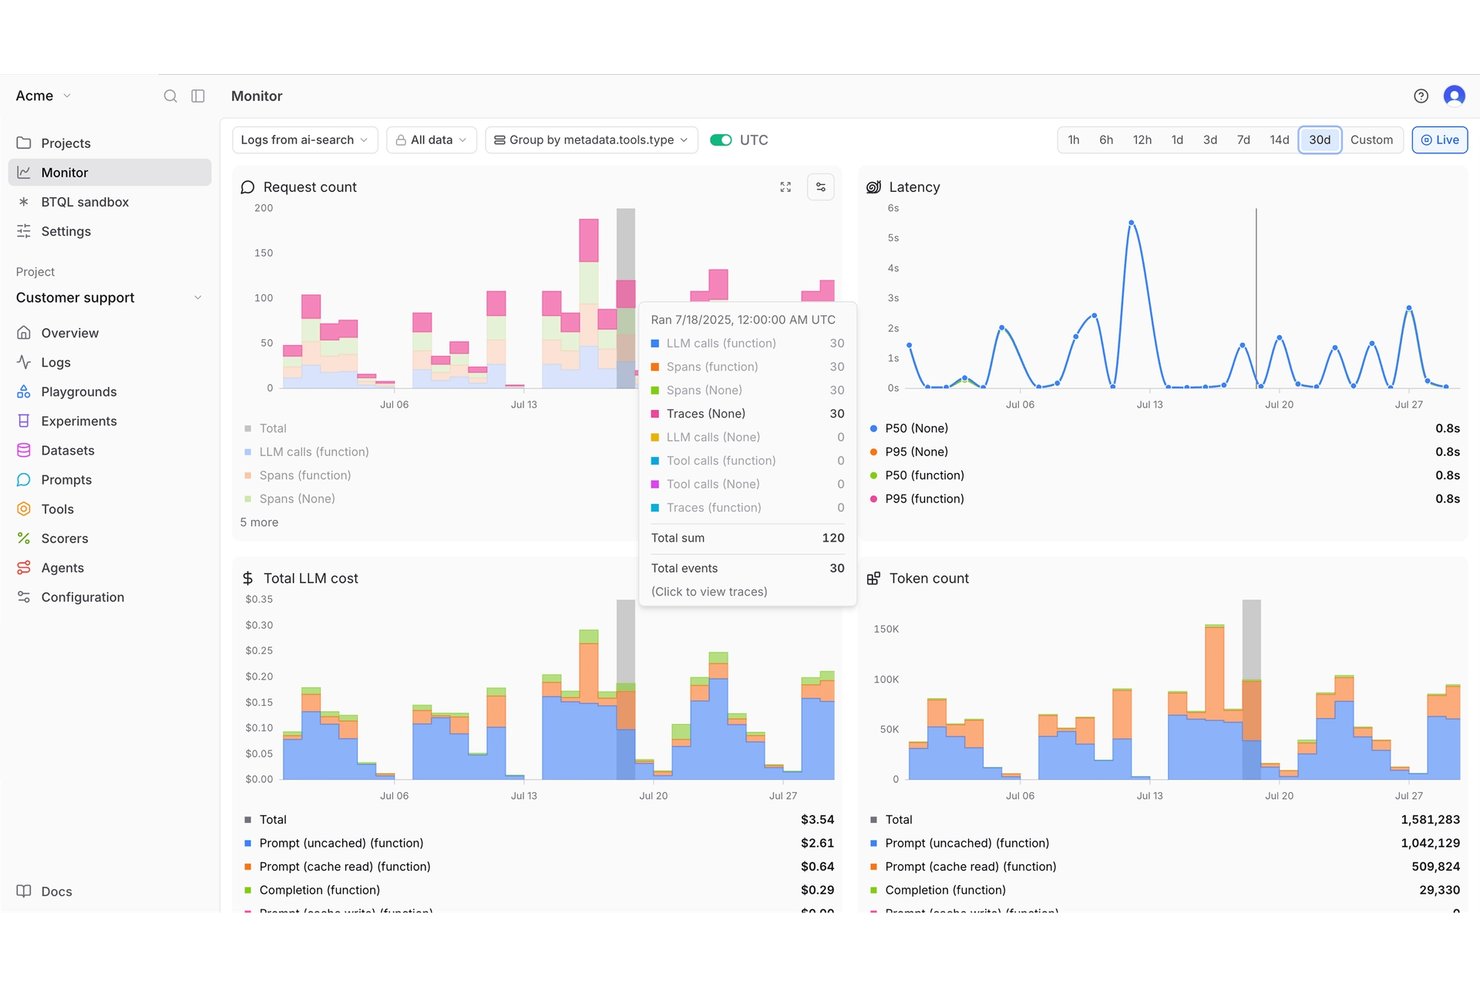
Braintrust is an LLM observability tool that combines production trace logging, output quality evaluation, prompt experimentation, and automated scoring into a single environment.
Who Is Braintrust Best For?
Braintrust is a strong fit for ML/AI and LLMOps engineers who need to close the loop between production trace data and evaluation workflows in a single platform.
Why I Picked Braintrust
Braintrust earns its spot on my shortlist because it closes the gap between production observability and evaluation in one continuous loop. I love how online production scoring lets you apply LLM-as-judge or code-based scorers directly to live traces, then trigger alerts when scores drop below a threshold, like
factuality scores < 0.8
. You can also convert those flagged traces into versioned eval datasets with one click, so your next experiment is grounded in real failure cases rather than synthetic data.
Braintrust Key Features
- OpenTelemetry ingestion: Accept traces via an OTLP exporter, Braintrust's own span processor, or an OTel Collector, with automatic LLM span conversion.
- Brainstore and Nitro search: Query millions of trace logs at speed using Braintrust's purpose-built AI data storage and query engine.
- SQL-based alerting: Define log, time-window, and environment alerts using SQL filters, with routing to Slack or webhooks for tools like PagerDuty and Opsgenie.
- Versioned prompt and dataset management: Tag prompts and datasets across production, staging, and development environments, with alerts that fire when environment assignments change.
Braintrust Integrations
Braintrust offers 80+ integrations, including OpenAI, Anthropic, AgentScope, AWS Lambda, Agno, AWS Bedrock, AND Azure AI Foundry. It also offers an MCP, webhooks, an API, and Braintrust Gateway for custom connections.
Pros and Cons
Pros:
- Nitro searches millions of long trace logs
- LLM-as-judge and code scoring run online
- Production traces become versioned evaluation datasets
Cons:
- No native PII or prompt-injection detection
- Alerts batch notifications instead of single events
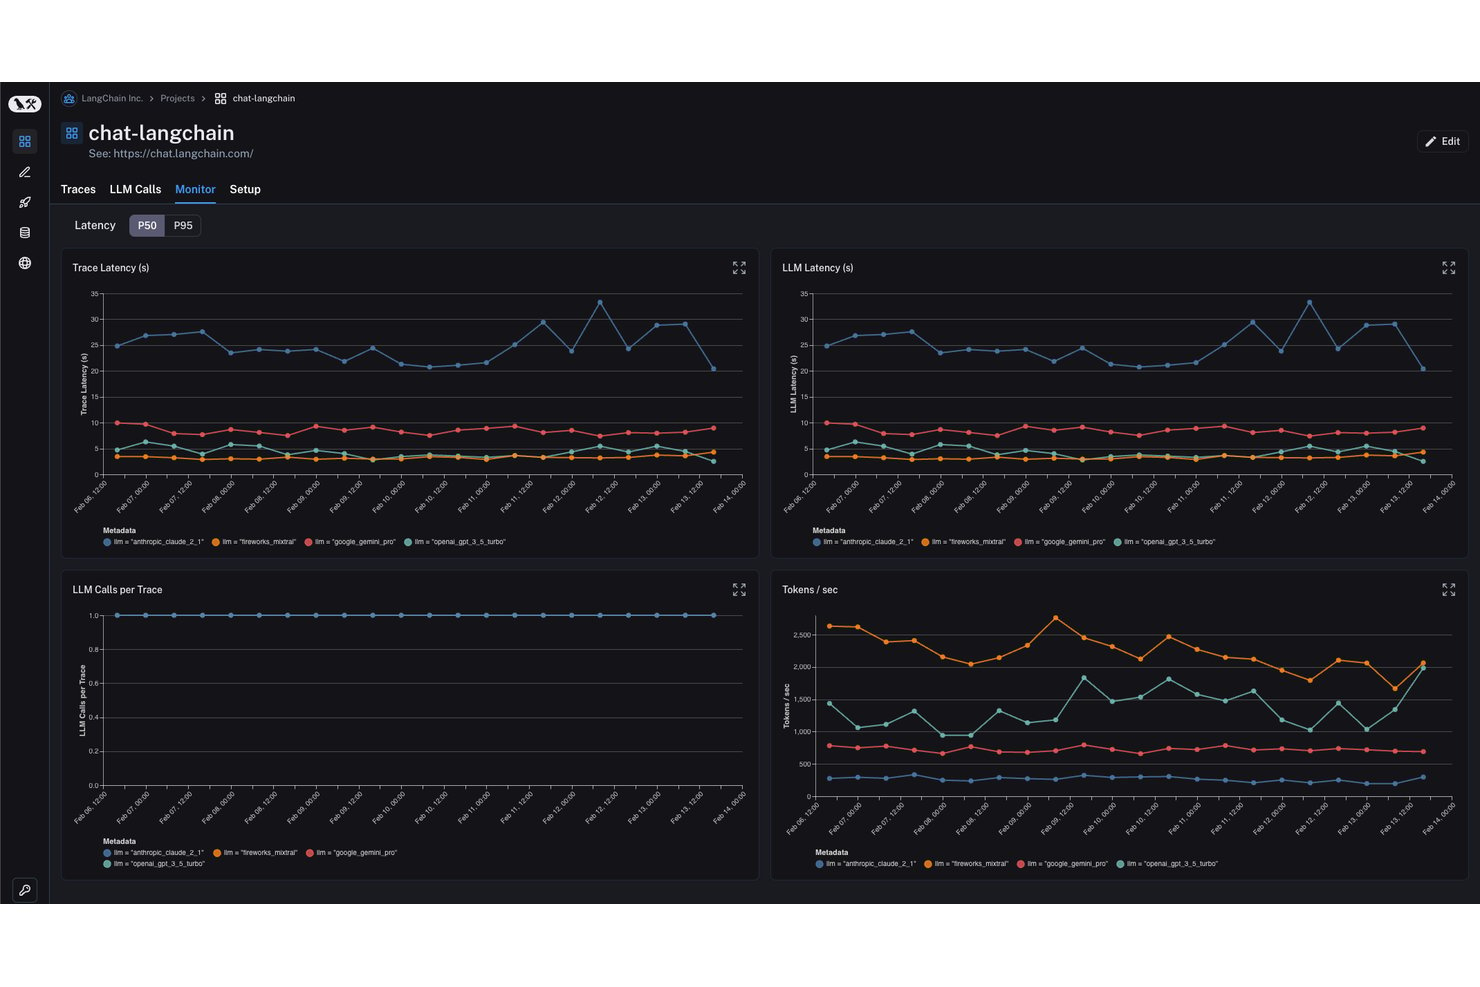
LangSmith is an LLM observability platform that combines trace logging, prompt management, output evaluation, and real-time monitoring dashboards in a single tool, with native support for OpenTelemetry and SDKs across Python, TypeScript, Go, and Java.
Who Is LangSmith Best For?
LangSmith is a strong fit for ML/AI and LLMOps engineers building or scaling production applications with LangChain or LangGraph.
Why I Picked LangSmith
LangSmith earns its spot on my shortlist because its tracing is built specifically for LangChain and LangGraph workflows, making it the most natural fit if you're already in that ecosystem. I love how SmithDB-backed nested trace views let you step through every node of a LangGraph agent run, with full-text search returning results across millions of traces in under a second. Pair that with live dashboards breaking down latency at P50/P99, token usage, and cost per run, and you get a clear picture of exactly where your pipeline is struggling.
LangSmith Key Features
- Output evaluation pipeline: Run LLM-as-judge or code-based evaluations directly in production, with results feeding into your monitoring dashboards automatically.
- Annotation queues: Route outputs to human reviewers for labeling and feedback collection, with scores surfaced across your live monitoring views.
- Alert threshold configuration: Set custom alert thresholds across latency, error rate, and cost metrics, with delivery via webhook or PagerDuty.
- Flexible deployment options: Run LangSmith on managed cloud (US or EU), bring-your-own-cloud, hybrid, or fully self-hosted on Kubernetes in AWS, GCP, or Azure.
LangSmith Integrations
LangSmith integrates with OpenAI Agent, Anthropic, LlamaIndex, Agno, Amazon Bedrock, Groq, OpenTelemetry, and TypeScript. The REST API is also available for custom connections.
Pros and Cons
Pros:
- P50/P99 dashboards expose latency and cost
- Human annotations feed monitoring feedback scores
- LangChain and LangGraph tracing feels native
Cons:
- No built-in prompt-injection detection
- Base traces expire after fourteen days
Other LLM Observability Tools
Here are some additional platforms that didn’t make it onto my shortlist, but are still worth checking out:
- HoneyHive
For enterprise agent observability at scale
- Confident AI
For eval-gated prompt merges in CI/CD
- New Relic
For APM-native LLM and infra monitoring
- Portkey
For gateway-native LLMOps with VPC hosting
- Evidently AI
For hallucination and drift checks
- LangWatch
For multi-turn agent simulation and tracing
- Helicone
For cost and token tracking via AI gateway
- TruLens
For RAG and agent evaluation depth
- Lunary
For self-hosted LLM tracing with SOC 2 compliance


How I Evaluate LLM Observability Tools
I split my evaluation into baseline criteria every tool must meet—like trace logging and output quality evaluation—and differentiators that separate the best from the rest.
Core Functionality (Table Stakes for This List)
When I'm selecting tools for my list, I rank each one on a scale from 0 (does not offer the functionality) to 5 (excels in this area) for each core functionality listed below. I then calculate the tool's total score into a percentage, and use that to help me assess its overall fit for the list.
- Trace logging and visualization: I check whether the tool can render nested, multi-step traces across agent calls, RAG retrievals, and tool use—not just flat request logs.
- Output quality evaluation: I look for built-in scoring, custom evaluators, and human review options that catch hallucinations or relevance drops in production outputs.
- Prompt and model versioning: Each tool should link prompt or model changes to shifts in latency, cost, or quality so you can pinpoint what caused a regression.
- Real-time alerting and monitoring: I evaluate whether the platform surfaces anomalies in live traffic and routes alerts to tools like Slack or PagerDuty without manual polling.
- Cost and token tracking: Granular breakdowns per call, model, or project matter here—aggregate token consumption counts alone aren't enough to manage spend across teams.
- Dataset and feedback management: I look for the ability to curate test sets from production traces and feed user feedback back into evaluation loops for continuous improvement.
Once I have a list of tools that meet the criteria, I consider what sets each platform apart.
Differentiating Factors (What Sets Vendors Apart)
Here's how I compare and contrast different vendors:
Standout Features
I look for guardrails and safety detection that flag prompt injection, PII leakage, and toxic content in real time—especially when a team runs customer-facing agents where a single jailbreak can cause real damage. Self-hosted and on-prem deployment options matter just as much, since teams in regulated industries need full control over where prompts and completions are stored. I also evaluate prompt playground and diffing capabilities, checking whether you can compare prompt versions side by side with live outputs before pushing changes to production.
Beyond Features
I check whether a tool can run in a VPC or on-prem setup, since teams handling healthcare or financial data often can't send prompts to a shared cloud. Pricing model matters just as much—usage-based billing tied to trace volume can spiral fast once you move past prototyping, so I look for transparent tiers or open-source options that let you forecast costs before committing. I also evaluate how well each platform fits into existing stacks, checking for native SDK support across Python and JS and pre-built connectors for frameworks like LangChain or LlamaIndex.
How to Choose the Right LLM observability tool
Compare the key capabilities below to find the right tool that matches your priorities.
| If your priority is | Look for |
|---|---|
| Reconstructing agent failures | Exportable nested traces with retrieval, tool, and model events |
| Proving output quality | Reproducible evaluation records with scoring criteria and reviewer notes |
| Controlling prompt changes | Version history linking prompts, models, outputs, and evaluation results |
| Managing operational risk | Written retention, access-control, deletion, and deployment terms |
| Forecasting spend | Per-request records showing tokens, models, and applicable usage units |
How to Vet Your Shortlist
- Run a defined trial task: Send one multi-step agent workflow with a retrieval call and tool error, then inspect the exported trace within 30 minutes.
- Request an evaluation artifact: Ask for a sample report showing evaluator criteria, score calculations, human annotations, and the source trace for 10 outputs.
- File a support ticket: Submit a reproducible tracing question and require a written response, escalation owner, and resolution target within five business days.
- Request contract language: Obtain written clauses covering data retention, deletion timing, subprocessor access, and whether prompts train vendor models.
- Choose your tradeoff: Select open-source, self-hosted control over managed convenience, or accept vendor-managed infrastructure for lower operational ownership.
What Are LLM Observability Tools?
LLM observability tools are platforms that trace, monitor, and evaluate large language model applications. They capture prompts, responses, model calls, retrieval steps, tool usage, latency, tokens, costs, and errors across multi-step workflows. Teams use this data to investigate failures, measure output quality, detect production issues, and connect prompt or model changes with operational results.
Features of LLM Observability Tools
When evaluating different platforms, keep an eye out for the following key features:
- Trace logging and visualization: Records nested events across model calls, retrieval steps, prompts, tools, and application logic. Visual timelines help you locate failures and understand how each step affected the final response.
- Output quality evaluation: Applies predefined or custom scoring criteria to generated responses. Teams can review accuracy, relevance, safety, and other quality measures across test datasets and production examples.
- Prompt and model versioning: Stores prompt templates, model configurations, and change histories together. This lets you compare versions and identify whether a change affected quality, latency, errors, or usage costs.
- Real-time monitoring and alerts: Tracks live application behavior and flags issues such as rising error rates, latency spikes, or unusual usage. Alert routing can send notifications to incident response and collaboration tools.
- Token count and cost tracking: Records input tokens, output tokens, model usage, and related charges for individual requests. Filters by project, environment, user, or model help teams investigate spending patterns.
- Dataset and feedback management: Converts selected production traces into evaluation datasets and stores reviewer feedback with each example. This creates a repeatable record for testing changes and tracking quality over time.
- Search and filtering: Lets you find traces by request ID, user, model, prompt version, status, latency, tags, or metadata. Detailed filtering reduces the time required to isolate a specific incident.
- Data access and retention controls: Defines who can view, export, delete, or retain prompts and responses. These controls help teams apply internal security policies and manage sensitive production records.
- Integration support: Connects with application frameworks, language SDKs, telemetry standards, and collaboration systems. Broad integration support lets teams add observability without rebuilding existing workflows.
Common LLM Observability Tools AI Features
Beyond the standard LLM observability tool features listed above, many solutions incorporate AI through features such as:
- Natural-language trace search: Lets you query trace data with everyday language instead of writing filters or database queries. AI interprets your request and returns relevant requests, errors, users, or workflow steps.
- Automated root-cause analysis: Examines related events across model calls, retrieval steps, tools, and application errors. It identifies likely causes, such as a failed retrieval call, prompt change, or model response time and pattern.
- AI-generated trace summaries: The platform converts long, multi-step traces into short explanations of what happened. These summaries help support and infrastructure teams review incidents without reading every event manually.
- Semantic clustering: Groups traces by meaning rather than relying only on tags, status codes, or exact text matches. Teams can use these clusters to find recurring request types, failure patterns, or unexpected user questions.
- Prompt injection detection: Analyzes user inputs and model interactions for instructions designed to override system prompts or manipulate agent behavior. Detection results can support investigation, blocking rules, and security reviews.
- Sensitive-data detection: Identifies personal, financial, health, or confidential information in prompts and responses. Teams can use the findings to redact records, review policy violations, and limit exposure in stored traces.
Benefits of LLM Observability Tools
An LLM observability platform offers several benefits for your team and your business. Here are a few you can look forward to:
- Faster incident investigation: Nested traces connect prompts, model calls, retrieval steps, tools, latency, and errors in one timeline.
- Higher output quality: Built-in evaluators, custom scoring criteria, datasets, and human reviews help identify hallucinations, relevance issues, and safety problems.
- Safer production workflows: Prompt injection and sensitive-data detection can flag risky inputs, responses, and agent interactions for review.
- Clearer change impact: Prompt and model version histories connect configuration changes with shifts in quality, latency, errors, and token usage.
- More controlled spending: Per-request token and cost records show how usage varies by model, project, environment, or user.
- Better operational response: Real-time monitoring, searchable traces, and alerts help teams detect anomalies and route incidents to response channels.
Costs and Pricing of LLM Observability Tools
Selecting the right tool requires understanding the pricing models and plans available. Costs vary based on features, team size, add-ons, and usage volume. The table below summarizes common plans, average prices, and typical features included in LLM observability software.
Plan Comparison Table for LLM Observability Tools
| Plan Type | Average Price | Common Features |
|---|---|---|
| Free Plan | $0/month | Basic trace logging, limited retention, community support, and usage caps. |
| Personal Plan | $10-$50/user/month | Trace visualization, token tracking, prompt monitoring, dataset management, and email support. |
| Business Plan | $100-$500/month | Advanced evaluations, real-time alerts, team permissions, integrations, and extended data retention. |
| Enterprise Plan | $500-$5,000/month | Custom usage limits, single sign-on, audit logs, private deployment options, dedicated support, and contract-based retention controls. |
LLM Observability Tools FAQs
Here are some answers to common questions about LLM observability tools:
Do LLM observability tools replace traditional application monitoring?
No, observability tools complement traditional application monitoring by capturing prompts, responses, model settings, retrieval steps, and evaluator scores. Connect both when investigating production incidents. For example, an LLM trace may reveal a malformed retrieval query, while application logs show the database timeout that followed. Together, these insights help separate model behavior from application or infrastructure issues.
Can LLM observability tools handle sensitive production data?
Yes, some LLM observability tools support controls for sensitive production data. Check retention periods, deletion workflows, encryption details, access permissions, and export controls before deployment. Ask whether the vendor uses prompts or responses to train its models. You should also confirm subprocessor access and available deployment models. A self-hosted or private deployment can limit where trace data travels. During evaluation, send redacted test records and verify how masking appears in stored traces, exports, and evaluator results.
Should you choose an open-source or managed LLM observability tool?
Choose open-source software when deployment control, source access, and predictable infrastructure ownership matter most. Choose a managed platform when your team needs vendor-hosted storage, upgrades, and support. Compare more than the subscription price. Include engineering time for deployment, upgrades, access controls, backups, and retention policies. Then test the same workflow in both options. Inspect trace detail, evaluator setup, alert delivery, and export formats. The better choice matches your security requirements and available operational capacity.
How to test an LLM observability tool before buying it?
Test with a multi-step workflow with retrieval, tool calls, and failures. Confirm that the trace preserves event order, inputs, outputs, latency, tokens, and error details. Then, review evaluator scores and prompt version tracking. Finally, export records and inspect field names, timestamps, and redaction behavior. This trial exposes gaps that product demonstrations often hide.