

Et godt alternativ til dbt gir teamet ditt pålitelig SQL-basert datatransformasjon, versjonskontroll og arbeidsflytautomatisering – uten å låse dere til én bestemt tilnærming eller ett bestemt økosystem. Hvis du ser etter alternativer til dbt Core eller dbt Cloud, vurderer du sannsynligvis fleksibilitet, integrasjonsmuligheter og om du foretrekker en kodeorientert arbeidsflyt med GitHub-basert versjonskontroll.
Med så mange plattformer i utvikling er det vanskelig å vite hvilke løsninger som kan håndtere behovene dine innen datamodellering, testing, orkestrering og samarbeidsbasert utvikling. Denne listen hjelper deg med å sammenligne de beste alternativene til dbt i 2026, slik at du trygt kan velge riktig verktøy for teamets utfordringer innen analyseutvikling.
Hva er dbt?
dbt er et verktøy for analyseutvikling som lar team transformere, teste og dokumentere data i datavarehuset ved hjelp av SQL. Det brukes vanligvis i ELT-arbeidsflyter, der rådata lastes inn i datavarehuset og transformeres etterpå. dbt muliggjør kodeorienterte arbeidsflyter med versjonskontroll, CI/CD-integrasjon, modulær datamodellering og automatisert testing, noe som gjør det enklere å administrere komplekse analysepipelines.
Selv om dbt ikke er et GUI-basert ETL-verktøy, bruker det YAML til konfigurasjon og fungerer sammen med ETL-verktøy i moderne datastakker. Det integreres også med skyplattformer som GCP og andre store datavarehus. dbt brukes i stor grad av dataingeniører og analytikere som ønsker å bygge pålitelige og vedlikeholdbare datatransformasjoner direkte i datavarehusmiljøet sitt.
Sammenligningstabell for alternativer til dbt
Denne sammenligningstabellen oppsummerer prisopplysningene for mine beste utvalgte alternativer til dbt:
Score legend (out of 5)
- Excellent4.5–5
- Good4–4.4
- Average3–3.9
- Below average2–2.9
- Poor1–1.9
Sorted by: Default
| Tool | Starting Price | Website | |||||||
|---|---|---|---|---|---|---|---|---|---|
Best for code-free advanced analytics | 3.0 out of 5 | 2 | 3 | 4 | 2 | 4 | 3 | $250/user/month 30-day free trial | Website |
Best for broad connector library support | Not rated | Not rated | 2 | 5 | 2 | 4 | 2 | Pricing upon request 30-day free trial available | Website |
Best for serverless ETL automation | 3.0 out of 5 | 2 | 3 | 4 | 2 | 4 | 3 | $0.29/DPU-hour Free plan available | Website |
Best for enterprise-grade workload scalability | Not rated | 2 | 2 | 4 | Not rated | 2 | 3 | Pricing upon request 30-day free trial + demo available | Website |
Best for low-code pipeline building | 2.8 out of 5 | 2 | 2 | 4 | 3 | 3 | 3 | Pricing upon request Free trial + demo available | Website |
Best for dynamic data validation rules | 2.7 out of 5 | 3 | 3 | 4 | 2 | 2 | 2 | Pricing upon request Free demo available | Website |
Best for collaborative notebook-based analytics | 3.7 out of 5 | 4 | 3 | 3 | 4 | 4 | 4 | Pricing upon request Two-week free trial + free demo available | Website |
Best for column-level data lineage visualization | 3.8 out of 5 | 4 | 4 | 4 | 4 | 3 | 4 | $150/user/month Free plan available | Website |
Best for version-controlled SQL workflows | 3.7 out of 5 | 4 | 3 | 5 | 4 | 2 | 4 | Pricing upon request Free plan available | Website |
Best for managed development environments | 3.7 out of 5 | 3 | 3 | 4 | 4 | 4 | 4 | Pricing upon request 14-day free trial + free demo available | Website |


Hvorfor du kan stole på våre programvareanbefalinger
6,700+
Reviews
20
Industry experts
16+
Evaluation factors
14
Years
Teamet vårt har testet og anmeldt programvare siden 2012. Vi er selv teknologiledere, så vi vet hvor vanskelig og hvor viktig det er å velge riktig programvare.
I denne guiden har vi vurdert verktøyene gjennom praktisk testing og uavhengig research og gitt dem poeng ut fra våre utvelgelseskriterier.
Anmeldelsene våre bygger på vår egen redaksjonelle vurdering. De er ikke et salgsargument.
Ekspertanmeldere:
- Paulo Gardini MiguelTech Director
 Tim FisherVP of AI
 Gabriel RosasTech Lead & Software Architect
 Christhian GruhnTech Lead & Platform Architect

Anmeldelser av alternativer til dbt
Nedenfor finner du mine detaljerte oppsummeringer av alternativene til dbt som kom med på kortlisten. Anmeldelsene mine gir et detaljert innblikk i funksjonene, de beste bruksområdene og integrasjonene til hver plattform, slik at du kan finne den beste løsningen for dine behov innen analyseutvikling.
 Best for code-free advanced analytics
- 30-day free trial
- From $250/user/month (billed annually)
Visit WebsiteCustomer Rating:4.6/5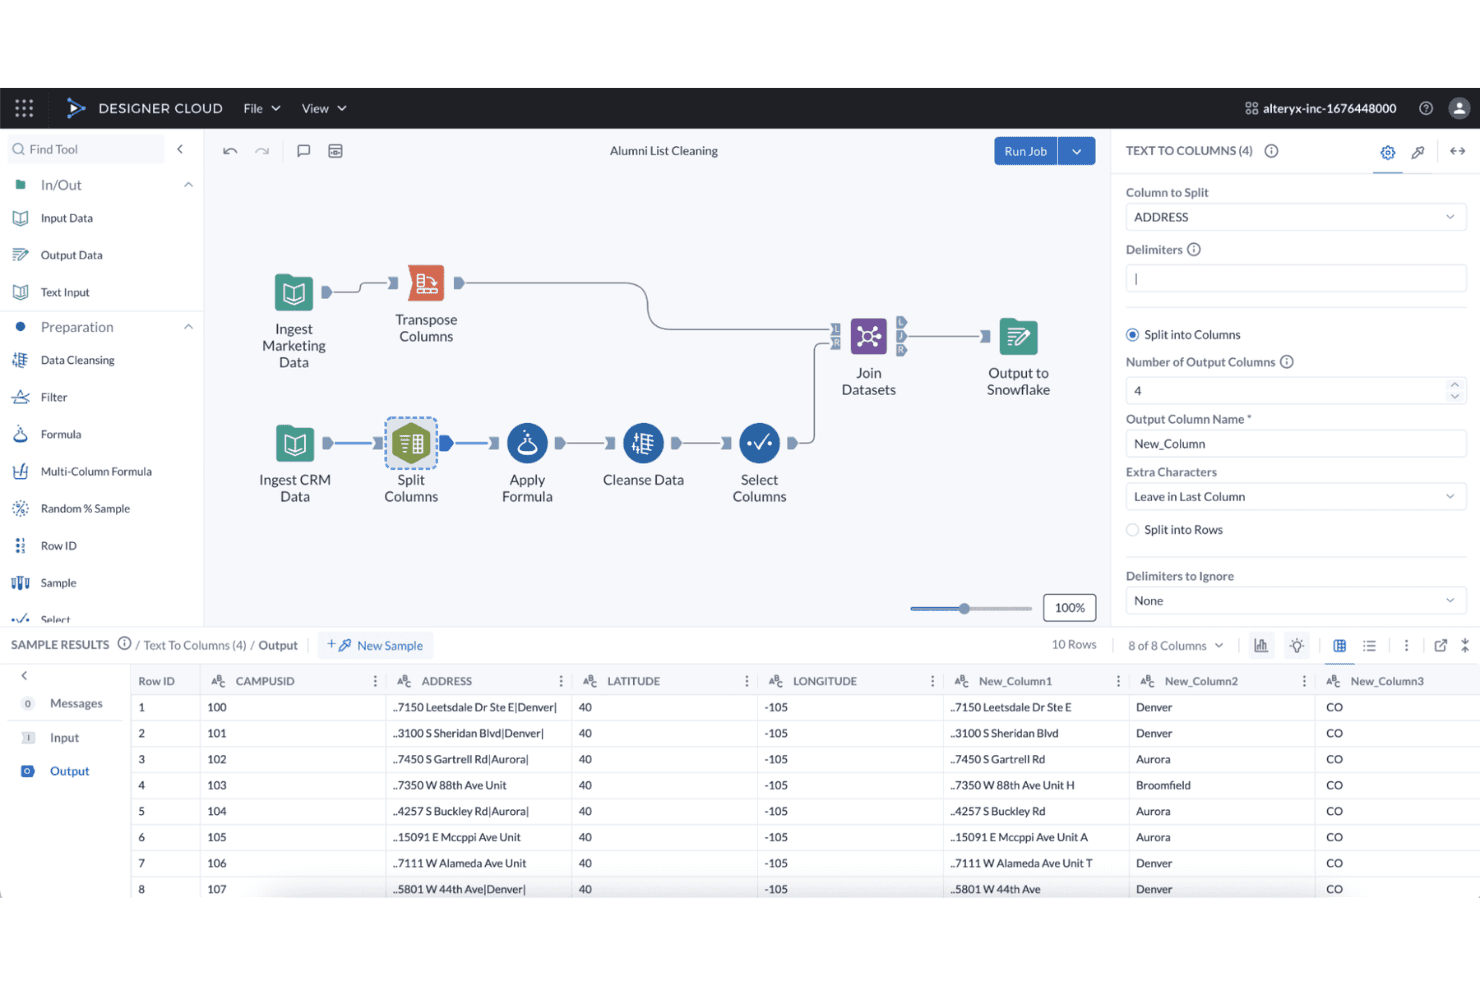
Alteryx Designer Cloud workflow splitting address fields into separate columns during alumni data cleaning. Alteryx is a low-code analytics platform that lets data and analytics teams clean, blend, and automate data workflows without writing SQL, making it a practical option for organizations that want to transform and orchestrate data pipelines across 100+ sources without a code-first toolchain.
Who Is Alteryx Best For?
Alteryx is a strong fit for analytics teams and BI managers who need to blend, clean, and automate data workflows across many sources without writing SQL.
Why I Picked Alteryx
I picked Alteryx as one of the best because it lets analytics teams replace manual SQL pipelines with drag-and-drop workflows that clean, blend, and join data across 100+ sources, no code required. I particularly like how the visual workflow canvas makes it easy to inspect data at each transformation step, which speeds up debugging in ways a raw SQL script never does. Scheduling and API-triggered automation in the Enterprise tier mean I can run those workflows hands-free on a cadence.
Alteryx Key Features
- Schema validation: Checks source schemas at the start of job execution and can halt a workflow when the current schema differs from the stored version.
- OpenLineage event emission: Sends workflow-run lineage events, including column-level relationship metadata, to external catalog tools like Collibra and Atlan.
- Python tool with scikit-learn and pandas: Provides an embedded Python environment with a curated package set for scripting predictive logic directly inside a workflow.
- Role-based access controls: Lets administrators create custom roles with granular app-level permissions for individual users or user groups across workspaces.
Alteryx Integrations
Alteryx offers 100+ native integrations, including Snowflake, Google BigQuery, Databricks, Amazon Redshift, Microsoft Azure Synapse Analytics, Tableau, and Qlik Cloud. It also provides an API for custom integrations.
Pros and Cons
Pros:
- Conditional plans coordinate dependent workflows
- Automates recurring preparation and reporting
- Inspectable visual workflows aid debugging
Cons:
- Git workflows rely on external tooling
- No reusable dbt-style SQL modeling framework
Learn more about Alteryx: Best for broad connector library support
- 30-day free trial available
- Pricing upon request
Visit WebsiteCustomer Rating:4.3/5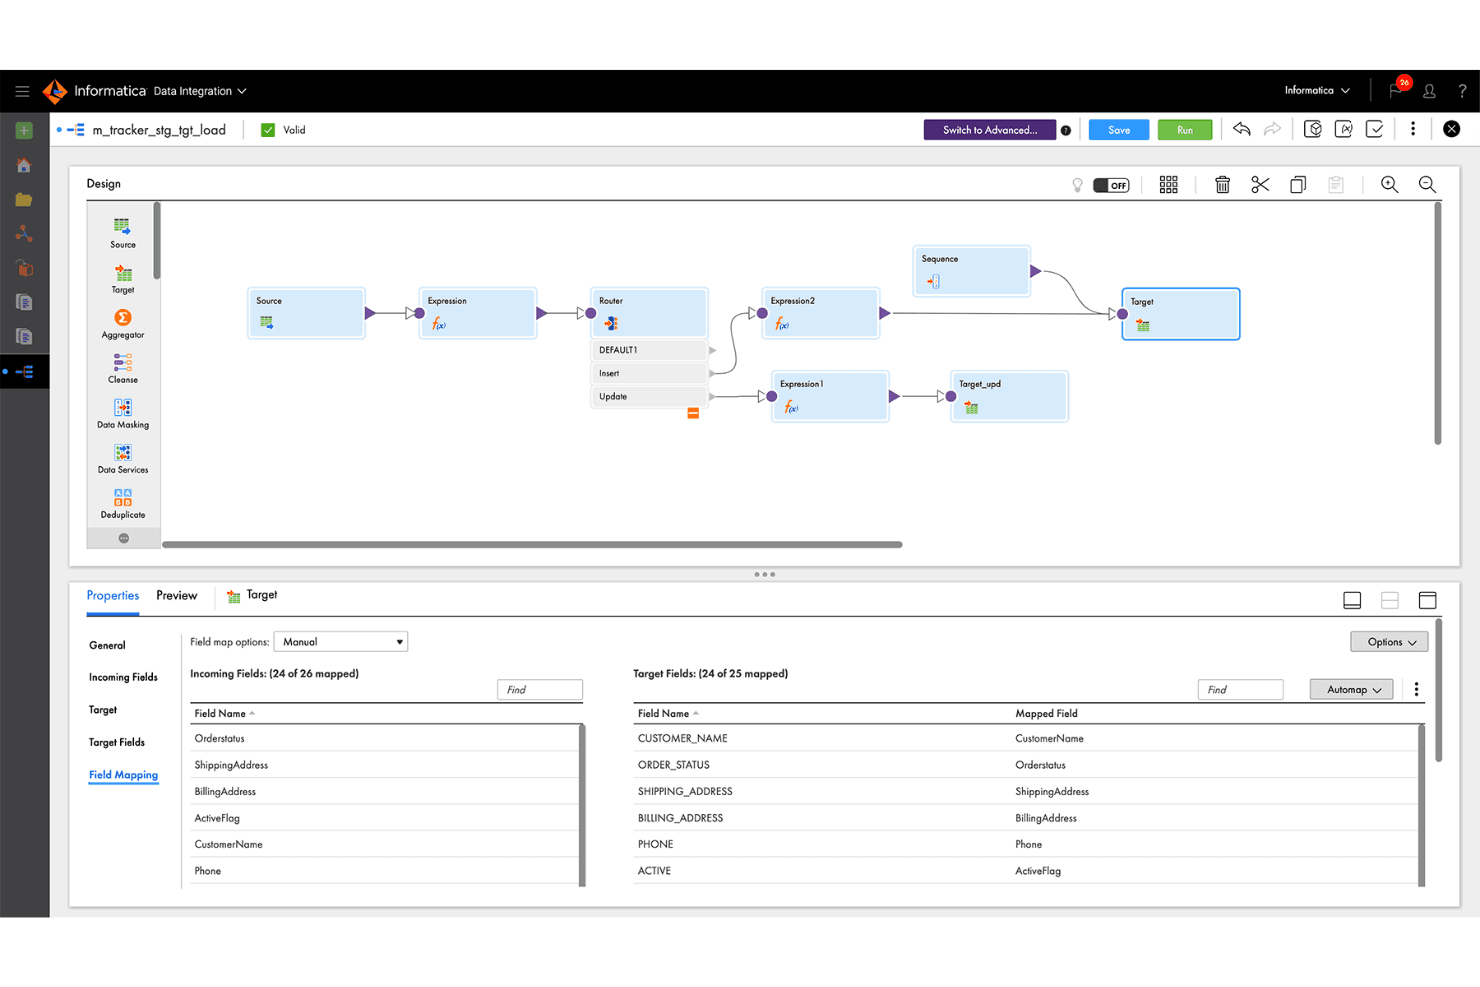
Informatica Data Integration mapping canvas showing source, router, expression and target transformations in a data load workflow. Informatica Data Integration is a cloud-based data pipeline platform built for data engineers who need to connect, move, and automate data across a wide range of sources and targets without writing every integration from scratch.
Who Is Informatica Best For?
Informatica Data Integration is a strong fit for data engineering teams that need to connect a large number of diverse sources and targets without building custom connectors from scratch.
Why I Picked Informatica
I picked Informatica as one of the best dbt alternatives because its connector library is genuinely in a league of its own. With hundreds of no-code connectors spanning cloud warehouses, on-premises databases, and ERP platforms, I can point it at nearly any source-target combination without writing custom integration code. Its ETL, ELT, CDC, and replication patterns mean my team can land data into Snowflake, Databricks, or a data lakehouse using whichever movement pattern fits the pipeline, and CLAIRE Copilot handles pipeline generation and runtime-log troubleshooting to cut down on manual debugging.
Informatica Key Features
- Data Validation: Compares replicated target tables against source tables to check data accuracy and completeness after ingestion.
- Python Transformation: Lets you write and execute Python scripts within CDI-Elastic mappings for statistical, ML, and NLP tasks.
- Taskflow orchestration: Supports simple and complex taskflow design with scheduling and REST invocation of workload executions.
- Git-based source control: Connects IDMC projects and assets to a Git repository so your team can track and manage pipeline changes over time.
Informatica Integrations
Informatica documents hundreds of no-code connectors, though availability varies by service, edition, and connector tier. A REST API supports custom integrations.
Pros and Cons
Pros:
- Mappings support data cleansing and validation
- AI-assisted logs help diagnose failures
- Scheduled workflows reduce manual pipeline work
Cons:
- Git workflow lacks merging and branching
- Complex SQL transformations can fail
Learn more about Informatica:
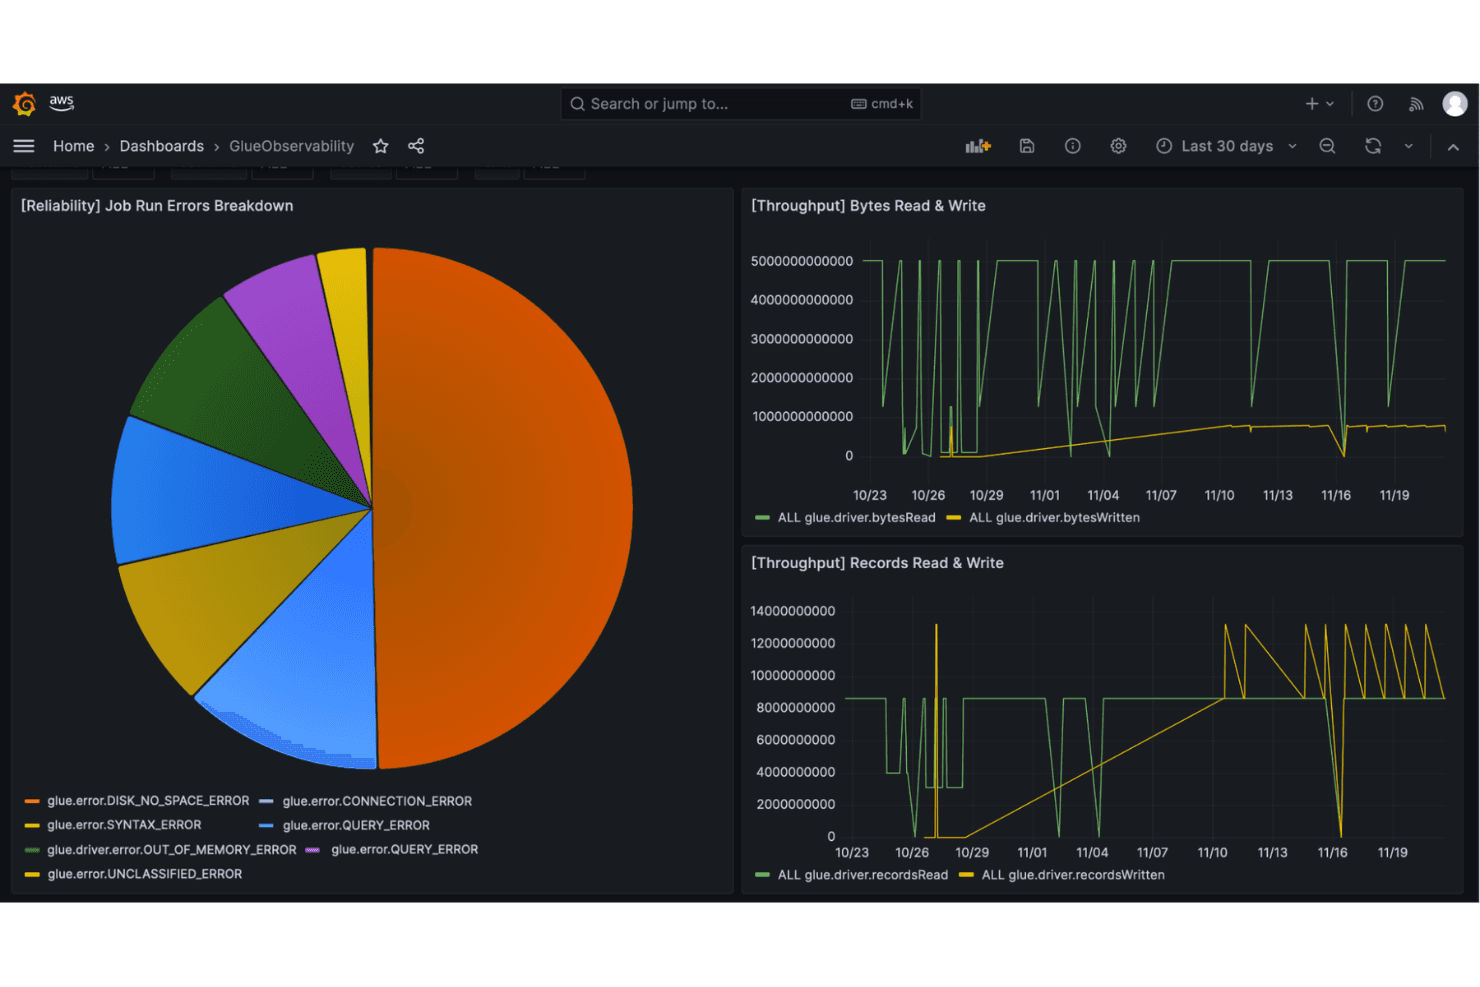
AWS Glue job observability dashboard showing run error breakdown and read/write throughput over 30 days. AWS Glue is Amazon's serverless data integration service that appeals to data engineers already embedded in the AWS ecosystem who need to automate ETL pipelines, orchestrate complex workflows, and connect to a wide range of data sources without managing infrastructure.
Who Is AWS Glue Best For?
AWS Glue is a strong fit for data engineering teams already running workloads on AWS who need serverless ETL automation without managing Spark infrastructure.
Why I Picked AWS Glue
I've included AWS Glue in my top picks because it's the strongest serverless ETL option for data engineering teams already running workloads on AWS. I love how Glue workflows let you coordinate jobs, crawlers, and triggers with schedule-, event-, or on-demand-based execution, so recurring pipeline automation requires almost no infrastructure oversight. Visual ETL authoring in AWS Glue Studio generates Spark code automatically, and zero-ETL integrations move data from sources like DynamoDB or Salesforce directly into Redshift without custom pipeline code.
AWS Glue Key Features
- Git-based version control: Syncs visual and script jobs with GitHub, GitLab, Bitbucket, and AWS CodeCommit using branch-based pull and push workflows.
- Glue Data Quality rules: Applies a library of 25+ DQDL rules to datasets and in-pipeline checks, with the option to halt a pipeline when quality thresholds are breached.
- Amazon Q data integration: Generates customizable Apache Spark ETL code from natural-language descriptions of your transformation requirements.
- Data Catalog with crawlers: Automatically discovers source schemas and stores table definitions, job definitions, and schema-version history across connected data sources.
AWS Glue Integrations
AWS Glue offers native integrations with Amazon S3, Amazon Redshift, Snowflake, Google BigQuery, GitHub, GitLab, Bitbucket, and AWS CodeCommit, with more than 100 documented data sources. It also supports Marketplace connectors and an AWS Glue Web API for custom integrations.
Pros and Cons
Pros:
- Discovers schemas and catalogs datasets automatically
- Flags poor data quality within pipelines
- Automates job, crawler, and trigger dependencies
Cons:
- Git excludes notebooks and needs repeated setup
- Spark SQL lacks dbt-style modular modeling
Learn more about AWS Glue: Best for enterprise-grade workload scalability
- 30-day free trial + demo available
- Pricing upon request
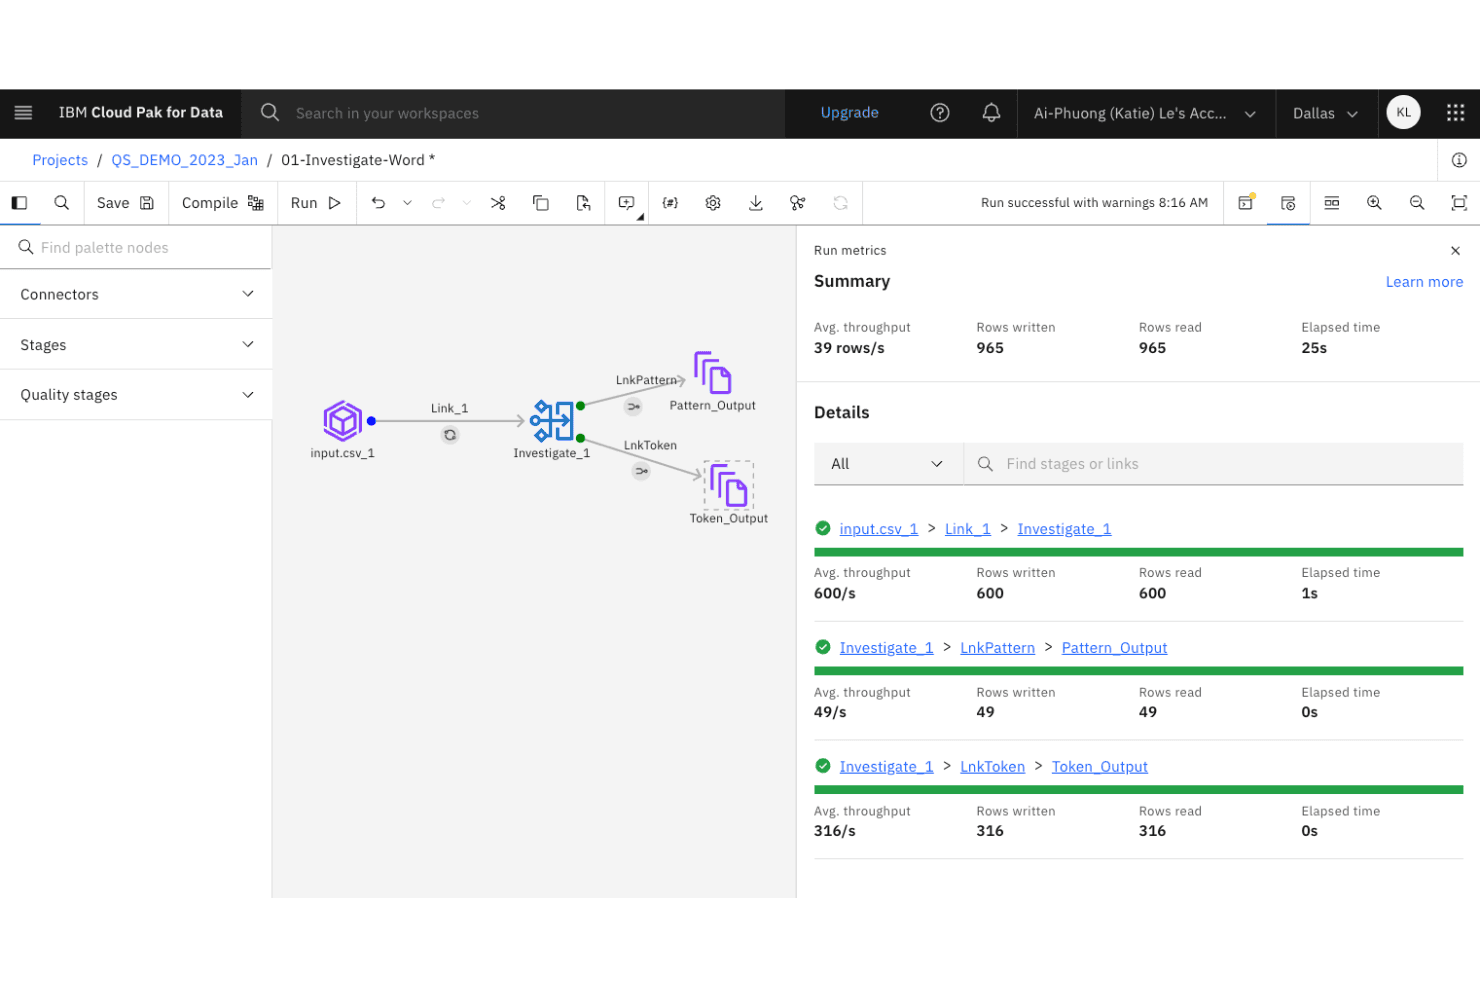
IBM DataStage job canvas with an Investigate stage and run metrics showing rows read and written. IBM watsonx.data integration (formerly IBM DataStage) is an enterprise data integration platform built for data engineers who need to move, transform, and prepare structured and unstructured data across batch, streaming, and replication pipelines in hybrid and multicloud environments.
Who Is IBM DataStage Best For?
IBM watsonx.data integration suits large enterprises running high-volume ETL/ELT workloads across hybrid and multicloud environments who need a proven, scalable pipeline platform.
Why I Picked IBM DataStage
I picked IBM DataStage as one of the best because its parallel processing engine splits large batch workloads into concurrent operations, letting data engineering teams handle enterprise-scale ETL/ELT volumes without redesigning pipelines as data grows. I also appreciate the autoscaling support via OpenShift Horizontal Pod Autoscaler, which means capacity adjusts to workload demand rather than requiring manual intervention during peak processing windows. The remote engine architecture separates the design control plane from execution, so pipelines run where the data actually lives across hybrid and multicloud environments.
IBM DataStage Key Features
- Unified Python SDK: Author, manage, and execute both batch and real-time streaming pipelines in Python, with support for Git versioning and CI/CD automation.
- Data Observability alerts: Configure threshold-based alerts for job duration, job state, and pipeline metrics like rows read and written, with routing to Slack or PagerDuty.
- Unstructured data processing: Ingest and transform unstructured files using drag-and-drop operators for text extraction, PII removal, chunking, and embedding generation.
- Multi-environment project propagation: Promote pipeline assets across development, testing, and production projects using
cpdctlor thedsjobCLI.
IBM DataStage Integrations
IBM DataStage has documented connections to Amazon Redshift, Google BigQuery, Snowflake, IBM watsonx.data Presto, Apache Flink on Confluent Platform, LangChain, and Milvus. It also provides APIs and a Python SDK for custom integrations.
Pros and Cons
Pros:
- Python pipelines support Git-based promotion
- Visual ETL spans batch and streaming
- Reviewers praise parallel processing at scale
Cons:
- Reviewers report proprietary logic migration is difficult
- No SQL-native modeling for dbt workflows
Learn more about IBM DataStage: Best for low-code pipeline building
- Free trial + demo available
- Pricing upon request
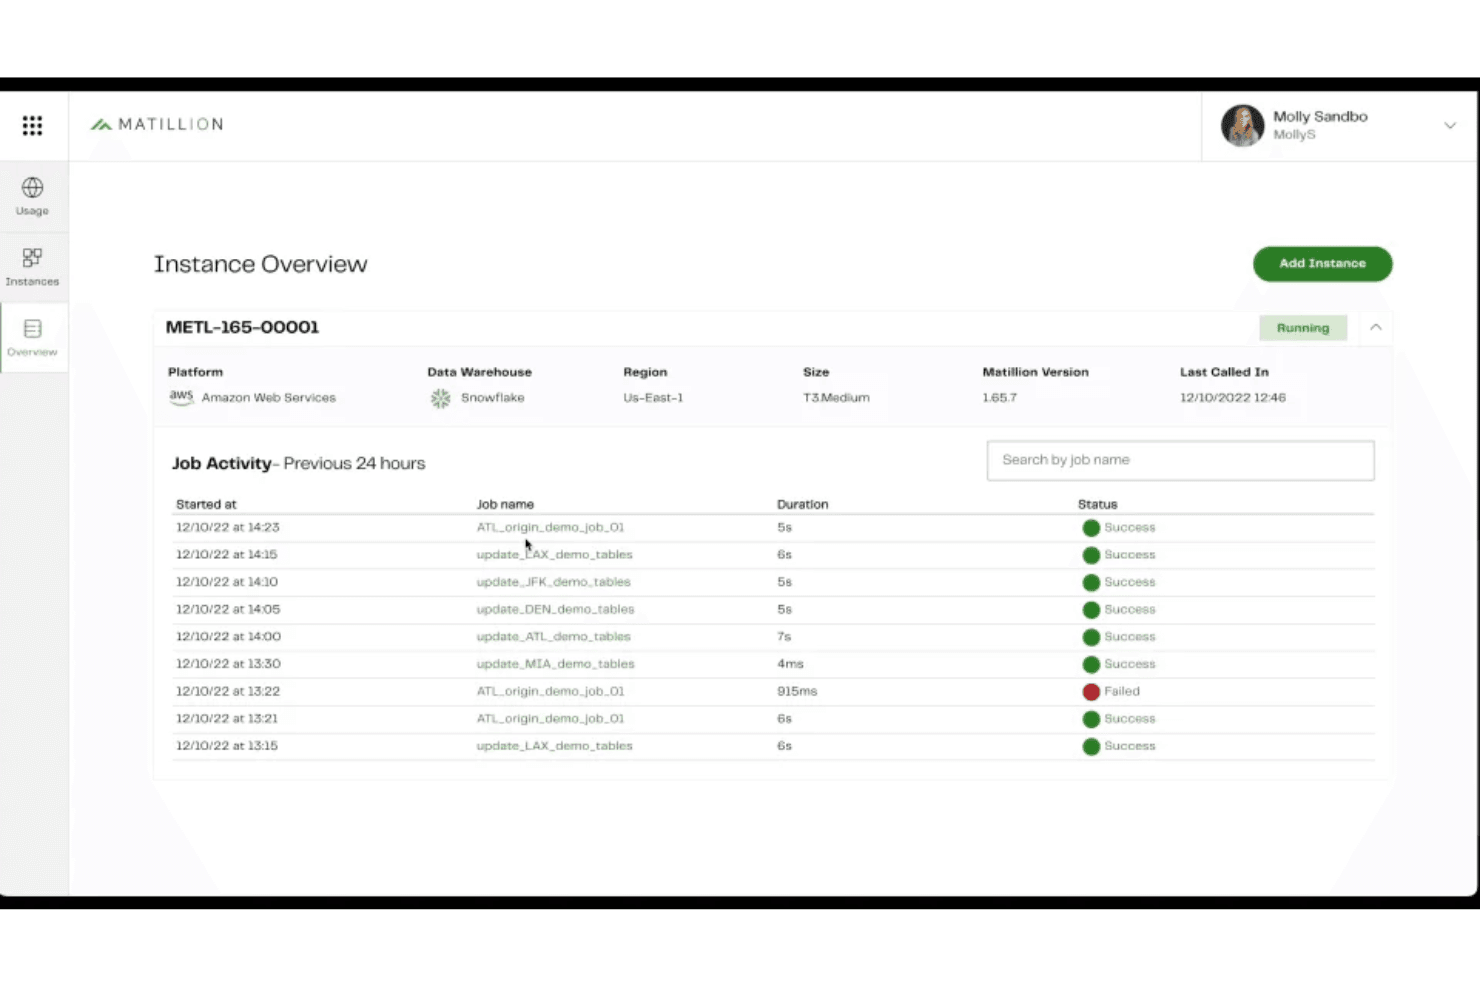
Matillion's Instance Overview tracks running instances and recent job activity, with status for each pipeline run. Matillion ETL is a cloud-based data integration platform that lets data and analytics teams load, transform, and orchestrate pipelines using a visual drag-and-drop interface alongside SQL and Python, making it a practical fit for teams that find dbt's code-first approach too steep a climb.
Who Is Matillion Best For?
Matillion ETL is a strong fit for BI and analytics teams that want to build and automate data pipelines without writing code from scratch.
Why I Picked Matillion
I picked Matillion as one of the best dbt alternatives because its visual drag-and-drop pipeline builder lets BI and analytics teams build transformation logic without writing SQL from scratch. I particularly like how you can build a complete ELT job using push-down components directly against Snowflake, Redshift, or BigQuery, then drop in a dbt Core command step if you need model-layer logic. The visual job canvas also generates documentation automatically, which removes a step that code-first teams often skip.
Matillion ETL Key Features
- Push-down SQL transformations: Runs transformation logic directly inside your cloud data platform—Snowflake, Redshift, BigQuery, or Azure Synapse—rather than moving data out for processing.
- Built-in scheduler: Automates orchestration jobs at predefined intervals, with per-schedule configuration for project version, environment, and timezone.
- Reverse ETL output components: Pushes transformed warehouse data back to operational systems like Salesforce, Intercom, and Oracle using native output connector components.
- REST API: Exposes a v1 API supporting GET, POST, and DELETE operations so you can trigger and manage jobs programmatically from external tools or scripts.
Matillion Integrations
Matillion offers 80+ out-of-the-box connectors, including Snowflake, Databricks, Amazon Redshift, Google BigQuery, Azure Synapse, Salesforce, Intercom, and Oracle. It supports GitHub, AWS CodeCommit, and Bitbucket repositories, plus a REST API for custom integrations.
Pros and Cons
Pros:
- One canvas combines loading and orchestration
- Pushdown processing keeps work in the warehouse
- Visual jobs make transformations easier to inspect
Cons:
- Data checks require user-built logic
- Git workflows lack documented CI/CD promotion
Learn more about Matillion: Best for dynamic data validation rules
- Free demo available
- Pricing upon request
Visit WebsiteCustomer Rating:4.9/5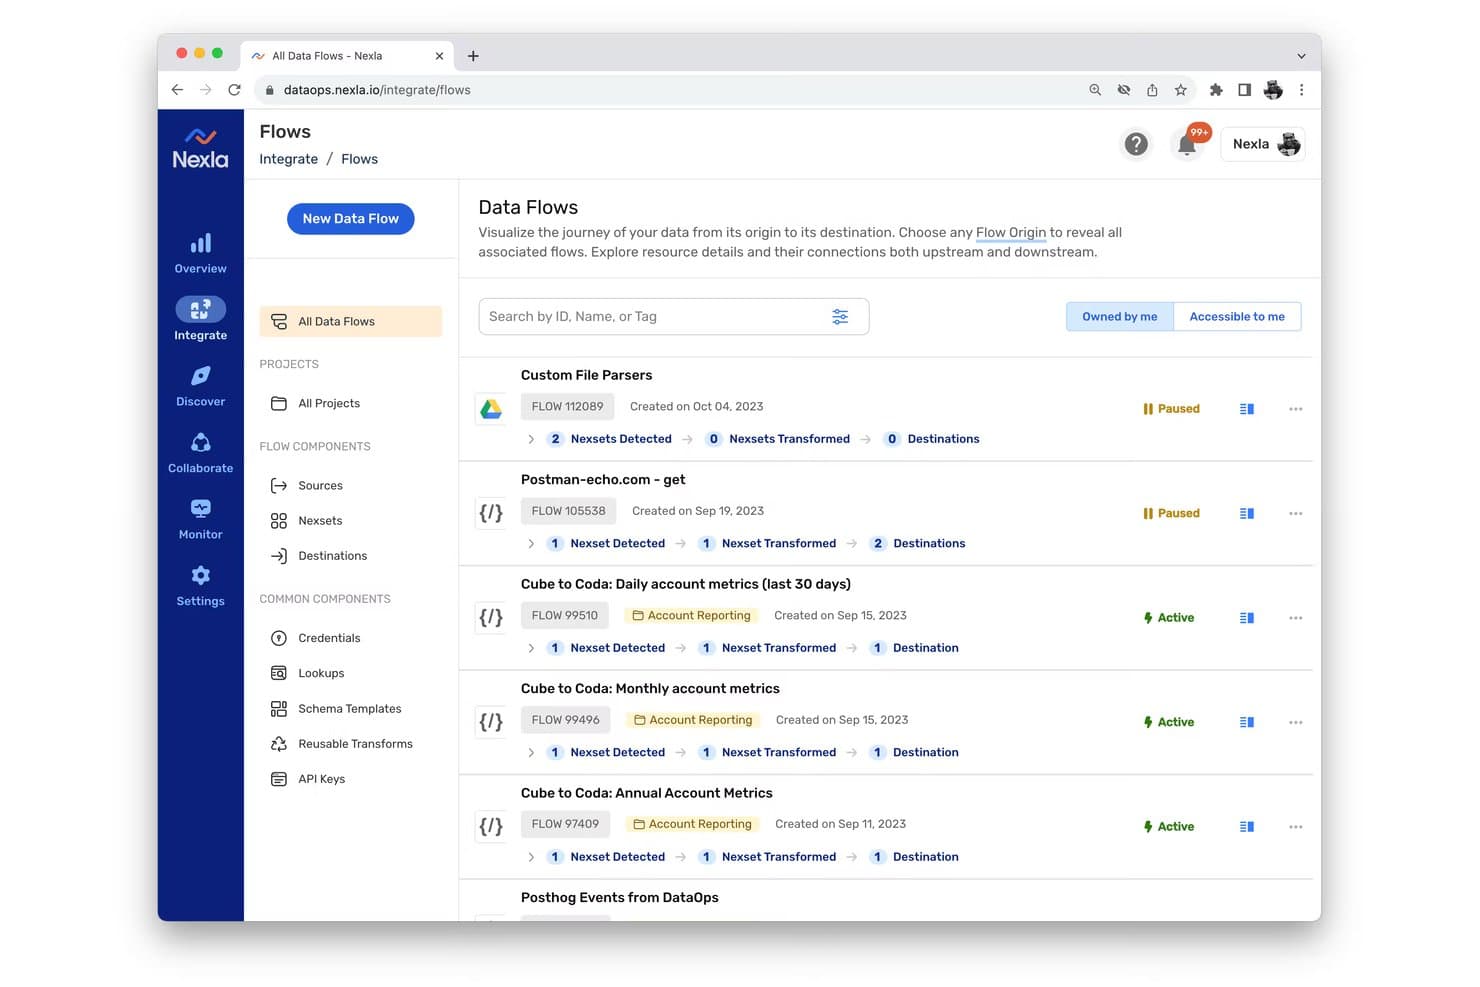
Nexla's redesigned Integrate section lists data flows with their status, sources, transforms, and destinations. Nexla is a data integration platform built for data engineers who need to connect, transform, and govern data across a wide range of sources—handling ETL, CDC, streaming, and API pipelines while applying validation and lineage tracking before data ever reaches its destination.
Who Is Nexla Best For?
Nexla is a strong fit for data engineers at enterprises managing complex, multi-source pipelines who need to validate, govern, and deliver data before it reaches downstream systems.
Why I Picked Nexla
I've included Nexla in my top picks because its dynamic data validation rules give data engineers a level of control over incoming data that most pipeline tools don't match. You can define record-level rules checking field existence, regex patterns, data types, and allowed values, and when schema drift happens mid-pipeline, Nexla detects it automatically and routes problem records to an error quarantine with full diagnostics. I especially like that validation runs before data lands at the destination, so bad records don't silently corrupt downstream datasets.
Nexla Key Features
- No-code data preparation functions: An Excel-like function library lets you filter, map, join, and reshape records without writing custom code.
- Automated error quarantine: Failed records are automatically isolated with full per-record diagnostics so you can inspect and resolve issues without manually hunting through logs.
- CLI-based flow import and export: Flow specifications can be exported to JSON and imported into separate accounts or environments, supporting migration, versioning, and development-to-production promotion.
- Custom Python and JavaScript transforms: A full IDE with a test harness lets you write, test, and share reusable custom transformation logic beyond what no-code functions cover.
Nexla Integrations
Nexla provides 1,000+ native connectors, including dbt, Snowflake, Google BigQuery, Databricks, Amazon Redshift, and Teradata. It also offers REST, SOAP, Data, Sync, and Admin APIs for custom integrations.
Pros and Cons
Pros:
- No-code transforms pair with reusable scripts
- Reviewers praise alerts for pipeline problems
- Record-level rules catch schema drift early
Cons:
- No native Git branching or CI/CD
- No reusable SQL modeling framework
Learn more about Nexla: Best for collaborative notebook-based analytics
- Two-week free trial + free demo available
- Pricing upon request
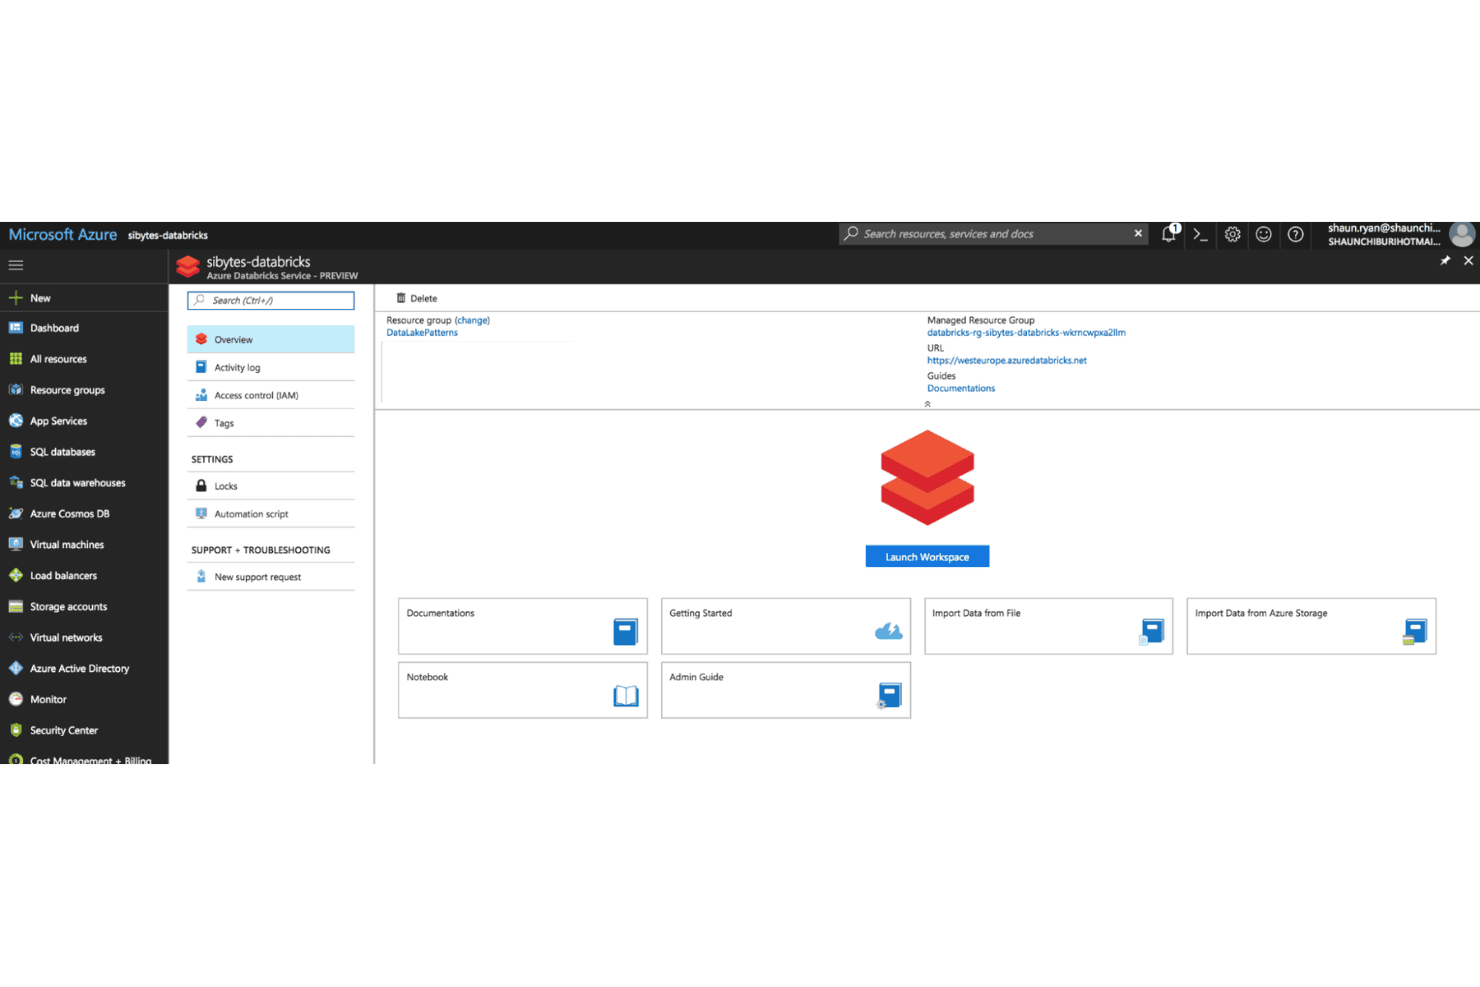
The Azure Databricks service overview in the Azure portal, with the Launch Workspace button to open the workspace. Azure Databricks is a lakehouse platform jointly built by Databricks and Microsoft that brings data engineering, SQL transformation, and collaborative notebook-based analytics together in one Azure-native environment.
Who Is Azure Databricks Best For?
Azure Databricks is a strong fit for data engineering teams already embedded in the Microsoft Azure ecosystem who need SQL, Python, and visual workflows on a single lakehouse platform.
Why I Picked Azure Databricks
I've included Azure Databricks in my top picks because its collaborative notebook environment lets data engineers and analysts work in SQL, Python, or a visual canvas without ever leaving the platform. I particularly like Lakeflow Designer, which generates Git-versionable code from drag-and-drop transformations, so your pipeline logic stays auditable and schedulable from day one. Unity Catalog then ties it together with automatic column-level lineage across every query your team runs.
Azure Databricks Key Features
- Pipeline expectations: Define SQL Boolean constraints on streaming tables and materialized views to retain, drop, or fail records that violate data quality rules.
- Unity Catalog lineage: Automatically captures column-level lineage across all Databricks queries and aggregates it across workspaces for upstream and downstream impact analysis.
- Lakeflow Jobs orchestration: Builds DAG-based workflows with event-triggered scheduling, task dependencies, conditional branching, retries, and run notifications.
- Lakeflow Connect ingestion: Provides 100+ built-in connectors for enterprise apps, databases, and file sources with serverless, incrementally-loaded pipelines governed by Unity Catalog.
Azure Databricks Integrations
Azure Databricks offers 100+ built-in Lakeflow Connect connectors, including Salesforce, SQL Server, Google Analytics, ServiceNow, SharePoint, Workday, Amazon S3, and Google Cloud Storage. It also integrates natively with Microsoft Azure services and provides REST, SDK, and CLI APIs for custom connections.
Pros and Cons
Pros:
- Visual pipelines generate Git-versionable code
- SQL and PySpark share transformation workflows
- Collaborative notebooks unite engineering and analytics
Cons:
- Pipeline expectations support limited object types
- Compute costs can become unpredictable
Learn more about Azure Databricks: Best for column-level data lineage visualization
- Free plan available
- From $150/user/month (billed annually)
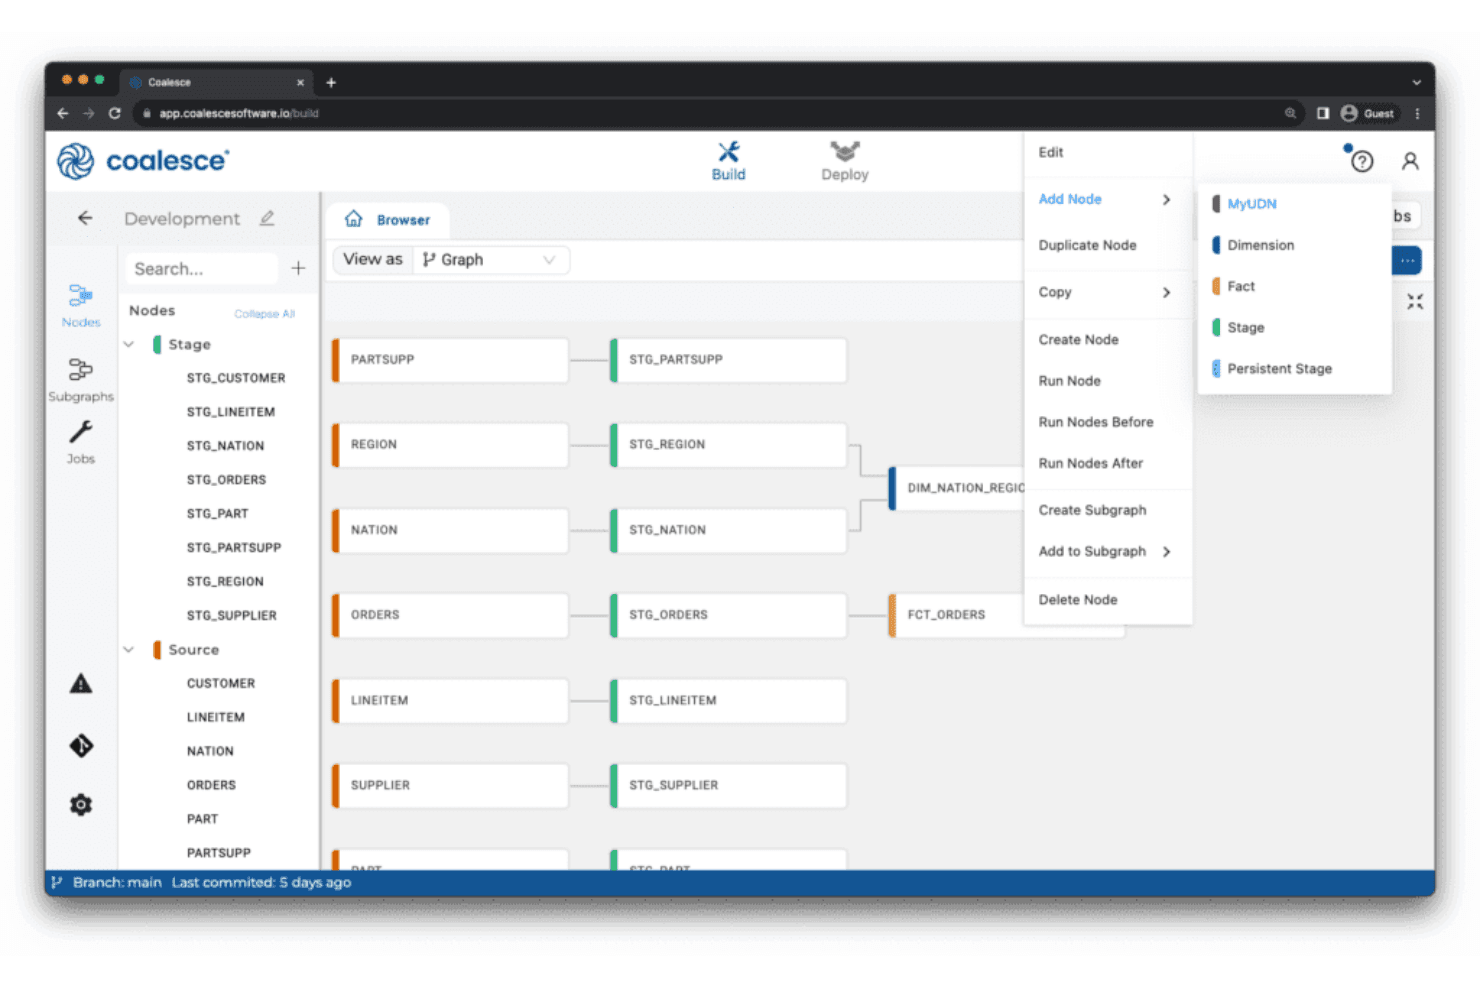
Coalesce's Build canvas maps source nodes through stage tables to dimension and fact nodes. Coalesce is a data transformation platform built for analytics engineers and data teams who want a visual, low-code alternative to pure SQL development—combining pipeline building, data cataloging, and quality monitoring in a single environment.
Who Is Coalesce Best For?
Coalesce is a strong fit for analytics engineering teams that need to trace data changes at the column level across pipelines and BI tools.
Why I Picked Coalesce
I picked Coalesce as one of the best because column-level lineage is where it genuinely earns its spot. When a column gets added or removed upstream, Coalesce propagates that change through downstream nodes automatically. I also rely on its Catalog to trace a data journey from a raw warehouse table all the way to a Power BI dashboard, field by field, which makes impact analysis something I can actually do in minutes rather than hours.
Coalesce Key Features
- Git-backed workspace: Store all pipeline files in a connected Git repository with support for GitHub, Bitbucket, GitLab, and Azure DevOps Git.
- Node Types and reusable patterns: Define standardized building blocks that control how nodes produce DDL, DML, and tests across pipelines.
- Automated anomaly detection: Monitor schema, volume, freshness, and distribution changes with lineage-aware alerting and built-in incident workflows.
- SQL migration with Copilot: Convert stored procedures, CTE-based scripts, compiled dbt SQL, and legacy ETL SQL into Coalesce nodes through a guided migration workflow.
Coalesce Integrations
Coalesce offers native integrations with Snowflake, Databricks, BigQuery, Amazon Redshift, Microsoft Fabric, dbt, Apache Airflow, Power BI, Tableau, and Looker. Git-backed workflows support GitHub, GitLab, Bitbucket, and Azure DevOps Git, with API, MCP, and CLI access for custom workflows.
Pros and Cons
Pros:
- Built-in checks flag schema and freshness anomalies
- Reusable nodes standardize visual SQL pipelines
- Column-level lineage traces downstream impact
Cons:
- Large graphs can feel cluttered and slow
- Existing dbt projects need manual SQL conversion
Learn more about Coalesce: Best for version-controlled SQL workflows
- Free plan available
- Pricing upon request
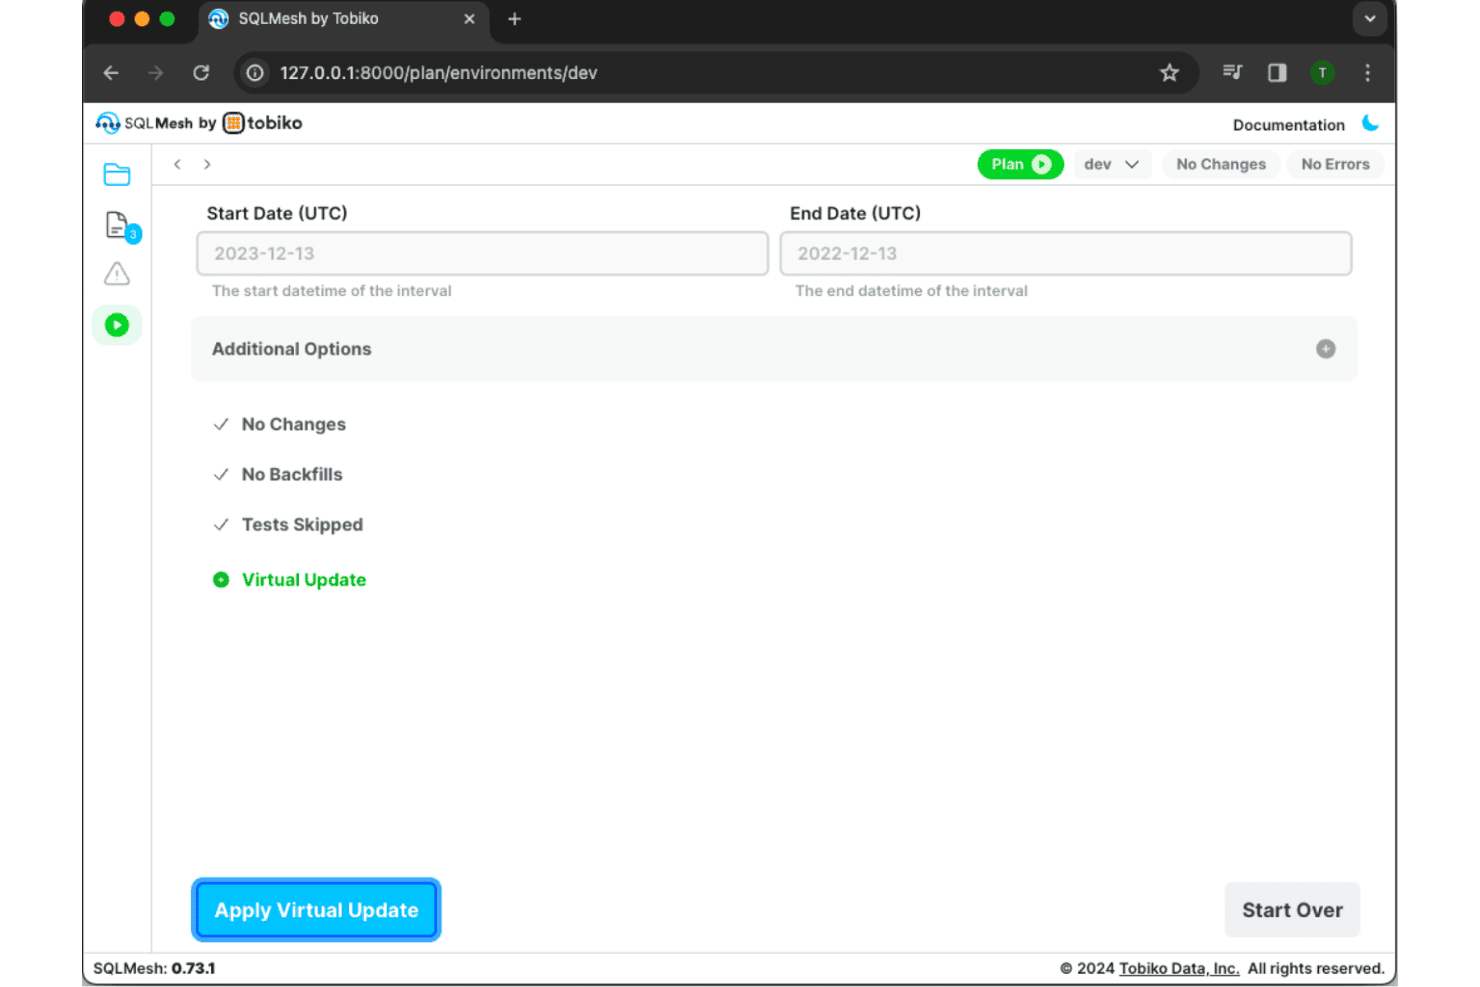
SQLMesh's plan view for the dev environment, where teams review changes and apply virtual updates. SQLMesh is an open-source data transformation framework that lets data engineers build, test, and deploy SQL and Python models with isolated virtual environments, automatic column-level lineage, and a plan-before-apply workflow that shows exactly what changes before anything runs in the warehouse.
Who Is SQLMesh Best For?
SQLMesh is a strong fit for data engineers who want a code-first transformation framework with built-in environment isolation and a plan-before-apply review workflow.
Why I Picked SQLMesh
I picked SQLMesh as one of the best because its plan-before-apply workflow genuinely changes how version-controlled SQL development feels. Before anything runs in the warehouse, I can see exactly which models are affected by a change and trace that impact down to the column level, automatically, with no manual annotation. That kind of built-in change visibility, paired with virtual development environments that isolate work without duplicating data, is what makes SQLMesh stand out for version-controlled SQL workflows specifically.
SQLMesh Key Features
- SQL dialect transpilation: SQLMesh automatically converts SQL written in one dialect into the syntax required by your target execution engine before any query runs.
- Multiple model kinds: Define view, full, incremental, seed, external, and SCD Type 2 models to match how each dataset needs to be materialized.
- Unit testing framework: Write unit tests against individual models or top-level CTEs using YAML, CSV, or SQL-generated inputs to validate outputs before deployment.
- GitHub Actions CI/CD bot: Automate project checks, pull request environment creation, and deployments directly through a native GitHub Actions integration.
SQLMesh Integrations
SQLMesh supports 16 native execution engines, including BigQuery, Snowflake, Databricks, Spark, Postgres, Redshift, Trino, and DuckDB. It also integrates with dbt, GitHub Actions, dlt, and Airflow, with Python API, CLI, and notebook interfaces.
Pros and Cons
Pros:
- Automatic column lineage reduces manual annotations
- Virtual environments avoid duplicate development tables
- Plan previews expose downstream change impact
Cons:
- dbt migrations can require incremental model adjustments
- Scheduler needs an external periodic trigger
Learn more about SQLMesh: Best for managed development environments
- 14-day free trial + free demo available
- Pricing upon request
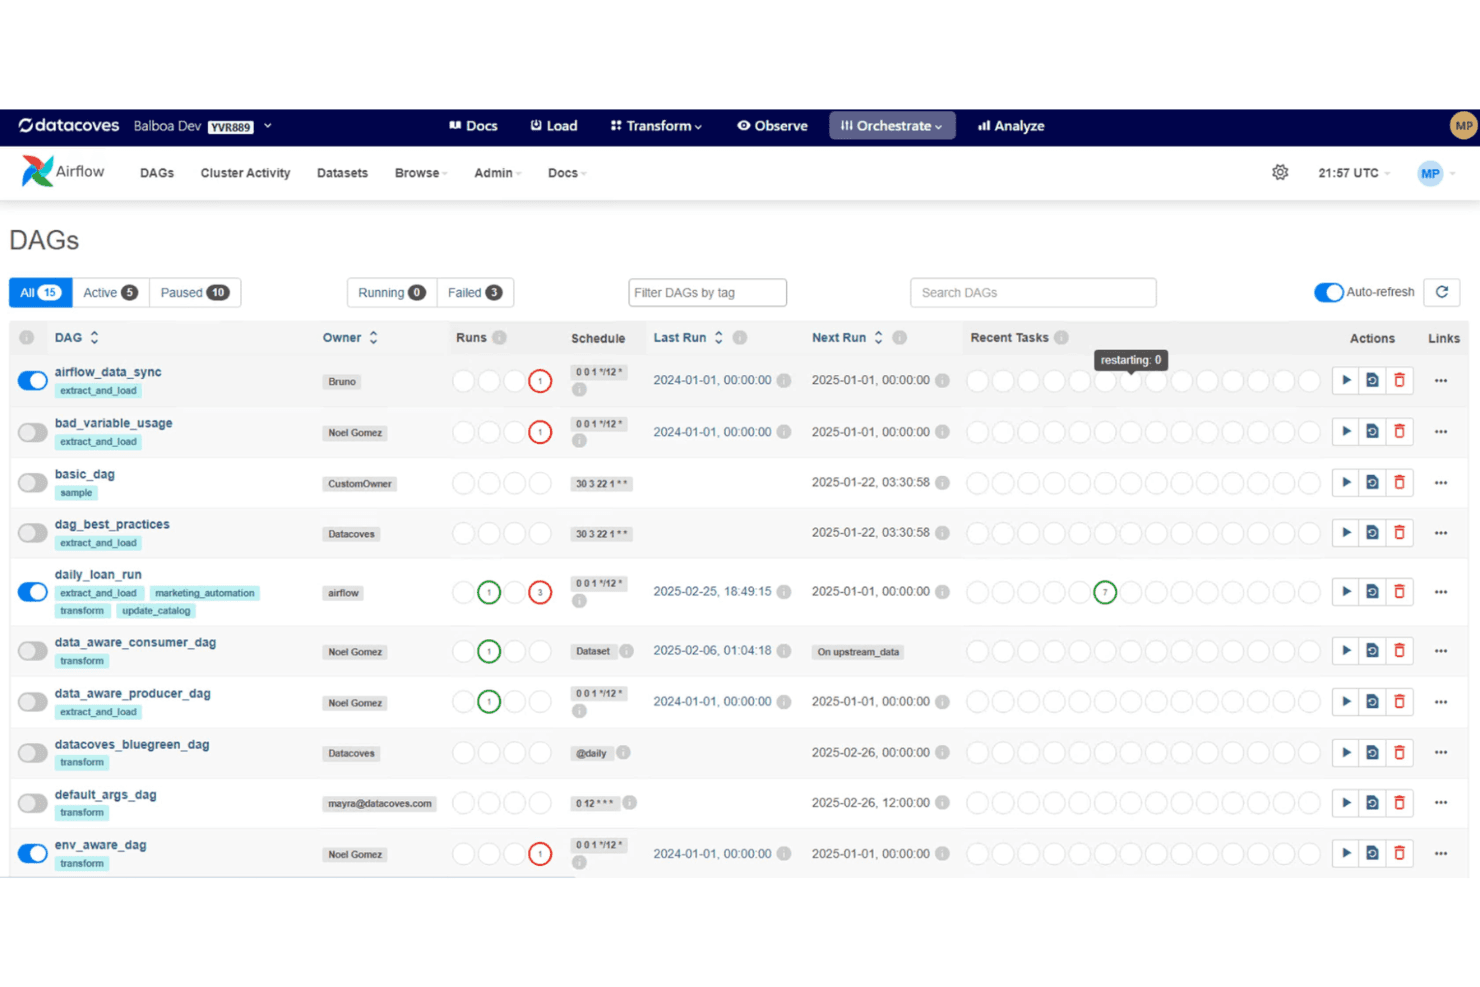
Datacoves' Orchestrate module, showing Airflow DAG schedules, run status, and task history in one view. Datacoves is a managed dbt and Airflow platform that gives data engineers and analytics engineers a browser-based VS Code environment with built-in Git, CI/CD, and pipeline orchestration—removing the infrastructure overhead of running these tools yourself.
Who Is Datacoves Best For?
Datacoves is a strong fit for data engineering teams that want a fully managed dbt and Airflow environment without the overhead of building and maintaining that infrastructure themselves.
Why I Picked Datacoves
I've included Datacoves in my top picks because it's the only tool here that ships a fully managed, browser-based VS Code environment with dbt and Airflow already wired together. I like that every developer on the team gets a consistent workspace with Git, Python virtual environments, and the Datacoves Power User extension pre-configured, so there's no local setup drift. When a team pushes a new DAG, Airflow picks it up from Git within a minute, and the VS Code lineage panel shows upstream and downstream model dependencies right in the IDE.
Datacoves Key Features
- Layered modeling structure: Datacoves organizes dbt projects into Inlets, Bays, and Coves layers, separating raw transformations, reusable data products, and analytics-ready outputs.
- Managed Airbyte ingestion: Teams can run managed Airbyte directly within the platform or bring their own tools like Fivetran or dlt and trigger them through Airflow.
- dbt-coves project scaffold: A setup command generates a customizable repository structure with warehouse-specific adapters, CI/CD workflows, linting, test frameworks, and documentation standards.
- Managed DataHub catalog: Datacoves includes managed DataHub for metadata organization and data discoverability across the team's dbt projects.
Datacoves Integrations
Datacoves integrates with GitHub, GitLab, Bitbucket, Azure DevOps, Snowflake, BigQuery, Databricks, Redshift, DuckDB/MotherDuck, and Airbyte. It also supports Fivetran, Azure Data Factory, Amazon Glue, dlt, Streamsets, Informatica, and API integrations.
Pros and Cons
Pros:
- Model lineage visible inside VS Code
- Hands-on onboarding and troubleshooting support
- Consistent browser-based development environments
Cons:
- Some CI/CD workflows require extra implementation
- Airflow sandbox differs from production behavior
Learn more about Datacoves:
Andre alternativer til dbt
Her er noen flere alternativer til dbt som ikke kom med på kortlisten min, men som likevel er verdt å undersøke:
- 115XBest for multi-cloud data stack orchestration
- 12Snowflake Native AppsBest for in-platform data transformation
- 13Qlik Talend CloudBest for unified data integration and governance
- 14HevoBest for zero-maintenance data pipelines
- 15AirbyteBest for open-source connector extensibility
- 16EstuaryBest for real-time data streaming
- 17FivetranBest for automated schema migration
- 18Coupler.ioBest for direct integration with business apps
- 19DatameerBest for spreadsheet-style data modeling
- 20OrchestraBest for customizable workflow automation
- 21FMEBest for complex data transformation logic
How I Evaluate dbt Alternatives
I split my evaluation into core requirements every tool must meet—DAG-driven modeling, built-in testing, Git integration—and the differentiators that set the right choice apart for your stack.
Core Functionality (Table Stakes For This List)
When I'm selecting tools for my list, I rank each one on a scale from 0 (does not offer the functionality) to 5 (excels in this area) for each core functionality listed below. Then, I calculate the tool's total score into a percentage. Each tool needs to achieve a minimum total score of 65% to be considered for inclusion.
- SQL-Based Data Transformations: I check whether each tool supports SQL and/or Python transformation logic that runs directly inside your warehouse, including templating and parameterization for reusable queries.
- Modular Model Development: Every tool should let you build interdependent models using refs or equivalent patterns, so your DAG reflects real dependencies—like staging, intermediate, and mart layers.
- Git-Based Version Control: I look for native Git integration that supports branching, pull requests, and CI/CD hooks, since analytics engineers need the same code review workflows they'd use in any software project.
- Automated Testing & Data Quality: Built-in test definitions matter here—things like uniqueness checks, not-null constraints, and custom assertions you can run against model outputs before they hit production.
- Lineage & Documentation Generation: The tool should auto-generate lineage graphs and searchable docs from your codebase, so you can trace how a revenue metric flows from raw ingestion through to a BI dashboard.
- Warehouse & Lakehouse Connectivity: I evaluate which platforms each tool connects to natively—Snowflake, BigQuery, Redshift, Databricks, Postgres—since gaps here can rule out an otherwise strong option for your stack.
Once I have a list of tools that meet this criteria, I consider what sets each platform apart.
Differentiating Factors (What Sets Vendors Apart)
Here's how I compare and contrast different vendors:
Standout Features
Native orchestration is a big differentiator—tools that include built-in scheduling and retry logic save you from stitching together a separate Airflow or Dagster setup just to run your models on a cadence. I also evaluate whether a tool offers a semantic layer, since defining metrics like MRR or churn rate once and exposing them consistently to Looker, Tableau, or Power BI cuts down on conflicting numbers across teams. A visual pipeline builder matters too, especially for teams where analysts need to contribute transformations without writing raw SQL.
Beyond Features
Pricing transparency matters when comparing dbt alternatives—some charge per seat, others by compute, and the difference shapes your total cost as the team scales. I also evaluate ecosystem fit, specifically whether a tool connects to your existing ingestion layer (Fivetran, Airbyte) and BI tools without custom glue code. Deployment flexibility is another key factor, since teams in regulated environments often need VPC or self-hosted options rather than a shared SaaS instance.
Hvorfor se etter et alternativ til dbt?
Selv om dbt er et godt valg av verktøy for analyseutvikling, finnes det flere grunner til at noen brukere ser etter alternative løsninger. Det kan hende du ser etter et alternativ til dbt fordi …
- Du trenger en kodefri eller lavkodet arbeidsflytbygger for analyse
- Teamet ditt mangler avanserte SQL- eller ingeniørferdigheter
- Du ønsker innebygde verktøy for maskinlæring eller prediktiv analyse
- Du trenger sanntids- eller datastrømsbehandling
- Du trenger mer detaljert dataopphav og revisjonsspor
- Organisasjonen din foretrekker et visuelt grensesnitt for utforming av datapipelines
Hvis noe av dette høres kjent ut, har du kommet til rett sted. Listen min inneholder flere alternativer for verktøy innen analyseutvikling som passer bedre for team som møter disse utfordringene med dbt og ser etter alternative løsninger.
Viktige funksjoner i dbt
Her er noen av de viktigste funksjonene i dbt, som kan hjelpe deg med å sammenligne hva alternative løsninger tilbyr:
- SQL-baserte datatransformasjoner og datamodellering
- Versjonskontrollintegrasjon med Git
- Automatisert testing og kontroller av datakvalitet
- Modulær prosjektstruktur for gjenbrukbar kode
- Generering av dokumentasjon for modeller og arbeidsflyter
- Avhengighetsstyring og visualisering av DAG-er
- Støtte for de viktigste skybaserte datavarehusene
- Inkrementell modellbygging for effektiv behandling
- Kommandolinjegrensesnitt og API-tilgang
- Miljøstyring for utvikling og produksjon